Operations | Monitoring | ITSM | DevOps | Cloud

Where Jev fits in ops

If you're using agents and MCPs to get a better understanding of your environment or work through an investigation, you can get a lot of useful information back. You can pull logs, look at recent changes, and check how services are configured, but you're still the one deciding what to do with all of it. That part of the process still lives in your head. To see where Jev might fit, look at decisions your team already makes and work backwards from them.
How to Monitor Database Backups and Get Alerted When One Fails

To monitor a database backup, make the backup script check its own output (exit code, file size, a table you know must be there) and ping a heartbeat URL only when all of it passed. If that ping does not arrive on schedule, you get an alert. A backup that failed, wrote an empty file, hung, or never started all look the same from the outside: no success ping.

How to Monitor Celery Beat and Catch Missed Periodic Tasks

To monitor Celery beat, give each periodic task its own heartbeat URL and ping it from the worker when the task succeeds, with a task_success signal handler. If beat is down, the message sits in a queue no worker reads, or the task raises, the ping does not arrive and you get an alert. The trap is that beat only publishes messages: its log prints Sending due task on schedule whether or not anything ever runs the task.

7 Best Network Sniffing Tools for 2026

Ever wondered what is actually using your network when it suddenly slows down? It could be a device sending too much data, a backup running at the wrong time, or an application taking too long to respond. Without visibility into network traffic, finding the real cause can take hours. That’s where network sniffing tools can help. They let you inspect network traffic, capture packets, and see what is happening between devices, servers, and applications.

7 Best SQL Server Monitoring Tools for 2026

A slow query can affect an application before the database team knows what is causing it. A blocked session, failed job, or growing database file can create more problems if no one spots it early. That’s where SQL Server monitoring tools come in. They help you track database performance, find slow queries, monitor waits and locks, and see what changed before a problem occurred.

Manage your OpenTelemetry Collectors with Fleet Management in Grafana Cloud

If you’ve built your telemetry pipelines around OpenTelemetry Collectors, you’ve already invested in a collector distribution, YAML configuration, and a deployment model that fits your infrastructure. As that deployment grows, managing it means keeping shared configuration consistent, accommodating different workloads, and understanding whether your collectors are healthy. Fleet Management in Grafana Cloud brings those tasks together in one place.

Debug Production at the Speed of AI

Your coding agent can debug production issues now. Yes… Not just “help you debug.” Actually run the investigation… FOR YOU! In this new era of agentic development, speed matters. And in the old days (you know… last week or so) we used to investigate production bugs ourselves. Manually. Like humans. But for a lot of incidents, we don’t need to do all of that anymore.

Searching Sentry Logs with Regex

We use Sentry's new Regex search for Logs to hunt for non-obvious bugs in our app. What do you do when traces show that Postgres jobs are backing up? Logs are trace-connected, so by looking at one of the affected traces, we can see all of the logs on that trace. In there, we can see Postgres has logged that it acquired a lock only after a long wait. Using regex, we can find all of these logs that describe acquiring a lock after a 10-second-plus wait. That narrows our search from thousands or hundreds of logs down to about a dozen.

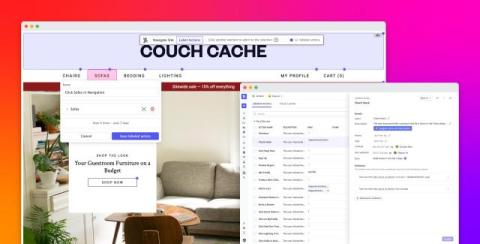
Define user actions on your web app with visual labeling in Product Analytics

Adding or renaming a product event has traditionally meant creating an engineering ticket. Datadog Product Analytics uses the same SDKs and configuration as Real User Monitoring (RUM), and those SDKs autocapture actions such as clicks and taps. But an automatically generated action name describes the element rather than the user intent behind it.

Log in, look around, level up: Building a trial people want to explore

We turned the mic around for this episode, with Zoe Hawkins interviewing Adam White and Jake Lee about Sumo Logic’s redesigned free trial. The new 14-day sandbox comes preloaded with realistic data feeds, Cloud SIEM, and our AI agents, so no one has to build collectors or open tickets before finding out whether the platform fits. Adam and Jake walk through the guided “choose your own adventure” paths, the broad, open-ended questions that bring out the best in Mobot, and how the trial will keep pace with new releases.

We Stuck Minecraft on a Kubernetes Cluster and Observed it with Open Source

Why did we do this? Not important: jump to 1:31 to see the Pis. TL;DR: We stuck Minecraft on kubernetes running on 4 Raspberry Pis in a 3D-Printed case, and monitored it with open source observability. Huge thanks to Percona DBA Ivan Zaitsev for putting the demo together for Percona University, Montevideo. Coroot automatically collects and visualizes all your telemetry data: logs, metrics, traces, profiles, and a complete map of your services. With the complete context of eBPF, it can diagnose the exact cause of an incident in seconds, and show you the exact commands to fix it.

Reducing Android scope-sync overhead in Sentry Flutter

Our SDK adds work to the app that installs it. It records recent app activity as breadcrumbs and keeps user information and other diagnostic data up to date. Changes to that information are called scope updates. On Android, we send those updates to a worker isolate, which passes them to the Sentry Android SDK. We found that the calling isolate and the worker both normalized the same data. The encoding step also created a JSON string and an extra byte buffer that we could avoid.

Run incident response in your FedRAMP High environment

Earlier this year, Datadog for Government achieved FedRAMP High certification, extending our GovCloud environment (US1-FED) to the federal government’s most sensitive civilian workloads. That certification now covers Datadog Incident Response, bringing paging, incident coordination, automation, and postmortem workflows into US1-FED. When a government system goes down, responders need to reach the right people, coordinate a fix, and keep stakeholders informed.

Generative AI in Banking: Balancing innovation, risk, and operational readiness

Generative AI (GenAI) is moving quickly into banking. According to a 2025 survey by McKinsey, 52% of financial institutions surveyed already consider GenAI a priority, while another 39% are interested but have not yet made it a top priority. As adoption grows, banks need to think carefully about what AI agents can access, which identities it uses, what actions it can take, and whether those activities can be traced when something goes wrong.

9 Best Help Desk Software for Small Business in 2026

Why is your network slow or failing even when your devices seem to be working? Finding the cause of a network problem can take time. You may need to check packet loss, trace the network path, find a busy link, or see why an application is not connecting. A simple ping test can tell you whether a device responds, but it cannot always show what is causing the problem. Network diagnostic tools help you narrow down the cause by checking devices, ports, routes, packets, traffic, and link performance.
8 Best Network Diagnostic Tools for 2026

If your team manages a network across several offices and cloud systems, finding the cause of a slow or failed connection can take time. You may run into problems such as: As your network grows, a quick test from one computer may not show where the problem started or when it first appeared. Network diagnostic tools help you check devices, ports, routes, packets, and link performance.

Icinga Web Filter Syntax: Operators, Wildcards and Custom Variables

An Icinga Web filter is a chain of conditions, each one a column, an operator, and a value, combined with & and |. You type it into the search bar of Icinga DB Web, but the same syntax shows up in URLs, dashboards, role restrictions, and the event rules of Icinga Notifications Web. This post covers the whole thing: operators, wildcards, grouping, and filtering all the way down into arrays and dictionaries.

Manage synthetic checks at scale: Introducing folders in Grafana Cloud Synthetic Monitoring

As your use of Grafana Cloud Synthetic Monitoring grows, so does the number of checks you need to manage across services, environments, and teams. Eventually, a single flat list of checks becomes difficult to navigate, and even simple questions get harder to answer: Which checks belong to the payments team? Can I disable everything in staging during a maintenance window? Who should be able to edit the checks for this service?

OpenTelemetry Collector Configuration for LLM Observability

Your LLM application emits telemetry unlike anything else in your stack. Model calls, tool invocations, retrieval steps, and token usage arrive as spans whose attributes carry entire prompts and completions. That data is bulky, it's full of user content you may not be allowed to export, and depending on which instrumentation each service uses, the same fact can arrive under different attribute names.

Modernize Your Data Historian with InfluxDB

In this video, Dev Advocate Cole Bowden walks you through where traditional data historians fail, and why a dedicated time series database like InfluxDB can streamline your operations. With an AI-powered demo showcasing an automative plant's data, you'll see the value of InfluxDB and where it can power insights that Data Historians can't handle on their own.

Governing AI Agents From the Inside: What We Learned Building AgentIQ

When every employee is building AI agents, seeing what they did afterward isn't enough. AgentIQ's in-flow governance runs inside the agent's execution flow—pausing for human approval, enforcing policies by value, masking PII, and stopping runaway agents before costs spiral.

Seer Agent: Get Answers. Take Action.

This video walks through what it looks like to treat Sentry's Seer agent the way you already treat a chatbot, asking it plain language questions about your own production application. From Slack or inside your Sentry account, Seer Agent can answer questions with real context: the affected spans, the recent release, the likely cause. Seer doesn't stop at answering questions. Ask it to act on what it just told you and it completes that work inside Sentry, serving as an assistant to your projects, team workflows, and your future self.

AI Investigation for ITOps: Faster Root Cause with Edwin AI

AI investigation for IT operations finds the likely root cause of an incident and shows the evidence behind it. This video covers how deep AI investigation works for ITOps, SRE, and platform engineering teams using LogicMonitor's Edwin AI. Engineers lose time stitching together alerts, logs, and recent changes after an alert fires. Deep AI investigation hands that first pass to AI agents, so your team starts closer to the fix. Edwin AI, LogicMonitor's AI agent for ITOps, correlates alerts, identifies root causes, and recommends remediation.
Sponsored Post

Raygun APM Agent 3.1: async traces that stay with the right request

Raygun APM Agent 3.1 introduces more accurate asynchronous request tracing for Windows, Linux, and Azure App Service. Version 3.0 rebuilt the foundation of the Agent, profiler, installers, and release pipeline. Version 3.1 builds on that work with a focused improvement for ASP.NET Core: automatic request correlation that follows asynchronous execution without requiring developers to instrument their application. The result is a more accurate trace, with less duplication and a clearer view of the work performed for each web request.

Restoring Compliance After Missed SAP Patch Cycles

Avantra restores SAP compliance after missed patch cycles by measuring the real gap on every system, automating the catch-up in risk order, and monitoring continuously afterward. A missed cycle can leave SAP operations out of compliance or exposed to documented vulnerabilities, and until each system is assessed, the impact is unknown. Getting “back to good” requires three steps: The patching itself is rarely the hard part.

Unreal MCP now speaks Sentry

Setting up crash reporting is rarely the most exciting part of shipping a game. Paste a DSN, flip a few checkboxes in Project Settings, turn on symbol upload, package a build, crash it on purpose and check that the event shows up in Sentry… It’s not hard to do (and important), but it’s the kind of work you’d happily hand off to someone else. With Unreal Engine 5.8, that someone else can be your coding agent.

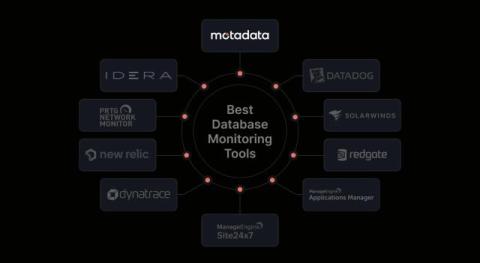
10 Best Database Monitoring Tools for 2026

If your company relies on multiple databases and applications, keeping track of database performance can become difficult. You may face challenges such as: As your database environment grows, identifying the cause of performance issues becomes harder without the right monitoring in place. I get why database monitoring tools have become an important part of managing database performance. They help you monitor database activity, spot performance issues, and find what is causing a slowdown.

How to Filter and Reduce AI Agent Telemetry with OpenTelemetry & Bindplane

Why is the telemetry AI agents generate so intimidating? If you turn on Claude Code’s internal telemetry it’ll throw a wall of text at you. And, it’s very expensive to store. But, the bigger issue is that you can’t make sense of it. Luckily it’s all OpenTelemetry native. That means you can configure it to send, transform, and store what you really need. Which raises the only question that matters. What do you actually need?

Beyond Traditional Observability: Turning Technical Insight into Operational Intelligence

Observability has become a central part of modern IT operations and for good reason. Metrics, logs and traces give technical teams detailed evidence about how applications, infrastructure and services are behaving. Such evidence helps them investigate performance degradation, identify abnormal behavior and understand what changed around the time an issue occurred.

How ScienceLogic Helps Federal Skylar One Customers Move to FIPS 140-3 Without Disrupting Operations

ScienceLogic provides federal Skylar One customers with a supported Oracle Linux 9 direction, deployment-specific migration workflows, validation gates, and clear ownership before Oracle Linux 8 is retired.

The Data Race That Wasn't a Bug (and the One That Was)

Imagine this: you are testing the performance of some part of your application. Everything is going smoothly, the numbers look good, and as a last check you turn on Go’s race detector. Then, out of nowhere, it prints a warning you didn’t expect: So you look at it. You look at it again, and again, and you think: “What the…?” The race is between your code and a goroutine you never started, somewhere deep inside net/http. You have no idea how that is possible, or why.

Azure in Bleemeo: your subscription next to your servers, with one read-only role

Most teams that run on Azure do not run only on Azure. There is a database on a VM nobody wants to move, a Kubernetes cluster somewhere else, a few servers in a rack, and a monitoring setup that grew around all of it. Azure Monitor sees the Azure part very well and nothing else, so the picture of an incident ends up split across two consoles, two alerting configurations and two sets of dashboards. Bleemeo now connects to Azure the same way it already connects to AWS.

Ship faster, improve reliability, and control CI costs with Datadog CI/CD Optimization

AI-assisted development can increase the rate at which teams produce code, but teams only realize those velocity gains if CI can keep pace. More pull requests (PRs) mean more builds, tests, and pipeline executions. Slow jobs leave developers and coding agents waiting for feedback, flaky failures consume time in reruns and investigations, and unnecessary test execution increases runner demand as delivery volume grows.

Observability vs Monitoring: Why Does IT Still Find Out After the Business Does?

✓ operational truth IT finds out late because traditional monitoring is built to detect what goes wrong, not what has quietly stopped happening. Closing that gap requires observability that validates business journeys end to end, detects missing activity, checks its own coverage, and predicts degradation before a threshold is ever crossed.

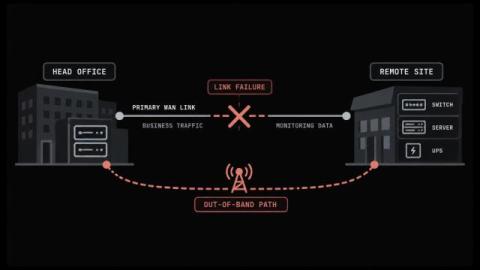
Remote Infrastructure Management: How to Run Sites With No IT Staff

Most IT teams now look after more sites than they have people to visit. Remote infrastructure management covers that gap, and it works differently from the IT infrastructure management you run inside a building where somebody can walk over and look at whatever broke. The technology rarely causes the trouble. Trouble starts when a site goes quiet and there's nobody standing there to look at it.

The Year-2 Price Cliff: What Your Observability Stack Really Costs Over 3 Years

I’m not the one whose phone lights up at 3 a.m. when production breaks. But I’ve spent years working alongside the engineers who are, and I’ve noticed that observability migrations happen for two reasons. Either engineering needed one, or, far more often, a quote landed that looked too good to refuse. The engineers rarely regret the first kind. The second kind they tell me about in year two, usually with a renewal notice in hand.
ISO 27001 Compliance: What Auditors Require and When You Need the Certificate

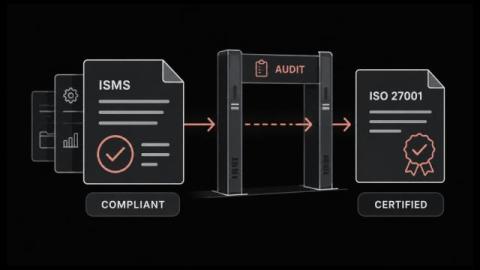
ISO 27001 compliance means running your information security the way ISO/IEC 27001 sets out. Most teams meet the standard when a customer sends over a security questionnaire. It lands as one more line on a cybersecurity compliance checklist. That framing hides the decision underneath it. You can follow the standard without ever being certified against it. The two routes cost very different amounts. In this blog, you will: You will finish able to decide whether you need the certificate, and what it takes.

How Honeycomb Private Cloud Drinks From the Fire Hose

Back in July, I wrote about how the Tenant team (the team behind Honeycomb Private Cloud (HPC)) has embraced the code review bottleneck to focus more of its work. One of the other challenges we have is that we're downstream of almost all the other teams at Honeycomb, meaning that we have to package up everyone's code and services, and how it gets provisioned! This is something impossible to handle through code review since there are so many engineers on other teams, and so few of us.

10 Best AI Help Desk Software for 2026

Are your support teams spending too much time handling tickets and answering repetitive questions? As support requests increase, teams spend more time reading conversations, assigning tickets, finding relevant information, and preparing replies. These tasks can take attention away from complex issues that require human support. AI help desk software can help reduce this workload. It can answer common questions, summarize tickets, suggest replies, route requests, and assist with support tasks.

Moving Mainframe Data to Snowflake and AWS Through Apache Kafka: Treehouse Software and meshIQ

Treehouse Dataflow Toolkit moves mainframe data from Db2, VSAM, and IMS through Apache Kafka pipelines into Snowflake and AWS targets. meshIQ keeps the streaming layer visible and stable. Together they give data science teams continuously updated enterprise data for AI and ML.

FastAPI 0.142 Turns On OpenTelemetry by Default. Here's What It Records.

FastAPI 0.142.0 ships with OpenTelemetry built in. Install fastapi, set one environment variable, and every request produces a trace, metrics, and error logs. No middleware, no instrumentation package, no code. That’s a big change for a framework most Python teams instrument by hand. It’s also easy to misread. The defaults record more than some teams expect in one place, and less than others assume in another. Here’s what you actually get.

The September 30, 2026 Railway Outage

Railway-hosted domains returned HTTP 404 to new connections in all four Railway regions on September 30, 2026, for about five minutes between roughly 07:35 and 07:40 UTC. This happened after a new version of Railway's routing service went live before the database schema change it depended on had been applied.

Turn Production Failures Into Test Datasets | SAO Dataset Curation

Your agent breaks in production. You fix it and move on. But the input that actually broke it is gone and two months later the same failure quietly comes back, because there was never anything to test against. That's not a debugging problem. It's a missing dataset. This demo turns low-scoring production traces into a regression suite you can run against every prompt and model change, without writing a single test case by hand.

Steer, Block and Audit Agent Behavior from One Place | SAO Agent Control Demo Cisco Agent Control

Most teams keep an agent from regressing by hardcoding checks into its logic, an if-statement here, a regex there. Every new rule then becomes a code change, a review, and a deploy, and the person who spots the problem in production is rarely the person who can ship the fix. Agent Control moves those rules out of the code and into one hub. Steer, block, and validate agent behavior in real time, with rules any team member can update without touching the codebase.

Block AI Agent Regressions Before They Ship | SAO Pre-Push Eval Gate Demo

Every engineering team has unit tests. They tell you the code still works. They tell you nothing about what the model started saying. This demo wires a single eval gate script into a git pre-push hook, so Splunk Agent Observability scores every agent's output before the push is allowed through. Luna, an on-premise small language model, runs as a synchronous judge against fixed thresholds. Fail one, and the push is blocked.

Who Built This Dashboard, and Are They Still Here?

You have lived it, no? When production is down, and you have that chart that says something really strange and peculiar, and nobody knows who did it or when. Production is bleeding. There is a spike on screen. And the chart answers everything except the question you actually have: who built this panel, what did they mean by it, and are they still here?

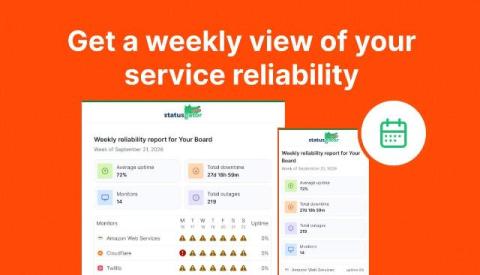
Get a weekly view of your service reliability

StatusGator already keeps you informed as outages happen with status change notifications and Early Warning Signals. Now, you can also get a simple summary of how your services performed over the past week. We’ve added Weekly Uptime Reports, delivered directly to your inbox. Each weekly report gives you an at-a-glance view of your StatusGator board, including: This makes it easy to review the week without digging through individual incidents or notification emails.

Seer, the Sentry MCP and CLI, or your own coding agent: where each one fits

I’ve been getting some version of this question a lot lately, mostly in our Seer preview webinars. Different audiences, same handful of questions: Worth answering all three in one place. Honestly, I needed to write this down for myself too. Things are moving fast around all of us and answers seem to get more nuanced by the week. This is an attempt to codify the difference: what each option is and when it makes sense to reach for one over the other.

Databricks' native monitoring resources

In the first part of this series, we cataloged key metrics for Databricks data engineering, analytics, and Model Serving workloads. In this post, we’ll discuss how to collect those metrics and other telemetry data from Databricks and Apache Spark, which powers Databricks under the hood. We’ll cover collecting and querying telemetry data via system tables, as well as the other primary sources of visibility into.

Monitor Databricks with Datadog

Earlier in this series, we covered key metrics for monitoring performance in Databricks and discussed Databricks’ native resources for accessing those metrics and other key observability data, such as logs and data lineage. In this post, we’ll cover using the Databricks integration to bring that data into Datadog and monitor your Databricks analytics and AI/ML workloads alongside the rest of your end-to-end data pipelines and distributed infrastructure. We’ll show you how to.

Prove Your SLAs: How Yext Ties Synthetic Monitoring to SLOs with Checkly (Live-Webinar)

Yext uses synthetic monitoring to prove and meet SLAs, by tying Checkly checks directly to SLOs and user-facing SLIs. Stefan (Developer Relations), Braxton (Solutions), and Shikhar (Engineering Productivity at Yext) cover the SLA/SLO/SLI basics, the math behind "all these nines", and how Yext turns those targets into concrete checks with monitoring as code.

Become a PowerPack Picasso: A Discussion About Skylar One Studio

If Sklyar One is your canvas, then Skylar One Studio is where you develop your art. In this session, we’ll dive into the latest tools that allow you to quickly and easily build new PowerPacks. You’ll learn how to build beautiful PowerPacks, without having deep Python knowledge, which work quickly, have great performance, are secure, and easy to support; all thanks to the extensibility of ScienceLogic tools using the latest and greatest innovations in content development. Your next masterpiece is at your fingertips!

Where do you see organizations hitting their limits?

In this clip, Virtana Chief Product Officer, Amit Rathi explains why more data does not automatically lead to better operations. As system complexity grows, organizations are collecting more telemetry than ever while struggling to turn it into actionable insights. At the same time, rising observability costs are forcing some teams to monitor only part of their environments. Watch the video to learn why intelligence, not just visibility, is becoming essential for modern IT operations.

NetScaler Console Indicators of Compromise Detection

On September 27, 2026, Citrix published a security bulletin covering eight new vulnerabilities in NetScaler ADC and NetScaler Gateway. Some of these vulnerabilities are critical and have already been exploited in the wild. Citrix released fixed NetScaler builds and recommends upgrading affected appliances as soon as possible. However, when a vulnerability is already being actively exploited, installing the update only solves part of the problem.

Azure Monitor pricing: What you pay vs. what you get

Azure Monitor doesn't have a price. It has a bill and those are very different. There's no plan tier to pick, monthly set fee, or simple number to sanity-check against your budget. Instead, you're charged across a handful of separate meters: log ingestion, log queries, retention, alert rules, web tests, and custom metrics. Each of these metrics scale independently. Most teams don't see the full cost until the bill arrives.

Fleet Monitoring with Netdata: Live Demo

A walkthrough of monitoring a distributed fleet with Netdata, using a simulated fleet of about 1,000 devices spread across regions. We show how the whole fleet reports into a single view: per-second metrics from every node, grouping by region and by customer, a map view that colors each device by health, filtering and saved views for different teams, and an AI-assisted investigation that scans the fleet for anomalies and points to likely causes.

OnlineOrNot updates from June through August 2026

It's been a while since I last updated you on what's new in OnlineOrNot. For the most part, I've continued making it useful for software teams: there's now an MCP server, I've improved the terraform provider significantly, and there's a new TypeScript SDK. You can also (finally?) monitor DNS/TCP with it.

Dr. Cat Hicks on the Psychology of Software Teams

What happens when a software engineer who has put their entire identity into being the resident expert of an obscure technology or language with ten years of experience and who knows the codebase like the back of their hand now has to compete with AI? Psychologically speaking, according to Dr. Cat Hicks, author of The Psychology of Software Teams and founder of Catharsis, that's called identity threat, and it's a surefire way to feel unsafe. We were honored Dr.

Introducing Distributed Tracing in Netdata

Netdata now supports distributed tracing. In this webinar, we'll demo the new tracing capabilities for the first time: OpenTelemetry trace ingestion, the new tracing dashboard, and the UI built to let you move from a metric anomaly to the exact span that caused it. For years, teams have asked us to close the gap between infrastructure monitoring and application performance. This release does that. Netdata can now ingest traces via OTEL, correlate them with the metrics and logs you already collect, and surface them in a purpose-built interface designed for speed and clarity.

Grafana Mobile to Desktop Companion App

The Grafana Mobile App lets you triage alerts with help from Assistant from your phone. You can declare an incident or trigger an investigation into an incident in order to get more information so that by the time you get to your desktop, everything is ready for you. Grafanistas Ignacio and Florian go through a use case deep dive, demonstrating the value of the Grafana Mobile Companion app by triggering an investigation, talk to Assistant, and have all the data you need to resolve an incident - all from your phone.

Best Monitoring Tools With MCP Servers for AI Coding Agents (2026)

Your AI coding agent can read your code, run your tests, and open a pull request. Until recently it could not see what that code does in production. MCP servers from monitoring vendors close that gap. Connect one, and Claude Code, Cursor, or Copilot can pull the error, the trace, and the slow query behind a bug report without you copying anything out of a dashboard. Most major monitoring vendors now offer an official MCP server. But they aren’t interchangeable. Some only expose errors.

How to Make Claude Your UI Design Companion

When I first tried Claude Design, shortly after it was released, I wasn’t impressed. As an every day Figma user, I missed the option to manipulate elements directly, especially for fine tuning details. What I overlooked at that point was the fact that it is really good at generating different options efficiently. Most of them aren’t usable, but getting these options suggested helps when exploring and combining different approaches and ideas.

How to Fix Intermittent Internet Issues: Is It Your Network or Your ISP?

Your Internet circuit is up. The firewall shows the WAN link as connected, your ISP's status page is green, and a speed test comes back at full provisioned bandwidth. Meanwhile, Teams calls at one branch break up for ten minutes every afternoon, and every user at that site sees Salesforce slow to a crawl at the same moment. Then everything recovers before anyone can capture it.

How Agilent Uses Workspace to Turn DEX Data into Confident IT Decisions

⁠Operating across 110 countries, Agilent Technologies supports scientists working in life science research, patient diagnostics and testing that helps ensure the safety of water, food and pharmaceuticals. Keeping the technology behind that work running effectively helps employees stay focused on the science and services that contribute to Agilent’s mission to advance quality of life.

Monitor warehouse data quality beyond pipeline health

You get a Slack message from the VP of Sales: They have asked an AI agent connected to Snowflake for the past quarter’s revenue and the numbers look wrong. First, you verify the agent’s query and, when that looks fine, check the pipelines that populate the underlying table. All jobs completed, the data is recently refreshed. Then it’s time to check the logs for errors. Nothing.

What Happens When an SLA is Breached and How to Recover Customer Trust

What does your organization owe a customer when a priority ticket misses its resolution target by forty minutes? For most service providers and internal service desks, the answer stays unclear until the customer asks for a credit or a manager asks why the monthly SLA report shows a miss. By then, the facts that decide the outcome, such as when the clock started, whether it paused and who was told, are scattered across tickets, emails and chat threads.

SOX ITGC Controls Checklist for IT Service Management and Year-Round Audit Readiness

How much of your SOX audit season goes into rebuilding proof of work that was already done? Access was approved, the change went through review, the backup ran, yet the evidence lives in email threads, chat messages and a spreadsheet someone updated last quarter. When an auditor asks for a complete list of production changes, IT staff have to pull records from several places against a deadline.

Cloud Shell, New Integrations, and More

VirtualMetric DataStream now includes a PowerShell console in the browser, more than a dozen new integrations, and a new way to collect data from servers and virtualization hosts, where teams choose exactly what they collect. This update also brings guided learning for new users, built-in monitoring rules, and new controls for organizations managing branding and sign-in. Here’s what’s new.

How Hybrid WAN Is Transforming Enterprise Network Connectivity

Enterprise networks are evolving as businesses adopt cloud applications, remote work, distributed offices, and connected devices. A hybrid WAN solution can help organizations combine different connectivity options while supporting the performance, reliability, and flexibility required by modern business operations.