Operations | Monitoring | ITSM | DevOps | Cloud

Pushing metric concurrency, cardinality, compute and retention limits with $1000 of infrastructure

We gave five metrics backends the same budget, the same week of data and the same ten queries, then ran those queries at rising concurrency. At one query at a time, the open source engines looked strong. Under concurrency, two of them stopped answering, and the rest slowed down by an order of magnitude.
What happened when we gave $10k worth of data to 5 observability platforms | Live Laugh Logs

We gave $10k worth of data to five different observability platforms. Which agent finds the true answer? In the first episode of our benchmarks series, Chris and Annie walk through how an agent performed on Coralogix, Datadog, New Relic, Dynatrace and Grafana Cloud across 10 injected incidents. They also explain why sampled data makes agents "hallucinate the gap". Subscribe to our channel for more benchmarks and insights into observability and AI.

PCI Compliance Logging: Complete Guide to Requirement 10

Of the 12 Payment Card Industry Data Security Standard (PCI DSS) requirements, Requirement 10 is one your platform team can engineer directly. Under the PCI DSS v4.0.1 standard, automated log review has been a tested requirement since March 31, 2025. Your assessor will test the mechanism that performs the review. This PCI compliance logging guide covers each 10.x sub-requirement, maps the seven event classes to log sources, and lays out a nine-step program you can hand to your assessor.

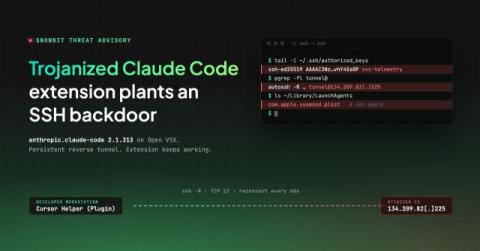
Threat Advisory - Trojanized Claude Code Extension: SSH Backdoor

A tampered build of the Claude Code editor extension (anthropic.claude-code 2.1.313) was published on the Open VSX store used by Vs code,Cursor and similar editors, quietly gives attackers persistent remote access to any computer that runs it, while the extension keeps working normally. Researchers don’t yet know how it was published (the listing belongs to an Anthropic employee) or who is behind it. They found no evidence that Anthropic’s official Marketplace release was affected.

Malicious Claude Code extension in the Cursor marketplace: Coralogix Security Advisory

The Claude Code extension in the Cursor marketplace was compromised for a short period of time today. Watch this security advisory from Chris Cooney and Hetram Yadav, threat detection and response manager at Coralogix, to understand: How the malicious attack operates How to know if you're affected How Coralogix is supporting customers.

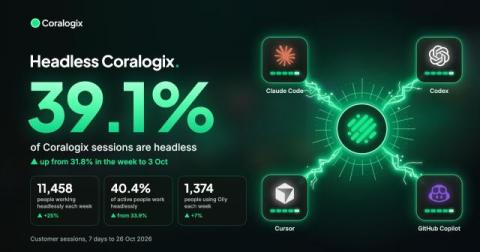
39% of Coralogix sessions are now headless

We set out to understand how customers were using Coralogix from outside the web app. Olly answers questions about a system in plain language. Coding agents query logs, examine traces, read metrics and configure the platform through the Coralogix CLI and MCP server. We wanted to see how much of this was becoming part of everyday work. In the week of 20–26 October, 39% of Coralogix sessions included Olly, the CLI or MCP.

Meet the new Explore: every question, one place

From the first alert to the root cause, without leaving the page. TL;DR: Investigating an incident is a series of quick questions, each one leading to the next. Until now, Explore made you stop between questions to translate them into syntax, switch modes or rebuild a chart. The new Explore lets you go straight from one question to the next: one workspace, any dataset, any team, any way you like to ask. Here’s what that looks like on a real night on call.

Can Observability Reduce Your Tech Debt? | Live Laugh Logs Ep. 5 with Wilco Burggraaf

Your telemetry data can reduce engineering complexity AND make your software more sustainable - find out how in this episode! Welcome to Episode 5 of Live Laugh Logs, the podcast from the Coralogix Developer Relations team. This week, Annie is joined by Wilco Burggraaf, Principal Lead at HighTech Innovators and host of the Sustainable IT Action Netherlands meetup.

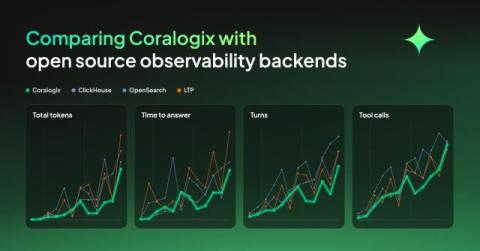
Comparing Coralogix with open source observability backends

We put the same OpenTelemetry data into four backends, Coralogix, ClickHouse, OpenSearch and a Loki, Tempo and Prometheus stack, then set an agent twelve questions against each one, from counting spans to working out what is wrong in a system it has never seen. Then we forced the agents to continue investigating until they got to the right answer. In this experiment, what separated them was the time, tokens, tool calls and turns it took to get there.