Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Observabilty for complex systems and related technologies.
Full-Stack Observability with Grafana Cloud: From Business Impact to Root Cause

How do you trace a dropped conversion or a checkout failure to its technical root cause? See how full-stack observability in Grafana Cloud connects business impact to system performance across web and mobile clients, applications, infrastructure, and databases. In this session, Principal Software Engineer Jim Gehrett and Staff Product Manager Sarah Constant demonstrate how to start with a business problem and work backward through the technology stack to investigate its cause.

What Does a Network Administrator Do? Skills and Faster Fixes with Network Observability

When a branch office can’t reach the ERP system and customer calls start dropping, who gets the call? It’s almost always the network administrator. What that person does the rest of the week is less clear, and a CIO, a CFO and the admin themselves would probably each describe it differently. Part of the reason is how much the network has grown. Ten years ago it was mostly switches, cables and one building.

Disk I/O profiling with eBPF

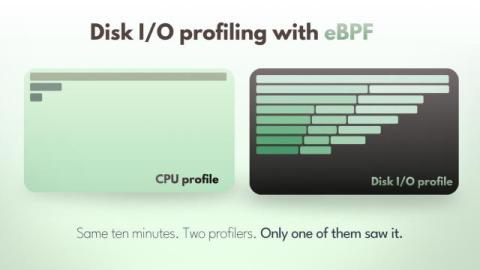
Coroot's node-agent has had an eBPF CPU profiler for a long time. When something burns CPU, you open the flame graph and see which function. When something waits for the disk, you have nothing: the CPU profile is flat, because waiting does not consume CPU. The metrics for disk problems are always the same. Latency on a volume goes up, utilization hits 100%, queries slow down. Every chart agrees the disk is the bottleneck, none of them says what the database was doing while it waited. Flushing pages?

It's a Critical CVE, Now What?

Bryan Peace Leon Adato break down what exactly security-minded IT folks - whether they work in SRE, dev, networking, or more esoteric disciplines - should do when a new, critical, apocalyptic vulnerability is announced. They walk you step by step through research, analysis, and how to protect your company if a patch isn't out yet. Along the way they muse about the nature of the industry, the sudden spike in CVEs, and where to find the best hard cidr to take the edge off.

AI observability: Why traditional monitoring isn't enough for AI systems

Traditional monitoring watches four things: whether the system is up (availability), how fast it responds (latency), how often it errors (error rate), and how hard the underlying resources are working (resource utilization). This system works because software is deterministic: the same input produces the same output, so a deviation means something broke, and it announces itself as a timeout.

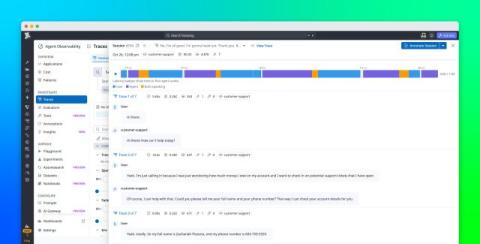
Trace voice agents with Datadog Agent Observability

A voice agent can return the right words and still deliver a poor experience. It might leave a caller in silence, speak over them, or stop midway through a response. A transcript may look correct even when the audio the user heard was delayed, incomplete, or different from the text on screen. These problems are difficult to diagnose from text traces alone. Voice conversations also involve more than a single request and response.

Evaluate AI models for observability: o11y-bench joins Fireworks' Specialized Intelligence Index and reaches v1.1

When evaluating AI models for observability, generating a plausible query or explanation isn't enough. Teams need to know whether an agent's conclusions are supported by telemetry, whether its changes to dashboards actually work, and whether it can deliver reliable results consistently. This is why we built o11y-bench, Grafana Labs' open benchmark for evaluating AI models on observability and SRE tasks. And today, we're excited to share two updates.

Ship SecOps changes like software: Modernizing the SOC without breaking what works

Cribl gives security teams control over their data: what they collect, where to send it and how much to keep. The rest of the SecOps stack hasn’t kept pace. Detections, parsers and configurations spread across SIEMs, pipelines and data lakes still change by hand, so every cost cut, migration or new source turns into weeks of manual validation, and plenty of planned changes never happen at all. SecOps as Code closes that gap: every change ships like software, with testing, version control and rollback across the entire infrastructure.

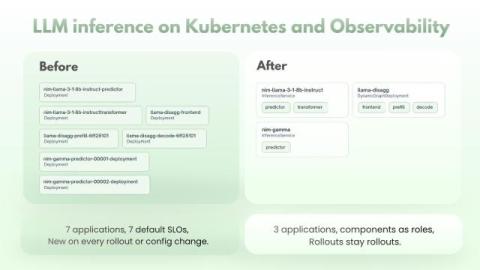
LLM inference on Kubernetes and observability

Running an LLM on Kubernetes is rarely just a Deployment with vLLM in it anymore. A whole layer of frameworks and operators has grown up for it: KServe, NVIDIA Dynamo, Ray Serve, Kthena, llm-d. Each one adds its own custom resource that describes a model deployment, with routing, autoscaling and the split of a model across pods built in, and each one turns that resource into ordinary Kubernetes objects in its own way.