Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Service Reliability Engineering and related technologies.

Inside Rootly On-Call: Schedules, Escalations & Alerts, End to End

Paging people shouldn’t be the hard part of incident response. In this walkthrough, we tour the Rootly On-Call platform end to end and show how teams set up on-call that’s reliable, fair, and easy to manage. Whether you’re moving off another paging tool or setting up on-call for the first time, this video shows how Rootly brings on-call and incident response together in one place.
A walkthrough of a root cause analysis with ilert AI SRE

It's 3am and a complaint has made its way to you: customers can't see product reviews. Nothing has crashed, and no alert points anywhere useful. Somewhere in your stack one service is failing, and the one showing the error is probably not it. Before you can fix anything you have to find it, and that search is most of your night. Now imagine you open the laptop, type one sentence and go grab a coffee. By the time you’re back, the root cause is ready, evidence attached. Your job is to check it.

Top on-call practices for SREs (by SREs)

This September, we hosted a few of our customers at the ilert headquarters in Cologne. The plan was to share where we're heading, have real-life conversations, and give them more room to ask us questions and share their thoughts. ‍ One part of the day was a discussion about on-call culture with some of the greatest minds in SRE (source: they chose ilert as their incident management tool). We asked our customers: what are your top practices for on-call?

Service Mesh Observability: Istio, Linkerd and Envoy Metrics

Service mesh observability guide: the metrics Istio, Linkerd and Envoy proxies emit, what ambient mode changes, and why tracing still needs app changes. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

MCP Server Monitoring: Tracing Tool Calls with OpenTelemetry

MCP server monitoring guide: spans, metrics and logs to record for tool calls, why failed tools look healthy, and how to trace requests from client to server. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

CI/CD Pipeline Observability: GitHub Actions, Jenkins and ArgoCD

CI/CD observability guide: the OpenTelemetry CI/CD conventions, tracing GitHub Actions and Jenkins runs, queue time, failure vs error, and deploy markers. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

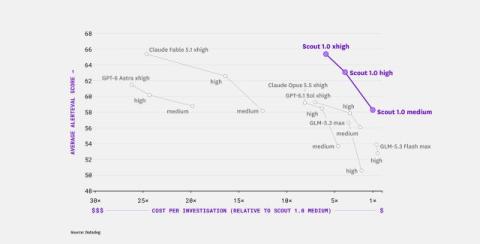
Introducing Scout 1.0: A new SRE model powering Bits AI with frontier performance at a fraction of the cost

Today, we’re introducing Scout 1.0, Datadog’s first AI model specialized for investigating production issues. Scout powers Bits Investigation, our AI SRE. We trained Scout to reduce inference cost so that investigations are cheap enough to run an order of magnitude more often and earlier in an incident’s lifecycle. Key highlights include: Close dialog.