Operations | Monitoring | ITSM | DevOps | Cloud

Deployment alerts: know when a renewed certificate doesn't land

Renewing a certificate is the easy part. Getting it onto the server is where automation breaks. Somebody rotates the API token on the firewall. A service account password expires. A VM gets rebuilt and the agent never comes back. The certificate renews right on schedule, the deployment fails, and the server keeps serving the old certificate until it expires. Renewed and deployed are not the same thing.
Go from alert to post-incident review with Grafana Cloud IRM and AI

You’ve got 10 minutes before your next meeting when your phone starts ringing. You’re being paged because the frontend is erroring with failed API requests. You open one tool to see what fired, then another to figure out what’s going on. You message a teammate in Slack to see if they’re noticing the same thing. That’s a lot of context switching, and it’s still how a lot of teams' incident response works today. Opening another tool and catching someone up takes time.

SIGNL4 Update: AI-Powered Event Routing, Alert Analytics, On-Call Coverage & More

This October, SIGNL4 is taking a big leap forward! One of our most comprehensive updates yet introduces AI-powered event routing, powerful new analytics to identify alert hotspots and trends, and instant visibility into on-call coverage gaps. Add smarter team and workflow management, plus enhanced security and compliance features, and there’s plenty to explore!

After-Hours IT Support: How to Build a Reliable On-Call Process

IT incidents do not follow a 9-to-5 schedule. A server can go down overnight, a critical application can fail on a weekend, or a high-priority support ticket can arrive when the IT team has already left the office. For IT teams, the challenge goes beyond simply providing after-hours IT support. They need a reliable on-call process that identifies the right responder, delivers critical alerts and ensures timely escalation when necessary.

How to Manage Cloud Alerts: AWS, Azure, and Google Cloud

To manage cloud alerts effectively, define which conditions require immediate action, include useful incident context, and route critical notifications to the engineer currently on call. Add escalation rules for unanswered alerts and test the entire path from detection to response. This process applies whether your team uses AWS, Azure, Google Cloud, or several providers. Cloud monitoring can tell you something is wrong.

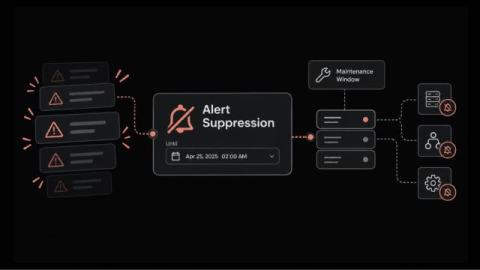
How Alert Suppression Pauses Alerts During Planned Work Without Losing Visibility

How many pages did your on-call engineer get during the last planned firmware upgrade on a core switch? The device stops responding and every dependent check fails. Soon the on-call phone is buzzing with alerts for a change that was approved last week. Alert suppression is a time-limited pause on alerts for a condition you already know about, such as planned work or an issue under investigation. And what is alert suppression from the engineer's side of the console?

8 Best AI SRE Tools in 2026 for Incident Investigation and Reliability

The best AI SRE tools to evaluate in 2026 include Sherlocks AI, Resolve AI, Traversal, Cleric, Rootly AI SRE, Komodor Klaudia, Datadog Bits Investigation, and Dynatrace Intelligence. Each addresses a different part of reliability work, from investigating alerts across multiple systems to diagnosing Kubernetes failures or validating production changes. Choosing the right tool starts with a practical question: where does your team lose time during an incident?

10 Best AI Logging Tools in 2026: Features, Pricing & Comparison

As businesses increasingly integrate artificial intelligence into their applications and workflows, understanding what happens behind the scenes of these AI systems has become essential. AI-powered chatbots, large language models (LLMs), and autonomous AI agents can process thousands of requests, interact with external applications, and execute complex tasks. However, when something goes wrong, identifying the source of the problem isn’t always straightforward. Was the AI response incorrect?

5 Signs Your In-House Ops Team Has Hit Its Ceiling (And What to Do Next)

Every small ops team reaches a point where the work outgrows the people. Tickets arrive faster than they close, the pager goes off at 2 a.m. for the third time this week, and the roadmap quietly slips another quarter. Leadership sees missed deadlines. The team sees a system with no slack left in it. The hard part is spotting the ceiling before it turns into attrition or an outage. This article covers five warning signs that a team is stretched too thin, then shows how to decide what to keep in-house and what to hand off.

Automated Medical Answering Services: Cost and Setup Guide

After-hours calls can create missed messages and send urgent issues to the wrong clinician. For private medical practices, that risk grows when call answering and on-call escalation rely on the same loosely defined workflow. Answering service receives an inbound call, captures information, and categorizes the request. On-call routing identifies the responsible clinician, delivers the message, and escalates it when the clinician does not respond.