Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

Elastic Introduces Elastic nightshift AI SRE to Investigate with the Full Context Others Can't Afford to Keep

The AI SRE uses complete context from across the entire stack to continuously detect issues and learn from every incident, delivering evidence-backed answers engineers can trust.
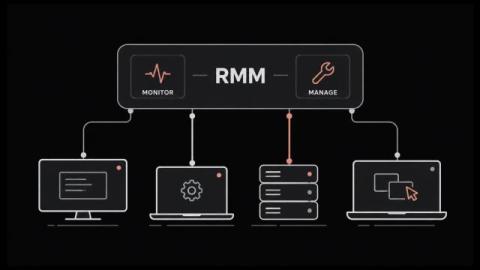
What Is RMM (Remote Monitoring and Management)?

RMM lets one small team look after thousands of machines nobody will ever physically touch. It grew up inside managed service providers. The whole category runs on agent-based monitoring, which means a small program sits on every endpoint and phones home on a schedule. That agent is also why attackers have taken such an interest lately. In this blog, you'll see: By the end you'll know what the category covers and where it stops. RMM stands for remote monitoring and management.

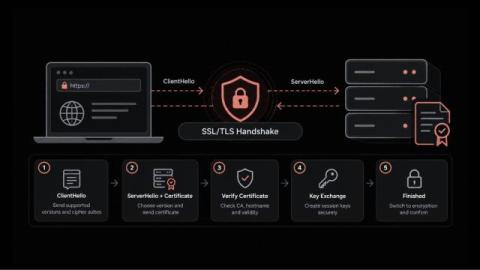
SSL Handshake Guide Covering Each Step and the Fixes That Prevent Outages

Why would a website that passes every uptime check still show customers a security warning? In most cases, the server is running and the network is healthy. The failure happens earlier, during the brief exchange in which the browser and the server agree on how to communicate securely. That moment is the SSL handshake. If it goes wrong, users get an error page while your dashboards stay green. Maybe a certificate expired; maybe a routine change left both sides on different protocol versions.

Meet Rosetta

During an incident, the answers an engineer needs are spread across tools. Telemetry sits in one place, configurations in another, and tickets in a third. Building a complete picture means knowing which tool holds which piece and how to query each one, usually under time pressure. Rosetta is the conversational interface for Selector Foundry, the agentic NetOps platform built on Selector’s existing AIOps and Observability solution.

How Configuration Monitoring Helps Detect Zero-Day Activity

Last updated: October 9, 2026 A zero-day vulnerability may be unknown, but its effects often are not. Exploitation can leave behind observable changes: a new privileged account, an altered management setting, an unexpected file, a modified access rule, or configuration drift from an approved baseline. That makes zero-day configuration monitoring an important part of a defense-in-depth strategy.

Top Tips: Staying productive during a slow work week

Top tips is a weekly column where we highlight what’s trending in the tech world and share ways to stay ahead. This week, we’re looking at what you can when you’re having a slow-paced, less hectic workweek. We’ve all been there at intermittent intervals of our jobs: You check into the office right after the weekend only to realize you’re having one of those slow, relatively low-pressure weeks. So what do you do to stay productive?

How AI agents help teams deliver better digital experiences

The moment your page slows down, two clocks start. One is yours: time to alert, time to investigate, time to fix. The other belongs to the user staring at the slow page. Yours is measured in minutes. Theirs runs out in seconds. That gap is what AI agents close. Zia Agents in OpManager Nexus detects an issue, works out the cause, and runs the fix on its own, often before your users feel a thing. This blog looks at how that changes the experience you deliver.

Event Intelligence and the Diagnosis Gap: When Logs Are the Only Witness

✓ operational truth Incident diagnosis is now the longest phase of resolution because evidence is fragmented, expertise sits with a few people, and cloud and SaaS estates no longer allow engineers to log in and look. Event Intelligence closes the gap by correlating events into a single probable cause, mining logs automatically, and arriving at the incident with a hypothesis already formed.

Searching Sentry Logs with Regex

We use Sentry's new Regex search for Logs to hunt for non-obvious bugs in our app. What do you do when traces show that Postgres jobs are backing up? Logs are trace-connected, so by looking at one of the affected traces, we can see all of the logs on that trace. In there, we can see Postgres has logged that it acquired a lock only after a long wait. Using regex, we can find all of these logs that describe acquiring a lock after a 10-second-plus wait. That narrows our search from thousands or hundreds of logs down to about a dozen.