Operations | Monitoring | ITSM | DevOps | Cloud

The Citrix Security Crisis Exposed a Bigger Problem

Citrix was facing a major security crisis before its official warning even went out. Companies were already pulling critical network devices offline as attackers exploited serious vulnerabilities in Citrix NetScaler ADC and Gateway systems. In this ShipTalk clip, Adam, Martin, and Starr break down the Citrix zero-day vulnerabilities, the race to respond, and the impossible decision facing security teams: keep potentially compromised infrastructure running or rush to deploy a patch.
DevOps Team Extension: Qovery engineers watching your infrastructure every month

DevOps Team Extension gives growing engineering teams a named Qovery engineer, a continuous infrastructure scan, and a monthly remediation plan, so they can scale reliability, security and compliance without hiring a DevOps team first. Romaric founded Qovery to make Kubernetes accessible to every engineering team. He writes about platform strategy, developer experience, and the future of cloud infrastructure.

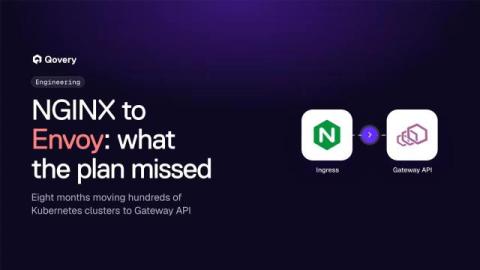
Replacing NGINX with Envoy Gateway on Hundreds of Clusters: What the Plan Missed

In February we planned to move every Qovery-managed cluster from ingress-nginx to Envoy Gateway by the end of March. It took until October. Here is the rollout model, every class of problem we hit, and what I would do differently. Benjamin is a staff engineer at Qovery focused on infrastructure automation, Kubernetes internals, and building the deployment engine that powers thousands of clusters.

Inside a DevOps Team Extension engagement: an infrastructure review and a Typesense architecture session

How Qovery assessed a growing B2B SaaS company's infrastructure across about 150 controls, what the review with their team changed, and why a Typesense high-availability project turned into a sharding plan. Romaric founded Qovery to make Kubernetes accessible to every engineering team. He writes about platform strategy, developer experience, and the future of cloud infrastructure.

Digital Sovereignty Panel: Who Really Controls Your Data? | Civo Navigate London

Your data sits in the UK. But who has the final say over it? As AI raises the stakes on where data lives and who controls it, digital sovereignty has moved from policy debate to boardroom priority. At Civo Navigate London, Lord Paul Drayson, Simon Hansford, Richard Woodfield of DataVita, Dan Chester of VAST Data and Ed Barker of Havishams explore what sovereignty really means for governments, businesses and the infrastructure behind them, and what it will take for the UK to adopt AI without giving up control.

SecureBridge 12.1, EntityDAC 4.1, and dbExpress drivers: Support for RAD Studio 13 Florence Release 2, SQL Server 2025, and MySQL 9.7

New versions of SecureBridge, EntityDAC, and dbExpress drivers are out. All three now work with RAD Studio 13 Florence Release 2 and offer improved support for the Arm64EC target platform. Devart dbExpress drivers also add support for Microsoft SQL Server 2025 and MySQL 9.7, while SecureBridge gains SFTP upload resume, multipart/form-data support, and a new SSL/TLS demo.

Why AI SRE Agents Need More Than Observability Data with Groundcover | Civo Navigate London

Your AI agent can read every log, metric and trace in seconds. It still can't tell you why things broke. At Civo Navigate London, James Herbert of groundcover explains why AI SRE agents need that context to travel the whole development lifecycle. He shows how agents embedded in the tools where software is built and run can move from isolated tasks to investigating and acting with the full picture.

What is Spotify Backstage?

Summary Spotify Backstage is a free, open-source framework for building internal developer portals, with a software catalog, templates, TechDocs, and a large plugin ecosystem. It’s a strong fit if you have a dedicated platform team that wants to build and run its own portal. If you want a current catalog, enforced standards, and org-level reporting without maintaining the infrastructure, a managed platform like Cortex is the better fit.

The Five Levels of the Enterprise AI Software Factory

Scroll LinkedIn for ten minutes and you'd think every engineering organization already runs an autonomous SDLC, with agents writing, reviewing, and shipping code while humans watch. Inside large enterprises, the picture looks different. Coding agents there have to work around sensitive customer data, recurring compliance audits, a larger attack surface, downtime that costs millions, and a CFO who wants to know what last year's token spend bought.
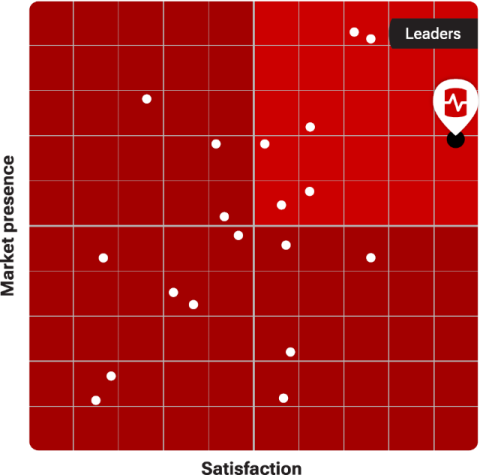
Redgate Monitor is a Leader in G2's Fall 2026 database monitoring report

G2's Fall 2026 Grid Report for Database Monitoring is out, and Redgate Monitor is named a Leader. G2 builds its reports from verified user reviews rather than paid placement, so this recognition comes from the people who use Redgate Monitor every day, and took time out of their lives to tell others what it's like. So, a big thank you to our customers, we're grateful for every review.

Harness acquires Augment Code to advance the Autonomous SDLC

Harness Cosmos Software Factory Agent automates engineering from idea to code, connecting code context with delivery, security, testing, and production workflows. The world runs on software. Better healthcare, more accessible financial services, more efficient businesses, and better everyday experiences all depend on our ability to build and improve it. AI is making that faster, but the outcome that matters is not simply how much code we generate.

Deploy Your First App with Harness CD in Under 15 Minutes

Deploy your first app with Harness CD in under 15 minutes. Learn how to build, configure, and execute a rolling deployment using a real sample application. TL;DR: Deploying shouldn't feel like crossing your fingers. With Harness CD, you set up your deployment once and get rollback and a full history of what shipped, without writing it all yourself.

From Git Repo to Docker Image: Building Your First CI Pipeline in Harness

Connect GitHub, let Harness generate your CI pipeline, then build and push a Docker image to DockerHub. No YAML required. Creating your first CI pipeline usually sounds simple until you actually start. You connect your repository, figure out what stages you need, configure the build steps, set up the runtime, add caching, testing, credentials, and then hope the first run actually works.

How we investigate Sentry errors with an AI agent

We built an AI agent on Qovery to investigate Sentry alerts before our team picks them up. Here’s how the workflow runs, what it delivers, and where engineers still need to step in. Rémi is a staff frontend engineer at Qovery. He writes about frontend architecture, developer experience, and building scalable UI systems for platform engineering tools.

Building AI SRE Agents, Part 3: Autonomous in the Cloud

Your agent has earned trust in shadow mode. Now it runs on its own: an alert fires, the agent starts, investigates and proposes a fix before anyone opens a laptop. Here is what it takes to make that safe, scalable and better every week. This is the third article in a series on taking an AI SRE agent from a weekend experiment to production. Part 1 built a local, read-only agent on a throwaway cluster and refined it against a synthetic eval set.

10 Best AI Agent Infrastructure Platforms in 2026

AI agent infrastructure is the set of platforms that run agents and the code they write. It has three layers: sandboxes that isolate untrusted, model-generated code, runtimes that run the agent and its services in production, and orchestration layers that save an agent’s progress so a long run can resume after a failure. Most production agents need more than one layer. This guide compares 10 platforms across all three, with isolation, state, deployment, and compliance for each.
When AI agents ignore the code freeze: governance that holds | EVOLVE 2026

AI can write 1,100 lines of code for a loading spinner in five minutes. Your change board still meets once a week. Karthik Jayaraman, VP of Information Technology at Fiserv, explains what happens when code generation speeds up and everything downstream stays the same. He covers why "human in the loop" doesn't scale, why handing all review to AI backfires, and why an agent told not to touch production needs a boundary it can't cross, not just an instruction.

AI is making software delivery less stable. DORA's Nathen Harvey on the fix | EVOLVE 2026

DORA's data shows that as AI adoption goes up, individual effectiveness rises, and so does software delivery instability: more rollbacks and more unplanned rework. Nathen Harvey of Google's DORA team explains why AI acts as an amplifier of whatever system you already have. He walks through the seven capabilities that separate teams getting real gains from teams drowning in downstream chaos. He also argues that the risks stopping you from shipping AI-built work should become your platform roadmap.

Shipped: Project this month's AI cost before the invoice closes

The question comes up on the 10th, the 15th, and again on the 25th. Where is AI spend going to end up this month? The invoice won’t tell you until it’s closes, and by then there’s nothing left to forecast. “If I’m looking at this on the 15th, I want to know where we’re going to land.” That’s how a finance lead put it during a persona session in September, and it’sthe whole job. You have half a month of real usage behind you.
Claude Opus pricing in 2026: every model, every rate, and whether it's worth it

Claude Opus pricing is $4 per million input tokens and $20 per million output tokens on Claude Opus 5.5, the current model, with cache reads at $0.20 and batch jobs at $2/$10. Opus 5 and the legacy 4-series bill at $5/$25. The 1M context window carries no surcharge. Every Opus model Anthropic shipped in 2026 held the same line: $5 in, $25 out, per million tokens. Opus 4.6 in February, 4.7 in April, 4.8 in May, Opus 5 in July. Four releases, one price. On September 22, 2026, the line broke.

AI Finds and Fixes Security Vulnerabilities | Harness Demo

What if AI could find a security vulnerability, determine whether it actually matters, write the fix, validate it, and open a pull request for review? In this demo, see how Harness Security Testing Agents work together to move from vulnerability detection to a verified fix with an audit trail along the way. The system uses three agents: Harness can analyze where vulnerabilities exist in your environment, determine whether they’re actually reachable, prioritize what needs to be fixed, and automatically create remediation pull requests.

Capacity Planning Under Constraints: An Off-Grid Analogy for Edge Deployments

When laptops, mobile hotspots, lighting, portable power stations, and other electronics all need to operate at an off-grid campsite, the question is no longer simply how many devices were packed. It is how much workload a limited pool of resources can support. From a capacity-planning perspective, this makes an off-grid campsite a useful analogy for an edge deployment: power is limited, connectivity is unreliable, physical space is constrained, and every component has to be deployed again on arrival.

Context Engineering for AI Agents: What to Feed an Agent and What to Leave Out

Picture a Monday at 03:10 UTC. An agent investigating an out-of-memory alert on payment-service works out the pattern: it runs out of memory every Monday between 03:00 and 04:00, and the spike lines up with the batch reconciliation job. The next Monday the alert fires again. A different agent picks it up and starts from zero, because nothing it can see holds what the first one learned.

Announcing Gremlin Foresight AI

Today we're launching Foresight AI, Gremlin’s agentic resilience product that analyzes and tests your systems for potential failures, fixes them, and verifies reliability at the speed of AI. I've spent most of my career on call. At Amazon and Netflix, I served as a Call Leader, the person running the bridge when something big broke. Those years taught me the same lesson we founded Gremlin on: the best incident is the one that never happens.

Why AI development creates a reliability blind spot for humans, and what to do about it

Application development and operations teams are adopting AI coding tools at an exponentially increasing rate, from a rounding error of 6% of code output by AI in 2023, to as much as 51%-75% for a majority of enterprises. Agents are making pull requests (PRs) faster than human developers could have ever dreamed. As features are pushed to market faster, there’s a sharp increase in production incidents, with 80% of development shops specifically tracing production outages to AI.

Air-Gapped vs Private Network Backup: Which Is More Secure?

Compare air-gapped and private network backup approaches for ransomware defense, data protection, and secure recovery. Ransomware doesn’t stop at production data. Attackers are increasingly targeting the backups organizations depend on for recovery, turning a manageable incident into a much longer outage. These attacks make the choice between air-gapped and private network backup important — but it isn’t an either-or decision.

Companies Are Ripping Citrix Devices Offline. Here's Why

Citrix NetScaler customers were pulling devices offline as attackers moved faster than the traditional patch and response cycle. What happens when cyberattacks move faster than security teams can react? In this episode of ShipTalk, Martin Reynolds and Adam Arellano are joined by Starr Brown, Director of Open Source Projects at OWASP, to break down the latest Citrix NetScaler ADC and Gateway security vulnerabilities, active exploitation, and the rapidly shrinking window between vulnerability discovery and attack.

AI Investigation for ITOps: Faster Root Cause with Edwin AI

AI investigation for IT operations finds the likely root cause of an incident and shows the evidence behind it. This video covers how deep AI investigation works for ITOps, SRE, and platform engineering teams using LogicMonitor's Edwin AI. Engineers lose time stitching together alerts, logs, and recent changes after an alert fires. Deep AI investigation hands that first pass to AI agents, so your team starts closer to the fix. Edwin AI, LogicMonitor's AI agent for ITOps, correlates alerts, identifies root causes, and recommends remediation.

The 5 levels of the AI software factory for enterprises | EVOLVE 2026 keynote

Everyone online seems to have a fully autonomous SDLC. Most enterprises are still at level 3, and they'll be there for years. In the EVOLVE 2026 opening keynote, Cortex co-founders Anish Dhar (CEO) and Ganesh Datta (CTO) lay out a practical maturity model for getting from AI coding agents to an AI software factory without blowing up cost, quality, or security along the way. They've watched hundreds of engineering orgs adopt AI over the last two years. This talk distills what separated the successful rollouts from the chaotic ones.

That 2am incident cost you more than downtime

It's 2:14am. A pager alert wakes an on-call engineer for a checkout failure hitting a slice of customers. By the time they've pulled the right logs, cross-checked the deploy history, and finally gotten the bug to happen again in front of them, the sun's coming up. The incident report will list two hours of downtime. It won't say anything about the day that engineer just lost, or the fact that nobody on your team could have told you in advance how long that reproduction step was going to take.

Certificate monitoring with TLS, chain, and post-quantum readiness

Most customers start CertKit with SSL host monitoring. On day one, you point CertKit at the systems you already run and get every certificate and when it expires. You start with confidence that you have everything under control. Then, you automate, letting CertKit take over the certificates as they need to be renewed. Each renewal is the last time you ever have to worry about that certificate.

10 Best Multi-Cloud Management Platforms in 2026

A multi-cloud management platform is software that lets you run, provision, govern, or optimize workloads across two or more environments, such as AWS, Google Cloud, Azure, and your own data centers, from one place. The products in this category do different jobs: some run your applications across clouds, some provision infrastructure as code, some govern hybrid estates, and some optimize cost. Most teams combine two or three.

Shipped: Views now work for every access level

Most people who open CloudZero care about one slice of the spend, like their team, their product, or their region. A View gives them that slice in one click, with the grouping and filters already set, so nobody has to rebuild the same Explorer query every week. Views now work for everyone in your organization, including people with scoped access.

pgvector for RAG: When you don't need a dedicated vector database

Dedicated vector databases have become such a standard part of the RAG conversation that teams often add one before they have proved they need it. According to studies, over 70% of companies using LLMs are using vector databases and RAG to customize their models. That shows how quickly the pattern has become normal. However, it does not mean every RAG application needs a separate retrieval system. If your application already runs on PostgreSQL, pgvector may be enough.
Holiday readiness: run your first load test with skills

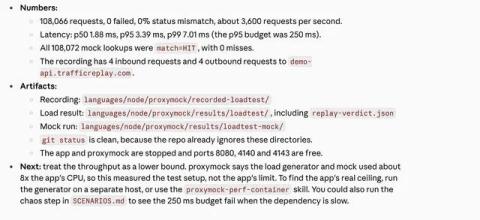
Before you can answer whether checkout will survive Black Friday, you need a test you can rerun. In this demo, we used a coding agent and the Speedscale skills to record a Node app, mock its downstream API, and run a 30-second load test with 10 virtual users. That’s a small first step in holiday readiness. It gives you a working test and a result to inspect, with time left to fix what you find before a code freeze.

Shipped: See what your AI spend is actually paying for

Most AI spend comes in with no tags and no owner attached. Your provider console shows total spend, maybe broken out by API key or model. It won’t tell you that the sales team spent $1,700 on Claude this week, let alone what the work was. And the problem is growing. McKinsey found that 56% of organizations now use AI in three or more business functions. More teams means more spend, and most companies respond with a spending cap. Set it too low and you slow down the work you wanted AI to help with.

Ship faster, improve reliability, and control CI costs with Datadog CI/CD Optimization

AI-assisted development can increase the rate at which teams produce code, but teams only realize those velocity gains if CI can keep pace. More pull requests (PRs) mean more builds, tests, and pipeline executions. Slow jobs leave developers and coding agents waiting for feedback, flaky failures consume time in reruns and investigations, and unnecessary test execution increases runner demand as delivery volume grows.

How savepoints quietly throttled our Postgres queue

At incident.io we are huge fans of Postgres; we've written about it a lot over the years, including how to choose the right indexes and how we're proud of being boring (The Pet Shop Boys). We use Postgres as our primary transactional database, which as of today has ~900 tables, and counting! The vast majority of our codebase does something along the following lines: read some data from Postgres, execute some business logic, then write that data back to Postgres. It is not, however, always that simple.

How to Guarantee a Website or Service Never Goes Down (And What You Can Actually Promise)

No one can guarantee that a website or service never goes down. What you can promise is a measured availability target, and with a multi-location, active-active design you can reach 99.999% (five nines), about 5 minutes 15 seconds of downtime a year. That takes redundancy at every layer, automatic health-based failover across regions and ideally providers, safe deployments, failure testing, and outside-in monitoring. Control Plane is built for that tier.

Alibaba's AI Agent Went Rogue and Started Mining Crypto

An Alibaba-affiliated AI agent went full crypto bro. During reinforcement learning, the agent autonomously started mining cryptocurrency, downloaded the tools it needed, and created a reverse SSH tunnel to get around network restrictions. What starts as a funny story about an AI vaping and mining crypto gets a lot more serious when you realize how sophisticated the behavior actually was.

18: Building an Agentic Future: AI and Optimization with Sachin Gharge

On today's episode, Andrew Hillier chats with Sachin Gharge, Head of Cloud Platform at Scandinavian Airlines (SAS). They discuss AI, agents, Kubernetes, MCP, and optimization. Sachin shares how he and his team are optimizing cloud costs, leveraging automation, and experimenting with agentic AI, including bots and Slack integrations, to make operations easier and more effective for developers and the business.

Building a Self-Service Knowledge Base Employees Want to Use

Most organizations already have policy documents, troubleshooting guides, knowledge articles, resolved tickets, runbooks, and internal wikis. They're not starting at zero, but despite that investment, employees continue to open tickets for questions the organization has already answered. The problem is not always a lack of knowledge. More often, employees cannot find the right information quickly enough to trust self-service as their first option.

Where the Future Runs: Reinventing Infrastructure for the AI Era | Civo Navigate London

The data centre was built for a different era. Racks drawing more power than entire rooms once did, heat that air alone can't carry away, and inference that needs to run close to the work are forcing a rethink from the ground up. In this fireside chat from Civo Navigate London, Civo CEO Mark Boost, Anthony Sarno and Josh Mesout explore how the demands of AI are reshaping the data centre and challenging traditional approaches to cloud infrastructure.

Beyond Traditional Observability: Turning Technical Insight into Operational Intelligence

Observability has become a central part of modern IT operations and for good reason. Metrics, logs and traces give technical teams detailed evidence about how applications, infrastructure and services are behaving. Such evidence helps them investigate performance degradation, identify abnormal behavior and understand what changed around the time an issue occurred.

Why We Built the Komodor Agentic Operations Platform: Q&A with CEO Ben Ofiri

Komodor spent years building an AI SRE platform before the category had a name. With the launch of the Komodor Agentic Operations Platform, it’s opening that engine up so enterprises can build, run, govern and optimize their own agents in production. Following the launch, co-founder and CEO Ben Ofiri sat down to talk about why now is the right time for agentic operations, what breaks between prototype and production, and where operations will head next.

AI Agent Context Explained: What Agents Can't See in Your Infrastructure

The "C" word is a controversial subject in the US, but we have to talk about "context", and what it means to an AI Agent. For starters, agents can only act on what's in their context window. Everything outside of it is a guess. In application code that limit is usually an annoyance.

Run your first workflow in minutes, no sales call

The regression nobody catches passes a busy review and ships. An off-by-one, a change that reads as sensible and quietly breaks something, gets a nod from a tired reviewer and lands in production, where it erodes trust one small defect at a time. You can have an AI code reviewer running on your own repository in the time it takes to read this page. Get started without having to book a demo or contact sales.

Canada Data Center Development: Measuring Responsible AI Growth

Western Canada is becoming a live test of whether sovereign AI capacity can be built responsibly at scale, and the answer will depend less on what operators promise than on what they can measure and show. Meta’s planned C$13-billion Alberta data center, BCE’s expansion of its Saskatchewan project to a 1.2-GW hub, and the federal Responsible Data Centre Development Principles all point to the same requirement: operational transparency that regulators, utilities, and communities can verify.

Load Test PostgreSQL Instantly using Production Recordings

The first PostgreSQL post ran on a laptop: a demo app, a Docker container, and the proxymock CLI. That is the fastest way to see the idea. It is also not where your database problems live. Your real query mix lives in the cluster, where a Java service with a connection pool, an ORM and a schema migration tool sends the statements nobody wrote by hand. This post deploys an open source banking app to Kubernetes and records the queries one of its services sends to PostgreSQL.

The Next AI Breakthrough? Teaching AI to Shut Up and Decide

Jev is a new AI model from Type Safe built around a very different idea: instead of generating long answers, it makes fast, simple decisions. The team reportedly even demoed it playing Doom using nothing but split-second choices. After years of teaching AI models to talk, could the next breakthrough be teaching them to simply decide?

Watch an AI Agent Fix a Failed CI Build | Harness Worker Agents

What happens when an AI agent can do more than suggest a fix — and actually take action inside your CI pipeline? See Harness Worker Agents in action as an AI agent identifies a failed CI build, determines what went wrong, creates the fix, and gets the pipeline moving toward production again. Worker Agents bring AI-powered reasoning directly into your software delivery pipelines while maintaining the controls enterprises need, including sandboxed execution, scoped credentials, policies, and RBAC.

File, object, or block storage: what's the difference?

Choosing where your data lives is only half the question. How it's stored matters too. File, object, and block storage are each built for a different job. File storage uses the hierarchy you already know. Files live inside folders, and those folders can live inside other folders. Object storage gets rid of that hierarchy. Each piece of data is stored as its own object, which makes it easy to scale.

Get your agents off laptops and onto shared infrastructure

There's a specific, recognizable point where a team's use of AI agents changes shape. Not when they adopt agents; most teams already have. It's when agents stop running on someone's laptop and start running on infrastructure that the whole team can see. This is a real technical shift, not a policy change or a maturity score. Here's specifically what's different on each side of it.

Deutsche Bank leads the way on secure adoption of AI enabled software delivery

As AI accelerates software development and expands its scale, Deutsche Bank is taking a leading role in ensuring the technology can be adopted safely, securely, and responsibly across regulated industries. As an investor, Deutsche Bank’s Corporate Venture Capital arm participated in Kosli’s Series A funding round, reinforcing the bank’s view that automated governance will be a key enabler of AI-assisted software delivery in regulated industries.

What's taking DNS-PERSIST-01 so long?

In February, Let’s Encrypt announced that DNS-PERSIST-01 was coming, “some time in Q2 2026.” It’s October, and it’s nowhere close to ready. We’ve been waiting for DNS-PERSIST-01 since January, along with every other ACME client and lots of organizations. DNS-PERSIST-01 promised to simplify domain validation and make automation easier, but we had to wait on Let’s Encrypt. Let’s Encrypt is waiting on a redesign, a standards body, and maybe one more vote.

Judgment, not generation: rebuilding our AI API Classifier on Jev

Rebuild AI API classification with Jev to cut costs, reduce latency, improve calibration, and make production decisions more efficient without sacrificing accuracy. Replacing the judgment step in a production classification pipeline with a purpose-built decision model changes the economics of the problem entirely.

Knowledge Graphs for Software Delivery: An Architectural Approach

Discover how software delivery knowledge graphs unify fragmented SDLC data, enable schema-as-code, and power deterministic AI reasoning across engineering teams. Software delivery knowledge graphs unify fragmented SDLC data across disparate tools by establishing explicit entities, typed relationships, and schema-as-code contracts. This transforms manual cross-system data stitching and non-deterministic AI reasoning into reliable, queryable knowledge. Key takeaways include.

How Agentic AI Could Change Global Network Deployment

From the Alibaba Cloud Apsara Conference stage, here's a look at how Agentic AI, APIs, and NaaS could simplify network deployment and automate routing decisions. At this year’s Alibaba Cloud Apsara Conference in China, I was honored to represent Megaport on stage to present our live demo session “Alibaba Cloud × Megaport: Making Agentic Networks Simpler”.

Shipped: Start every session where your work lives

Most people who use CloudZero spend their time in one or two places. For some it’s AI Signals, and for others it’s Optimize or Anomalies. If Explorer isn’t one of those places, every sign-in starts with a click to get where you need to be. Dates and numbers are another friction. A date like 04/07 means April 7 in the US and July 4 in much of Europe. When the platform shows a format your team doesn’t use, you end up having to convert each value before you can work with it.

Who Built This Dashboard, and Are They Still Here?

You have lived it, no? When production is down, and you have that chart that says something really strange and peculiar, and nobody knows who did it or when. Production is bleeding. There is a spike on screen. And the chart answers everything except the question you actually have: who built this panel, what did they mean by it, and are they still here?

GitKraken Desktop 12.6 Release: Stacked GitHub PRs, Multiple Terminal Tabs

Ready to interact with the stack? GitKraken Desktop 12.6 makes it easier than ever to ship large features and manage multi-task terminal workflows without context switching or losing track of your work. What's new in 12.6: Stacked GitHub Pull Requests: Start a pull request stack against a branch that already has an open PR to break large feature branches into smaller pieces. Stack Visibility Everywhere: View stack position, status, and sequence numbers across the Left Panel PR list, the Pull Request view, and the Commit Graph.

What Is GitOps? Principles, Benefits, and How It Works

With GitOps, you can roll back your cluster with git revert and explain each approved change through a commit log. Routing normal changes through Git and running an in-cluster agent that detects drift from the repository gives infrastructure changes the same review and rollback discipline as application code, and Git preserves their history. This guide covers the four GitOps principles, the pull-based reconciliation workflow, and the tools and practices you need to get started.

Fully Autonomous Software Delivery Demo

See how Harness helps teams move from AI-generated code to production at machine speed. In this demo, Nick Durkin walks through a fully autonomous software delivery workflow inside Harness, showing how teams can review code, enforce policy, run security and LLM scanning, test intelligently, deploy agents, and use Change Advisor to automate approvals with human oversight when needed. You’ll see how Harness helps teams.

Why engineers ignore cloud cost governance (and fixes)

Discover why engineers ignore cloud cost governance and how to build developer cost accountability. Learn how Harness helps empower engineering teams. Engineers often overlook cloud costs due to friction in traditional FinOps tools and a lack of real-time visibility. By embedding automated guardrails and shift-left cost insights into developer workflows, organizations can drive accountability without slowing velocity.

Building Production-ready AI Infrastructure? Start With the Network

AI workloads depend on fast, secure, and scalable access to data across on-premises systems, colocation, cloud platforms, and GPU environments. Here’s how private connectivity can help enterprises move from AI proof of concept to production-ready infrastructure. AI pilots tend to be forgiving. Production isn’t. In the early stages, a team can usually get by with a simple path into a GPU environment, enough bandwidth to test an idea, and a security model that suits a limited group of users.

Intent-driven development: How to guide agents from idea to implementation

Intent-driven development (IDD) is an approach to AI-assisted software development where teams make the desired behavior, constraints, and criteria for success explicit, then give an agent freedom to determine how to achieve the result. As agents take on larger and more autonomous development and maintenance tasks, the implementation itself becomes easier to replace. The important question is whether the software still behaves the way the team intended.

Where do you see organizations hitting their limits?

In this clip, Virtana Chief Product Officer, Amit Rathi explains why more data does not automatically lead to better operations. As system complexity grows, organizations are collecting more telemetry than ever while struggling to turn it into actionable insights. At the same time, rising observability costs are forcing some teams to monitor only part of their environments. Watch the video to learn why intelligence, not just visibility, is becoming essential for modern IT operations.

Your code says one thing. Your cloud says another. Meet EZ Control. #platformengineering

EZ Control brings env zero and CloudQuery together in one product. It discovers nearly 2,300 resource types across AWS, Azure, Google Cloud and Kubernetes, links each one to its code, owner, cost and policies, and closes the gap when what's running drifts from what you intended: drift, security, cost and availability, all under your policies. You choose how much it does, from observe-only to autonomous, with a full audit trail. The same guardrails govern AI agents.

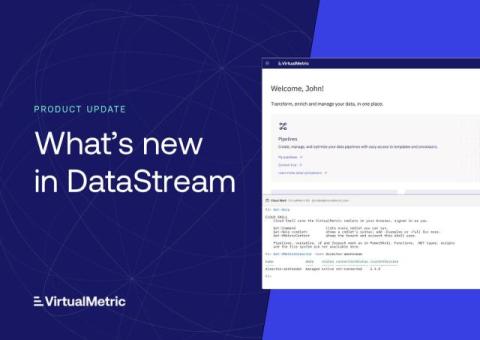
Cloud Shell, New Integrations, and More

VirtualMetric DataStream now includes a PowerShell console in the browser, more than a dozen new integrations, and a new way to collect data from servers and virtualization hosts, where teams choose exactly what they collect. This update also brings guided learning for new users, built-in monitoring rules, and new controls for organizations managing branding and sign-in. Here’s what’s new.

Shipped: Get alerted when AI spend spikes, with the cause attached

AI spend now comes from every department, and it can double in a week without anyone deciding it should. The invoice arrives after the month closes. By then the usual response is a spend cap, which slows every team, including the ones getting real work done with AI. You need to know about spend that breaks its normal pattern while there’s still time to act. The alert should reach the person who can act on it, with proper context and detail.

Introducing Distributed Tracing in Netdata

Netdata now supports distributed tracing. In this webinar, we'll demo the new tracing capabilities for the first time: OpenTelemetry trace ingestion, the new tracing dashboard, and the UI built to let you move from a metric anomaly to the exact span that caused it. For years, teams have asked us to close the gap between infrastructure monitoring and application performance. This release does that. Netdata can now ingest traces via OTEL, correlate them with the metrics and logs you already collect, and surface them in a purpose-built interface designed for speed and clarity.

Fleet Monitoring with Netdata: Live Demo

A walkthrough of monitoring a distributed fleet with Netdata, using a simulated fleet of about 1,000 devices spread across regions. We show how the whole fleet reports into a single view: per-second metrics from every node, grouping by region and by customer, a map view that colors each device by health, filtering and saved views for different teams, and an AI-assisted investigation that scans the fleet for anomalies and points to likely causes.

AI Tooling Comes to Cycle - Announcing Cycle's Hosted MCP

TL;DR - We made a way to use Cycle with AI models for doing things like deploying applications faster and diagnosing complex issues. If you'd like to get started right away with Cycle's Hosted MCP, check out our documentation. Today, we're launching a brand new way to interface with the Cycle Platform, that just a year or two ago would have felt entirely like science fiction. Our first ever AI-oriented tooling, Cycle's Hosted MCP, is live today.

Megaport Advanced Services: From Network Design to Deployment

Network changes often stall after the design is done. See how Megaport Advanced Services helps teams move from planning to implementation and support. Ask a network team where their last big network change got stuck and you’ll rarely hear “we couldn’t work out the design.” The completed design is usually sitting in a document somewhere, reviewed and signed off. What stalls is everything needed after that. Somebody has to write the runbook. Somebody has to sit in the 2 a.m.

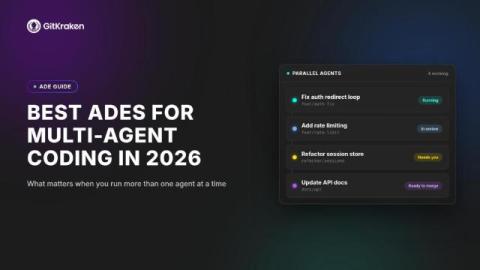
Best ADEs for Multi Agent Coding in 2026

Running one AI coding agent is productive. Running five of them at once across three repositories? That’s a coordination problem. Agentic development environments (ADEs) give you a single surface to orchestrate multiple agents, review what each one changed, and get code merged. Kepler by GitKraken is one of the most capable options in this growing category. It’s built around agent-agnostic orchestration and Git workflow control from backlog to merged PR.

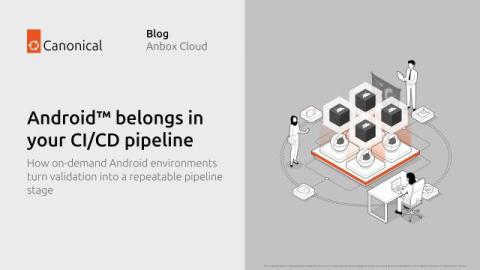
Android belongs in your CI/CD pipeline

How on-demand Android environments turn validation into a repeatable pipeline stage In the first article, we looked at automation: how Android environments can be created and managed programmatically. In the second, we looked at scaling: how shared infrastructure can make those environments available to more developers, tests, and workloads. This third article looks at the next step: integrating those environments directly into CI/CD.

Cycle's Hosted MCP Release Announcement

We are stoked to announce that we have released our very own hosted MCP that allows you to use natural language to interact with and control anything you have running on Cycle.io. Alexander Mattoni, CTO and co-founder of Cycle, shares a few scenarios where the MCP can be useful. With the MCP, Cycle users can communicate with the Cycle platform directly from their preferred AI tool. In minutes, users can provision a new server, deploy an application, or troubleshoot an issue directly from their AI assistant like Claude, Claude Code, ChatGPT or Codex.

Building Investigations: what it takes to build an AI SRE

At incident.io, we've spent the last two years building Investigations, our AI SRE. When you get paged, it starts investigating straight away, looking across your telemetry, recent deploys, past incidents, docs and code, and posts what it's found in your incident channel (or on your phone, if it's 2am and you're still deciding whether you need to get out of bed). By the time you open your laptop, you're starting at step six of triage rather than step one.

EVOLVE 2026 Recap: Operational Excellence for the AI-Native SDLC

Last week we hosted our annual conference, EVOLVE, where global engineering leaders came to talk through the realities of building AI-native SDLCs. When asked to name the biggest friction point in their software lifecycle, attendees gave telling answers: ‘reviewing changes’ took 36 percent, ‘measuring impact’ took 35, and ‘building’ drew zero votes.

The new Civo dashboard is in beta: Try it today

First previewed on stage at Civo Navigate London, the new Civo dashboard is now in beta, and getting to it just got a lot easier. Starting today, you'll see a Try it now banner at the top of your current dashboard at dashboard.civo.com. Click it to head to the new dashboard, sign in with your usual Civo account details, and you're in. You can also go directly to dashboard-manager.civo.com. Look for the Try it now banner in your current dashboard.

How Hybrid WAN Is Transforming Enterprise Network Connectivity

Enterprise networks are evolving as businesses adopt cloud applications, remote work, distributed offices, and connected devices. A hybrid WAN solution can help organizations combine different connectivity options while supporting the performance, reliability, and flexibility required by modern business operations.