Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

Featured Post

Monitoring CloudNativePG: What Changes When the Operator Owns Your Logs

Postgres operators like CloudNativePG (CNPG) have lowered the threshold for running highly available Postgres clusters on Kubernetes. Failover, replicas, backups, and rolling upgrades are handled by the operator, along with helpful niceties like automatic configuration of essential extensions. A few changes to a YAML manifest can provide a lot of value very quickly.
On Release Days We Wear Teal for release 4.20.3

In this episode, Leon sugars up and then opens the wrapper on the sweetest new bites in the Cribl candy dish - Cribl Detect, updates to Apps including app certification, a new way to use Terraform to automation Cribl rollouts, notifications for data loss, and a name change - along with our running Crib-bits and New-2-U segments. For more information, check out these links.

How to Troubleshoot Intermittent Network Issues After They Happen

One of the most frustrating challenges I faced as a network engineer was troubleshooting problems that had already disappeared. A user would call and report that an application was performing terribly. A site would become unusable for several minutes. Voice calls would break up. File transfers would suddenly slow to a crawl. Then, by the time I started investigating, everything would be working normally again.

Monitoring the Monitor: When One of Our Uptime Vendors Went Quiet for 27 Hours

DNS Check watches its own infrastructure with several layers of monitoring, including DNS Check itself and third-party uptime monitoring services. One of those vendors polls a private health endpoint on our servers every five minutes, from probes around the world. That endpoint runs a set of internal checks (disk space, mail delivery, background job queues, DNS resolvers, and more) and returns an error if any of them fail. If it errors or stops responding, the vendor alerts us.

Scout Monitoring Is Now in Claude's Connector Directory

A customer messages support: checkout feels slow today. You open Scout, find the endpoint, open a trace, spot the query, copy it into Claude, and ask what’s wrong with it. Each step is quick, but together they add up to a lot of tab switching to answer one question. Scout Monitoring is now available in Claude’s connector directory. Connect it once and Claude can look at your production data directly.

Introducing AI Observability: Trace Every AI Agent Request from Prompt to Pod

TL;DR Logz.io AI Observability provides end-to-end tracing for AI agents and LLM applications. Built on OpenTelemetry, it lets you trace every request from prompt to backend service, visualize multi-step agent execution, isolate root causes across models and infrastructure, and track token usage per step, all alongside your existing logs, metrics, and traces.

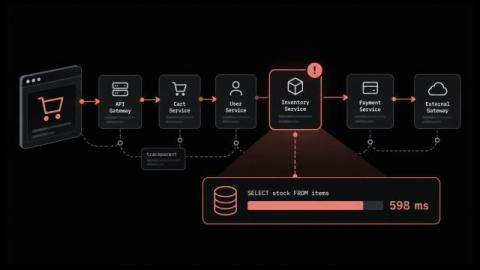
What is Distributed Tracing? How a Request Becomes a Trace

A checkout request leaves the browser and touches seven services before anything comes back. Seven dashboards light up. Every one of them reports a healthy number for its own service, and every one of them is telling the truth about a different slice of the work. Nobody measured the request. That gap is what pushed tracing in beside metrics and logs as a core signal of observability. In this blog, you will: By the end you will open a trace and say where the time went.

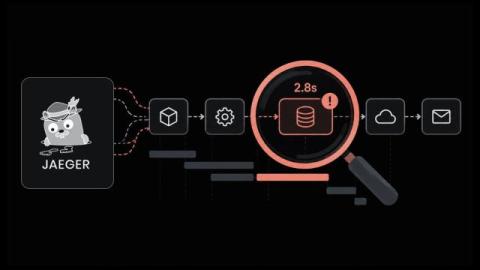
What is Jaeger Tracing and How does It Locate Slowdowns Across Microservices

Why does a checkout or login take several seconds when CPU and memory look normal on every server? In microservices, one click can travel through a long chain of components before the user sees a response. Any one of them can hold the request up, and server graphs won't tell you which. Logs show what each service recorded. Metrics give you averages. What's missing is the path one request took and the place it lost time, and Jaeger tracing records exactly that.