Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

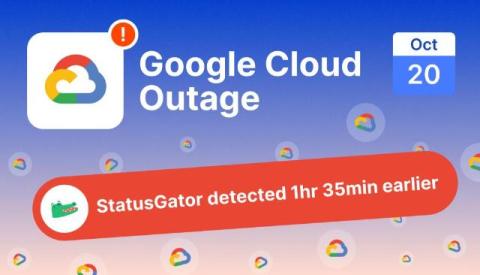
Google Cloud outage on October 20, 2026: a europe-west2 power event and 171 possibly affected services

A power event in Google’s europe-west2-b (London) zone triggered a wide Google Cloud outage on October 20, 2026, taking down dozens of services including Cloud SQL, BigQuery, Compute Engine, and Kubernetes for customers across the UK and beyond. StatusGator sent an Early Warning Signal at 07:02 UTC, 1 hour and 35 minutes before Google Cloud publicly acknowledged the incident at 08:37 UTC. The ripple effect was wide: StatusGator tracked 171 other services showing signs of impact during the outage.
Ship SecOps changes like software: Modernizing the SOC without breaking what works

Cribl gives security teams control over their data: what they collect, where to send it and how much to keep. The rest of the SecOps stack hasn’t kept pace. Detections, parsers and configurations spread across SIEMs, pipelines and data lakes still change by hand, so every cost cut, migration or new source turns into weeks of manual validation, and plenty of planned changes never happen at all. SecOps as Code closes that gap: every change ships like software, with testing, version control and rollback across the entire infrastructure.

Application Metric or Log? Which should you use?

Sentry offers both "Application Metrics" and "Logs", but both can seem pretty similar. Both logs and metrics are just a collection of attributes attached to a name in your code. Both can be counted, visualized, or alerted on. Both are not sampled by default. So how do you know which to choose? In this video, we'll briefly go over a few examples of when to use logs and when to use metrics. TLDR; Logs are designed for debugging and may be temporary or likely to change when problems arise. Metrics on the other hand are stable, purposely placed events used to track user behaviors.

Five things you can do with Sentry's Agent Tracing

AI-powered apps are hard to debug without observability. From one run to another, AI produces different results, goes down different paths, and you’re none the wiser as to why it’s happening. Agent Tracing bridges the gap between prompt, tool calls and final output, all within the context of your app. If things break (it always does at some point, we know from experience), you get everything in one complete trace.

The Hard Part of Incident Remediation Is Knowing When to Act

A critical application slows overnight. Monitoring identifies an unhealthy component, and an engineer finds a familiar remedy: restart a service. The command takes seconds. Determining whether the restart will restore the application or disrupt another dependency takes far longer. That is the real challenge in enterprise incident remediation. Most IT teams already know how to automate a task.

Elastic is a Strong Performer in The Forrester Wave for AIOps Platforms, Q4 2026

Open architecture, explainable AI, and full context Elastic was named a Strong Performer in The Forrester Wave: AIOps Platforms, Q4 2026, which evaluated 10 providers across 24 criteria. Forrester gave Elastic the highest possible scores in five criteria: algorithmic trust and explainability, observability as code (OaC) and GitOps alignment, AI stack and semantic observability, sovereign deployment and data isolation, and pricing flexibility and transparency.

Match monitoring depth to workload needs with Infrastructure Basic

A back-office server that runs out of disk space can interrupt an important internal workflow. A process that stops on a staging host can delay development. Although workloads like these might not require application-level instrumentation, teams still need to know when the hosts that support them require attention. Without a monitoring solution tailored to these requirements, teams have to apply more monitoring than the workload needs, maintain a separate tool, or accept a gap in visibility.