Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

What Happens When an SLA is Breached and How to Recover Customer Trust

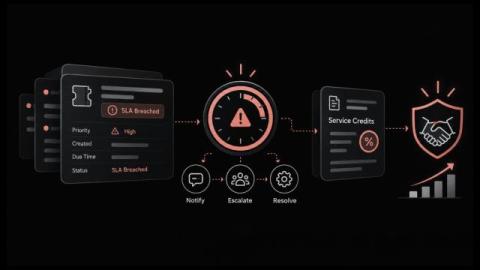
What does your organization owe a customer when a priority ticket misses its resolution target by forty minutes? For most service providers and internal service desks, the answer stays unclear until the customer asks for a credit or a manager asks why the monthly SLA report shows a miss. By then, the facts that decide the outcome, such as when the clock started, whether it paused and who was told, are scattered across tickets, emails and chat threads.
SOX ITGC Controls Checklist for IT Service Management and Year-Round Audit Readiness

How much of your SOX audit season goes into rebuilding proof of work that was already done? Access was approved, the change went through review, the backup ran, yet the evidence lives in email threads, chat messages and a spreadsheet someone updated last quarter. When an auditor asks for a complete list of production changes, IT staff have to pull records from several places against a deadline.

Cloud Shell, New Integrations, and More

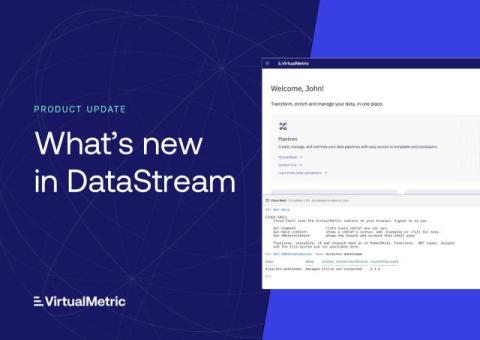
VirtualMetric DataStream now includes a PowerShell console in the browser, more than a dozen new integrations, and a new way to collect data from servers and virtualization hosts, where teams choose exactly what they collect. This update also brings guided learning for new users, built-in monitoring rules, and new controls for organizations managing branding and sign-in. Here’s what’s new.

Monitor warehouse data quality beyond pipeline health

You get a Slack message from the VP of Sales: They have asked an AI agent connected to Snowflake for the past quarter’s revenue and the numbers look wrong. First, you verify the agent’s query and, when that looks fine, check the pipelines that populate the underlying table. All jobs completed, the data is recently refreshed. Then it’s time to check the logs for errors. Nothing.

Dr. Cat Hicks on the Psychology of Software Teams

What happens when a software engineer who has put their entire identity into being the resident expert of an obscure technology or language with ten years of experience and who knows the codebase like the back of their hand now has to compete with AI? Psychologically speaking, according to Dr. Cat Hicks, author of The Psychology of Software Teams and founder of Catharsis, that's called identity threat, and it's a surefire way to feel unsafe. We were honored Dr.

OnlineOrNot updates from June through August 2026

It's been a while since I last updated you on what's new in OnlineOrNot. For the most part, I've continued making it useful for software teams: there's now an MCP server, I've improved the terraform provider significantly, and there's a new TypeScript SDK. You can also (finally?) monitor DNS/TCP with it.

Best Monitoring Tools With MCP Servers for AI Coding Agents (2026)

Your AI coding agent can read your code, run your tests, and open a pull request. Until recently it could not see what that code does in production. MCP servers from monitoring vendors close that gap. Connect one, and Claude Code, Cursor, or Copilot can pull the error, the trace, and the slow query behind a bug report without you copying anything out of a dashboard. Most major monitoring vendors now offer an official MCP server. But they aren’t interchangeable. Some only expose errors.

Grafana Mobile to Desktop Companion App

The Grafana Mobile App lets you triage alerts with help from Assistant from your phone. You can declare an incident or trigger an investigation into an incident in order to get more information so that by the time you get to your desktop, everything is ready for you. Grafanistas Ignacio and Florian go through a use case deep dive, demonstrating the value of the Grafana Mobile Companion app by triggering an investigation, talk to Assistant, and have all the data you need to resolve an incident - all from your phone.

Fleet Monitoring with Netdata: Live Demo

A walkthrough of monitoring a distributed fleet with Netdata, using a simulated fleet of about 1,000 devices spread across regions. We show how the whole fleet reports into a single view: per-second metrics from every node, grouping by region and by customer, a map view that colors each device by health, filtering and saved views for different teams, and an AI-assisted investigation that scans the fleet for anomalies and points to likely causes.