Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

Tempo 3.1 release: new features for Kafka, TraceQL metrics updates, trace redaction, and more

Building on the major release of Tempo 3.0, Tempo 3.1 is here, delivering community-contributed Kafka client improvements, query-based trace redaction, sampling-aware TraceQL metrics, and more. Together, the updates in 3.1 make it easier to operate Tempo, get accurate insights from your trace data, and investigate issues more efficiently. You can continue reading and check out the video below to learn more about the latest features.
Telemetry Talks ep 8 - Fireside chat with OpenTelemetry maintainers

Telemetry Talks episode 8 is here We sat down with OTel maintainers to talk about the future of the community, GenAI semantic conventions, contributing beyond code, OTel in Practice, and what they’re currently building, writing, organizing, and experimenting with across the CloudNative and OpenSource ecosystem. A conversation about where OTel is today and what comes next. Playlist Resources for Further Learning.

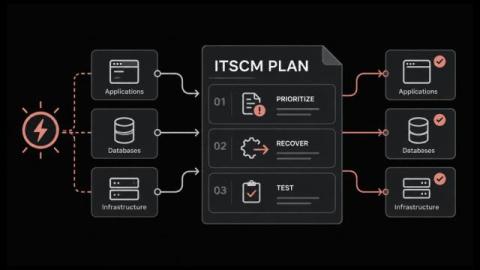
IT Service Continuity Management: How to Build an ITSCM Plan

Most IT teams have a recovery plan somewhere. It was written for a disruption that has not happened yet, and tested less often than anyone admits. The gap rarely sits in the technology. Nobody agreed which services come back first, or how fast. There was time to settle that calmly, and it went unused. IT service continuity management is the ITIL practice that settles those questions in advance. In this blog, you will: By the end you will know what belongs in an ITSCM plan and who has to agree to it.

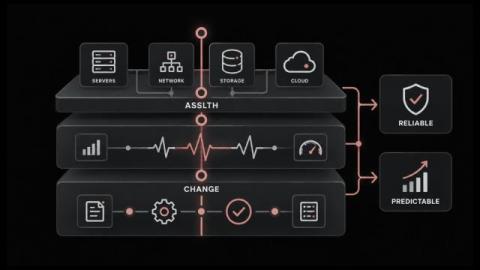
How IT Infrastructure Management Keeps Services Reliable and Costs Predictable

When a business application slows down, how fast can your organization trace the cause to a server, a network link, storage or a cloud instance? Often it comes down to who's on call that day, since asset, observability and change data are scattered across separate systems. Engineers then check each tool one at a time while customers wait and the cost of the outage grows. IT infrastructure management solves this by keeping asset records, health data and change history in order before an incident starts.

How Etsy gets its mobile apps ready for peak traffic

Most advice about surviving a traffic spike is about capacity. Scale the fleet, warm the caches, load test the checkout path. All of it assumes you can fix whatever breaks the moment you find it. Mobile apps don’t work that way. I spent an hour on a workshop with Jay Henry, a senior engineering manager at Etsy who owns engineering strategy across three teams covering CI, build, test, release, observe, and SRE. Jay’s take: a web team having a bad day can revert in minutes.

Show off your uptime with SLA badges.

Your uptime is probably better than your customers think. But the proof sits in your UptimeRobot dashboard, where only your team can see it. Starting today, you can put it on your website. SLA badges let you set an uptime target for your monitors, then embed a live badge that shows the uptime you actually delivered, colored against that target. Add it to your site footer, your docs or your GitHub README, and get the result by email at the end of each period.

How Unified Cloud Monitoring Closes Hybrid IT Blind Spots

Modern IT runs across public cloud, data centers, containers, SaaS, networks, and AI services. Cloud monitoring delivers more value when those environments share the same observability context, giving teams a clearer way to troubleshoot service issues, manage cloud spend, and support AI-assisted operations.

OpenAI outage on September 14, 2026: "some tools are temporarily unavailable" errors hit ChatGPT worldwide

ChatGPT’s tools and workspace features failed for users around the world on September 14, 2026, with the message “Some tools are temporarily unavailable” blocking spreadsheet and document creation, Codex, Projects, file reading, and dictation while core chat largely kept working. StatusGator sent an Early Warning Signal at 14:41 UTC, 1 hour and 17 minutes before OpenAI publicly acknowledged the incident at 15:58 UTC.