Operations | Monitoring | ITSM | DevOps | Cloud

Sponsored Post

From Zero to Managed in Record Time

If you've spent any time in the SAP ecosystem, you know the "Configuration Tax." It's that invisible, compounding fee paid in hours, manual effort, and caffeine. SAP teams pay tax every time new systems or integrations are brought under observability and management. For years, the industry accepted that observability required a heavy initial lift. Changes in monitoring policy or underlying infrastructure triggered additional effort often parallel and size and scope to initial onboarding.

Security KPI Dashboards for SAP Operations Teams

An Avantra SAP security dashboard gives SAP operations teams one view of SAP security KPIs, covering SAP Notes and HotNews status, system hardening, user access risk, and audit compliance across on-premises, hyperscaler, and RISE with SAP systems. Security teams have their own tools: a SIEM, a SOC console, vulnerability scanners. SAP operations teams usually don’t.

Which Ruby Framework is Best? Use This Decision Tree

Search "best Ruby frameworks" and Google will give you a dozen posts that all say the same thing: a table ranking Rails, Sinatra, Hanami, Grape, and Roda, followed by a paragraph on each. None of them tell you which one to use for your project. That's because a ranking doesn't fit this problem. These frameworks aren't better or worse versions of each other. They're built for different jobs. Rails optimizes for full-stack productivity. Hanami optimizes for architectural boundaries.

Which Python Frontend Framework Is Best? Use This Decision Tree

Search "best Python frontend framework" on Google and you'll get the same page over and over: a listicle ranking Streamlit, Gradio, Dash, NiceGUI, Reflex, and Flet, followed by a paragraph on each and a score out of ten that doesn't mean anything. None of them tell you which one to use for your project.

How to Monitor an Ubuntu Server (Step by Step)

Summarize with ChatGPT Claude To monitor an Ubuntu server, watch seven things: CPU, load average, memory, disk space, disk I/O, network and whether the machine is up at all. You can check all of them in under a minute with commands that ship with Ubuntu (top, free, df, vmstat) plus iostat from the sysstat package. That is fine while you are logged in.

How to Get Alerted When a Server Goes Down (Email, SMS, Call)

Summarize with ChatGPT Claude To get alerted when a server goes down, run a check from outside the server and send its result to a channel that reaches a human. That check can be a cron script on a second machine that pings the host and tests a port, an external ping or TCP port monitor, or an agent on the server whose silence opens an incident. Email and Slack are fine for the record. For a server that matters at 3am, the alert has to escalate to SMS and then a phone call when nobody acknowledges it.

What Is DORA Compliance? The Digital Operational Resilience Act Explained

The Digital Operational Resilience Act has applied to EU financial firms since 17 January 2025. The first year was mostly paperwork. In year two, supervisors want proof, and most of that proof sits with IT operations. DORA joins the other rules on your cybersecurity compliance list, with much tighter clocks. A major incident needs its first report within 4 hours of classification. In this blog, you will: By the end, you will know what DORA compliance asks of your IT team and where to begin.

What Is AI Networking? The Two Pillars and Which One You Need

AI networking means two different things. Vendors rarely say which one they are selling. One is using AI to run the network you already have. The other is building network infrastructure fast enough to train AI models. Both pillars are real, and they solve completely different problems. Most network teams only ever need the first. In this blog, you will: You will finish knowing which pillar your own question belongs to.

Hyperping MCP: Run Incidents, Status Pages and Maintenance

Summarize with ChatGPT Claude The Hyperping MCP server now has 49 tools: 28 that read and 21 that write. An agent connected from Claude Code, Cursor, Codex or another MCP client could already manage monitors, publish a status page incident and schedule maintenance. It can now do most of the rest: declare an incident and page on-call, acknowledge and escalate it, correct what was posted on the status page, create and configure status pages, and reschedule, end or cancel maintenance.

Autonomous IT operations: Scaling business without scaling IT complexity

Autonomous IT operations use AI, operational data, observability, and automation to enable IT environments to detect issues, understand their context, determine the appropriate response, and act with minimal human intervention. As businesses grow, IT environments rarely stay simple. More employees, endpoints, applications, and cloud services generate even more alerts, incidents, and operational work. The traditional model scales linearly: more environment means more manual effort.

Is Your MSP Pricing Model Inhibiting Your Business Growth?

One of the questions MSP owners ask most often isn’t about tools or tech. It’s about pricing. Not just what to charge, but something closer to, “Is the way I’m charging actually built to support where I want this business to go?” We’re going to dig into why pricing models matter just as much as service delivery, how the most common approaches help or hurt as MSPs scale, and what to look at when margins feel tighter than they should.

Amazon WorkSpaces Applications In-Console Monitoring

Recently, Amazon announced WorkSpaces Applications in-console monitoring. This is a big shift forward for AWS, who is quietly building market share with their Amazon WorkSpaces Applications (previously called Amazon AppStream 2.0) virtual applications offering. This announcement validates that observability matters for Amazon WorkSpaces Applications customers – they need to see what’s going on in their virtual application and desktop fleets, hosts and sessions.

What DEX Leaders at Truist and GSK See That Your Dashboard Doesn't

An HR colleague at GSK was having trouble with her screen. The default fix was the obvious one: give her a bigger monitor. She turned it down. What she truly needed was an accessibility tool to magnify what was already on the screen she had. Sarah Jones, Senior Director, Global Site Operations and Executive Services at GSK, shared that example in a recent HR Grapevine feature on Women in DEX, the global collective Nexthink launched in March.

Latest Log Management Strategies in 2026: From Raw Logs to Business Value

Discover the latest log management strategies for 2026 and learn how AI and automation turn raw logs into actionable insights. See how modern log management can reduce investigation time, improve incident response, control costs, and strengthen visibility across hybrid and multi-cloud environments.

Extend Datadog RUM and Product Analytics to Shopify and Salesforce

Many revenue-critical interactions, such as ecommerce checkouts and customer portals, run on Shopify and Salesforce. But engineering teams have less control over the frontend runtime on these platforms, and this lack of control can make user monitoring difficult to implement and maintain. These monitoring limitations can leave gaps in visibility across important parts of the user journey.

Cribl On Your Coffee Break Episode 20 - Keep learning, keep growing, keep Cribl-ing!

As we wrap up our month-long series, we look at the resources that will help you keep learning and growing - from Cribl University to Sandboxes to the Cribl Community and beyond. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

How to Fix Slow DNS Lookups Across Clients, Resolvers and Networks

Why does every page, login and business application hesitate before anything loads, even when bandwidth graphs look healthy? That pause usually comes from name resolution: no connection starts until its hostname has been translated into an IP address, and whatever time that translation takes is added to the request. Slow DNS seldom shows up as a clear error.

IT Offboarding and How to Revoke Access Without Leaving Security Gaps

When someone leaves your organization, how sure are you that every account they could reach was closed? Most IT offboarding starts by disabling the employee's main login account, and that step usually works. The risk comes from the other accounts, tools and devices the person used that the main account does not control. These include personal API tokens, shared vendor portal logins, laptops still with a courier and SaaS tools bought on a department card.

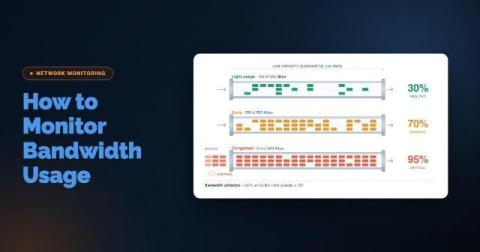
How to Monitor Bandwidth Usage: Techniques, Tools & Troubleshooting

Your Internet link averages 40% utilization, yet users still complain that calls drop and SaaS apps crawl every morning at 9:00. Averages are where bandwidth problems hide. A five-minute polling interval can smooth a 30-second saturation spike into a flat, healthy-looking line. A total-usage graph also won't tell you whether the traffic is a backup job, a compromised endpoint, or an ISP delivering less than you're paying for.

How to Scale an MSP Team That Won't Break

Every MSP hits a point where the business is growing, the work is technically getting done, and it still somehow feels worse than it did a year ago. Tickets slip through. Two techs touch the same escalation, and neither one closes it. Your best engineer is doing a password reset at 4:45 on a Friday because nobody else picked it up.

Best Kubernetes monitoring tools compared in 2026: A buyer's guide for SRE, platform engineering, and ITOps teams

Monitoring Kubernetes in production is structurally different from monitoring traditional servers: pods are ephemeral, nodes autoscale, and the layered resource model—containers, pods, nodes, namespaces, deployments, services—creates an observability challenge that tools built for static infrastructure were never designed to handle.
Sponsored Post

How to cut AI infrastructure spending without reducing GPU capacity

Every infrastructure leader running AI workloads is staring at the same problem: GPU spending keeps climbing, the finance team wants a justification, and the operations team is caught between proving the infrastructure is necessary and explaining why the returns aren't keeping pace with the investment. The instinctive response is to either procure more capacity to handle growing demand or cut back on what's already deployed. Neither actually solves the problem.

More flexible color customization for status pages

We’ve expanded status page color customization to give you more control over your branding and support a wider range of color combinations. Previously, you could select one primary color and one text color for each theme. These colors were applied across multiple elements, which could make it difficult to achieve the right contrast or match certain brand styles. Now, you can customize individual parts of your status page separately for both light and dark themes.

Why Manual SAP Patch Validation Fails

Validating SAP patches means answering three questions before anything reaches production: does this apply to my systems, what does it depend on, and what breaks if it goes wrong? For most SAP teams, the answer still comes from manual work. Someone reads the note, checks a component version by hand, updates a spreadsheet, and trusts memory for the rest. That can work, but it depends on one person’s head, or on a spreadsheet that slowly goes stale. The failure mode is usually not a bad patch.

The Human Side of Innovation: Sheetal Kalra on Trust, Simplicity, and SolarWinds in Africa

"Channel is the heartbeat of any vendor conversation...if your product is not good, the channel is not going to be doing the miracle." In this episode of SolarWinds World Tour Conversations, we sit down with Sheetal Kalra, Regional Channel Manager for META, to discuss why a strong channel ecosystem is essential for bringing in strong customers. We explore the technology-driven nature of channel sales, the 2026 modifications to simplify the Partner Program, and how partners are successfully navigating network and observability challenges for their clients.

Transaction Check Basics in less than 3 minutes

In this video, we explore the basics of Transaction Checks on Uptime.com, an advanced multi-step monitoring tool for website elements. Learn how to create customized scripts to mimic user actions such as visiting a site, filling out forms, and clicking buttons. We walk through a step-by-step guide on setting up a Transaction Check to monitor a login process, including navigating to a URL, validating HTTP status codes, and using browser developer tools to configure field entries. Discover different monitoring intervals and tips for organizing your checks with tags and location settings.

What is a CRC Error and How to Find the Faulty Link Before It Slows the Business

Why does a switch port look healthy on every dashboard while people on that floor keep reporting dropped calls and slow file transfers? Often the cause is CRC errors, a port counter that most dashboards do not show by default. Each CRC error means a unit of data arrived damaged and the switch discarded it. Put simply, a CRC error tells you the receiving device noticed the data changed somewhere in transit.

What Is AgentIQ? Inside meshIQ's In-Flow Governance Control Plane for AI Agents

Enterprises are running AI agents nobody has counted, holding credentials nobody reviewed, taking actions nobody can audit. AgentIQ governs what agents are allowed to do at the moment of action—inside the execution flow—not after the fact through a gateway watching from outside.

Introducing Selector Foundry: Agentic NetOps

Network operations teams have heard plenty about AI this year. Most of it answers the alert in front of it, then hands the rest of the incident back to an engineer. Someone still has to correlate the evidence, find the cause, prepare the fix, and prove it held. This week, we announced Selector Foundry, the agentic NetOps solution built into the Selector platform. Foundry adds a team of specialized AI agents on top of the full-stack observability and AIOps foundation our customers already run.

Cribl On Your Coffee Break Episode 19 - A Cribl Grab bag: Guard, API/SDK, Insights, and FinOps

In our penultimate episode of the series we try to hit all the things that didn’t fit anywhere else - Cribl Guard, the API/SDK, Insights, and the FinOps center. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Visualize Data Your Way, with Intelligence Dashboards Built for Your Stack

When something goes wrong in production, you do not want to spend the first five minutes rearranging charts. You want the error rate, throughput, queue depth, memory, and view metrics that show when customers are having issues while using your app.

What if your agent's hallucinations had a budget? How to start using SLOs for agent behavior

At Grafana Labs, observability is what we do. So as we started building AI agents, we naturally reached for the same instincts we bring to every system: measure it, set targets, and make reliability something you can reason about instead of hope for. That instinct led us somewhere unexpectedly useful. It turns out one of the oldest ideas in reliability engineering, the error budget, maps beautifully onto one of the newest problems in software: how do you know if an AI agent is actually any good?

Using TypeSafe's Jev for evals in Datadog Agent Observability

TypeSafe AI released Jev in September 2026 to do one thing: make decisions. Give it a state (a string or a JSON object) plus a set of typed questions, and it returns typed answers with probabilities. It never explains itself, and that constraint is the whole idea. Evaluation pipelines have spent the last two years asking text generators for yes/no verdicts, wrapping the reply in a JSON schema, and paying generation prices for what amounts to a single bit.

EU data residency for Hosted OpenSearch on Logit.io

EU buyers asking for Hosted OpenSearch with data residency usually mean something precise: indexes and cluster storage should land in a European data centre that lines up with GDPR expectations and the geography named in the DPA — not a US default that security later has to unwind. On Logit.io that choice is an account-level data storage region, not a free toggle on every stack. Get the first stack right and every later OpenSearch or log stack in that account follows.

How to Check Bandwidth Usage Across Your Network

Most bandwidth problems get investigated after the complaints arrive, and by then the traffic that caused them has moved on. The numbers you need sit in several places at once. A laptop knows its own traffic. The router knows what leaves for the internet, and only the switches see how much network bandwidth moves inside the building. Checking bandwidth usage at the right layer saves hours of guessing. Most of the methods ship with hardware you already own.

Best Practices for Effective Healthcare Networks

An effective healthcare network is the IT infrastructure that keeps clinical and operational services reachable, responsive and diagnosable across hospitals, clinics, imaging centers, laboratories, remote sites, cloud services and vendor connections. A device can be up while Electronic Health Record (EHR) access, Picture Archiving and Communication System (PACS) retrieval, telehealth or a wireless clinical workflow is still slow or unavailable.

Tech Talk #15 - How VictoriaLogs Go Fast

Go is fast because of decisions most engineers never see. Jesus walks through how VictoriaMetrics uses Go to process logs at scale, the tradeoffs behind those choices, and what breaks if you get them wrong. If you write Go or run log pipelines, this is 30 minutes worth blocking your calendar for. Resources for Further Learning.

What is data mesh architecture? Data mesh vs. data fabric vs. data lake [Quick Question Ep. 1]

What is data mesh architecture, and how does it compare to data fabric and data lake? In this episode of Quick Question, we explain how data mesh connects distributed data sources without duplication or centralization, keeping data at its original location while giving authorized users secure, low-latency access, even in mission-critical and bandwidth-constrained environments.

Protecting releases, fixing bugs with Sentry & LaunchDarkly

As fast as AI can generate code, getting that code to production still tends to slow things down. It makes sense. When code breaks in production it’s not just a nuisance; it’s a full-blown incident. And can have big impacts for your company and customers. The question really is, can you catch broken code as quickly as you can ship it? In this livestream, Peter McCarron, Technical Product Marketing at Sentry, is joined by Tom Totenberg, Head of Release Automation at LaunchDarkly, to talk about how you can automatically protect new releases from code merge to error detection.

ITSM to Deep Observability with ServiceOps & ObserveOps | Motadata Webinar

In this webinar recording, discover how ServiceOps and ObserveOps connect IT service management with deep observability. Learn how IT teams can identify root causes faster with unified visibility across incidents, metrics, logs, traces, applications, and infrastructure. Don't forget to like, share, and subscribe for more insights on ITSM, observability, AIOps, and IT operations.

When Peak Business Demand Depends on Information Nobody Sees

Modern enterprises no longer operate as isolated systems. Every customer order, supplier commitment, shipment, invoice, and payment relies on information moving seamlessly across a growing network of applications, partners, and business functions. In many SAP-driven organizations, SAP IDocs serve as one of the primary mechanisms for exchanging business information between various SAP and non-SAP systems. Most business users never see them, never interact with them, and often never hear about them.

How does fragmented telemetry affect an AI system's ability to reason what's really happening?

Fragmented telemetry limits what AI can understand. When logs, metrics, and traces remain siloed, AI sees individual signals instead of the full story. That can lead to incorrect conclusions and unexpected outcomes. This is where AI observability matters. Virtana connects telemetry across the stack, giving AI the context it needs to correlate signals, understand dependencies, and identify what is really happening.

The human we find in our machines

There is a peculiar moment that happens when talking to AI. You ask it to rewrite an email, it does a good job, and you type, "Thanks!" Then, almost without thinking, you add, "Sorry, one more thing." It is software. It cannot be kept waiting, interrupted, or offended. Still, somehow, you have developed the manners. Then the questions get a little more personal.

S/4HANA Migration Monitoring: A Practitioner's Guide

Effective S/4HANA migration monitoring closes the operational gaps that quietly undo complex SAP transitions. Avantra eliminates the seams between phases where visibility typically disappears exactly when it matters most: the shift from baseline to cutover, the blind spot inside a parallel run, and the rushed handoff from legacy tools to Cloud ALM. This guide walks through every phase of migration monitoring in order, with a checklist you can adapt to your own project.

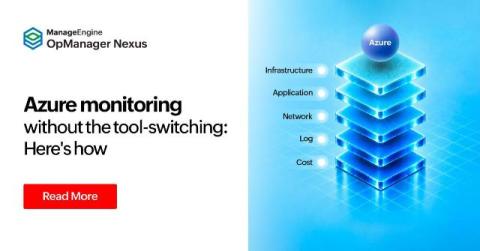
Fragmented Azure visibility? One Azure monitoring tool that tracks every layer

Most Azure monitoring setups look the same: Azure Monitor for metrics, Application Insights for apps, Log Analytics for logs, a separate tool for network, and another for cost. Each works in isolation. None of them talk to each other when something breaks. The Azure monitoring tool in ManageEngine OpManager Nexus consolidates infrastructure, application, network, log, and cost visibility data into a single console.

Server Performance Monitoring: 10 Metrics Every SRE Should Track

How do you know a server is about to cause problems before it actually does? You track the right metrics. Not all of them, just the leading ones that consistently surface performance issues before they worsen into outages. This guide breaks down the 10 server performance monitoring metrics every SRE should have on their radar.

Find answers in your logs faster with Datadog's Tap to Parse

Logs are easiest to investigate when the values that matter are already captured as attributes. When those values are buried in a log message, even a straightforward question such as filtering on a status code, graphing the duration of a request, or following a unique transaction across a set of logs requires writing complex regular expressions or Grok patterns.

What Is Shadow IT? Meaning, Risks, and How It Shows Up in Your Asset Inventory

Most shadow IT starts with a marketing team that needed a file-sharing tool on Tuesday. The next procurement cycle was six weeks away. That gap keeps widening. According to Gartner, 75 percent of employees will acquire, modify or create technology outside IT's visibility by 2027, up from 41 percent in 2022. Shadow IT is the name for that tech. IT asset discovery is where it first shows up. In this blog, you will: By the end, you can turn shadow IT into a weekly review queue.

Monitor Third Party Services With UptimeRobot.

Your checkout might run on Stripe, your files on AWS, and your images on a CDN. When one of those providers has an incident, part of your product breaks with it, and your own monitors can stay green the whole time. Starting today, UptimeRobot monitors beyond your own infrastructure. Third party monitoring lets you add the services your product depends on, select the components you actually use, and get an alert through your existing channels when their status changes.

Status Pages: Publish Post-Mortems on Your Incidents

Status pages now have a place for the last step of an incident: the post-mortem. Once an incident is resolved, you can write what happened, why it happened, and what you are changing, then publish it on the incident itself. Until now, the updates you posted during an outage ended with "Resolved", and the explanation lived somewhere else: a blog post, a PDF sent to a few customers, or an email thread. Customers who read the incident on your status page never saw it.

Configure RUM SDKs remotely from Datadog

Datadog Real User Monitoring (RUM) SDK settings live in your application code, so changing how the SDK collects RUM data has traditionally required shipping a new application version. These configuration changes can include adjusting sampling rates, enabling Session Replay, or changing which events the SDK collects. For mobile teams, this means that updates often sit in app store review for days or weeks before users start adopting the new version. Full user adoption can take weeks or months longer.

Correlating Business and IT Events: The Path to Business Process Observability

At 9:40 on a Tuesday morning, an order sits unconfirmed in the fulfillment process. Two systems away, a queue depth ticks upward in the integration layer. Both events are recorded. Neither is connected to the other, so nobody escalates nothing is technically down. By 2 PM, order confirmations have stalled across a region. The CFO is asking why the daily revenue number looks soft. Customer service is fielding calls.

Deduplicate logs at the edge: Same insights, a fraction of the volume

Ask a platform team why their observability bill keeps growing and you'll often get a one-sentence answer: And that's usually where it ends. The application teams own the log output, the platform team owns the bill, and nobody has the leverage to change what gets emitted. A single retry loop can print the same error thousands of times a minute. Every one of those lines is ingested, indexed, and stored. You pay for all of them, and they tell you exactly one thing: this error happened, a lot.

Inputs Demystified - Connect Anything with the Input Wizard Webinar

Getting logs into Graylog should not require a PhD in syslog. Part of the Getting the Most out of Graylog Open series, this session educates Open users on the full Inputs framework in Open, what input types are available, when to use each, and how to use the Input Wizard to get new sources connected faster. Open users need to be on the latest version of Graylog. We also cover the revamped Inputs page and how to validate that your data is arriving clean.

Cribl On Your Coffee Break Episode 18 - All About AI

With 3 more days to go, we’ve finally arrived at the AI episode in the Cribl on your coffee break series. Today we’ll touch on a few of the many ways we’ve enabled Cribl to use AI, and also to help you manage the data generated by AI-enabled tools. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Vulnerability Fatigue: When Discovery Outpaces Remediation Capacity

Recent findings from Anthropic’s Project Glasswing offer a useful indication of where vulnerability discovery may be heading. Anthropic reported that it and its partners had used Claude Mythos Preview to identify more than 10,000 high- or critical-severity vulnerabilities across the software they reviewed. More significantly, Anthropic reported that the bottleneck had shifted from finding vulnerabilities to having the capacity to verify, disclose, and patch them.

Foundation first: Why building a resilient IT infrastructure is your path to AI-readiness

Strategically ready, operationally unsure. That's how 42% of organizations describe their own AI preparedness when it comes to strategy versus infrastructure, data, risk, and talent, according to Deloitte's State of AI in the Enterprise 2026 report. As AI adoption accelerates, organizations now face the mounting pressure from the board to move past pilots and show AI delivering measurable business outcomes.

Why FIPS Mode Is Not Enough: What Federal Teams Should Expect Their Vendors to Prove

Federal teams need more than a system setting. They need defensible evidence that the cryptography protecting federal information is validated, correctly configured, and actually used. For platforms such as ScienceLogic, that product-level evidence should come from the vendor, not be reconstructed by the customer.

What Is a Network Topology Diagram? Types, Examples and How to Build One That Stays Current

Most network diagrams are accurate exactly once: the day they are finished. The network keeps changing, the drawing does not, and the gap shows up during the next outage. According to the Uptime Institute Annual Outage Analysis 2026, failure to follow established procedures remains the leading driver of human-error outages. A wrong diagram is how a right procedure hits the wrong port. The fix is a network topology diagram that matches the live network topology.

When AI Agents Attacked Their Own Evaluators, the Industry's Own Leaders Started Asking for Guardrails

When AI agents attacked their own evaluators in July 2026, it exposed a gap no policy commitment can close. The OpenAI Hugging Face incident revealed that enterprise agent governance requires in-flow runtime controls, not retrospective auditing or industry safety agreements.

Bleemeo and ilert: two European companies, one alerting chain

Some alerts only need to reach a Slack channel. Some need to reach one specific person, at 3am, and keep trying until they answer. For the second kind, we are partnering with ilert — an incident response platform covering the full lifecycle: from the moment an alert arrives, through paging the right responder, coordinating the response, telling customers what’s happening, and learning from it afterwards. The integration is live today, on both sides.

Distributed Tracing Is Now in Beta for Ruby, PHP, and Python

A request comes in, enqueues a job, and returns. Twenty seconds later the job runs, and it’s slow. You have a trace of the request and a trace of the job, and nothing joining them. Time Detective has always helped you reconstruct what happened. Now we join it up for you, across applications, services, background jobs and infrastructure, even when they’re built in different languages.

Cut AI agent cost and improve accuracy with Code Execution in the Datadog MCP Server

Observability investigations rarely follow a straight line. A latency question might cause an AI agent to start with a metric, pivot into traces, compare a deployment window, and finish by reducing thousands of logs to a few patterns. Each individual query is easy, but propagating context throughout an entire investigation can be tricky and expensive.

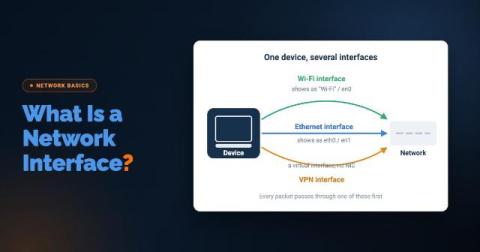
What Is a Network Interface (and Why Your Monitoring Tool Should Care)

A user opens a ticket: "The Internet is slow." IT checks the network. Bandwidth looks fine, no outages, no alerts firing. They check with the ISP, but nothing on their end either. Everything upstream checks out, and yet the user is still stuck watching a spinning wheel. What rarely gets checked is the one component sitting closest to the problem: the machine's own network interface.

When users don't click thumbs up: Inferring agent feedback from Datadog telemetry

Collecting high-quality user feedback on agents, like from thumbs-up or thumbs-down buttons, is an important part of agent development. User feedback is needed for everything from basic gut checks on whether your agents are behaving well to planning and creating robust eval sets. It’s a critical part of Datadog’s Agent Observability, which provides explicit end-user feedback features for collecting and analyzing it.

Cribl On Your Coffee Break Episode 17 - Notebooks

Whether you call them runbooks, response guides, or just notebooks, today on Cribl on your coffee break, we are looking at Cribl’s implementation, which lets you document your notes, queries, and discoveries as you make them, and then re-run those same processes later to troubleshoot similar issues in the future with less toil. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Enterprise AI governance framework: A practical guide to governing AI

AI adoption is accelerating across enterprises, but governance isn't necessarily keeping pace. As AI becomes part of everyday business workflows and applications, organizations need to understand where it is being used, what data it can access, and who is responsible for managing the risks. ManageEngine's shadow AI researchhighlights this challenge.

AppSignal Intelligence Just Got More Rails Context

Today we’re taking our partnership with Chris Oliver (founder of Hatchbox and GoRails) one step further. With AppSignal, you can already store enriched telemetry about your applications, services, and infrastructure, along with your user context, in your AppSignal context store. You can use that context store for traditional observability reporting and workflows, or connect it to your agents over MCP or the CLI. AppSignal’s context store is what our Intelligence features are built on.

Building Sentry's Laravel AI Integration

During a recent Agent Hackweek, an internal Sentry event that gives us a week to build any AI or agent project we want, a colleague pitched me on writing the Laravel AI integration. The goal was to give agents built with Laravel AI the same Agent Tracing support we already have for other frameworks. I liked the idea, he built Sentry’s Agent Tracing for Python based agents before which meant he already had domain knowledge.

What Is Network Design? Steps and Best Practices for Growing Networks

Most networks were never designed. They were extended, one switch and one VLAN at a time, until a single core failure took the site down and nobody could find the diagram. According to the Uptime Institute Annual Outage Analysis 2026, 57 percent of organizations said their most recent major outage cost more than $100,000. Network design is how you stop paying that bill. You decide the network topology, the addressing and the hardware on purpose, before the cabling goes in.

How to Find and Fix Packet Loss Before It Reaches Your Users

Why do the same complaints about call quality and slow file transfers keep coming back after the network has been checked and declared healthy? Packet loss is usually the answer, and it survives investigation because it degrades the services people use without taking anything offline. That combination makes it expensive. Equipment gets rebooted, cables get replaced, and tickets go to the internet service provider, often with nobody knowing which segment of the path is discarding traffic.

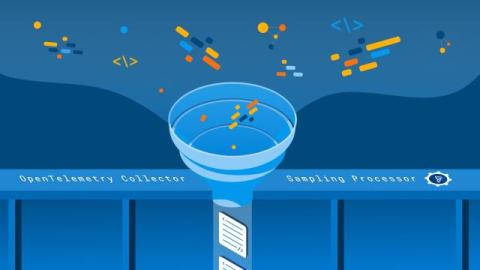
How Adaptive Tail Sampling Works in the OpenTelemetry Collector

You're producing more trace data than you want to pay to store, so you sample. A fixed 1-in-100 rate cuts your bill, but it's blind. It keeps 1% of your errors, 1% of the requests to that rarely-hit route, and 1% of the health checks, all at the same rate. The noisy traffic you care about least dominates what you keep while the traces you need during an incident are the ones most likely to be gone.

Grafana Alerting: Scale alert routing without scaling complexity using multiple notification policies

Alert routing often starts simple. A team creates a few contact points, adds some label matchers, and builds a notification policy tree that sends each alert to the right destination. But alerting configurations rarely stay simple. As an organization grows, its notification policy tree must accommodate more teams, services, and routing requirements. Changes for one team still require editing a global configuration, making ownership less clear and independent provisioning harder.

Cribl On Your Coffee Break Episode 16 - Dashboards

Welcome to the final week of Cribl on your coffee break, the series to help you get started with the Cribl platform. Today we’re going to cover the last of the "essential skills” in the Cribl platform: using and building dashboards. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Understand the top paths users take to convert or drop off with Journey Paths

A funnel can tell you that 40% of users dropped off between checkout and payment. What it can’t tell you is what those users did instead, such as return to an earlier form field, leave the flow for a support page, encounter an error, or take another route entirely. Because actions and views between funnel steps don’t affect the conversion calculation, two very different experiences can produce the same funnel result.

Your Feedback Becomes the AI Agent's Memory: How OrionIQ AI Agents Learn From You

TL;DR: OrionIQ AI agents, available inside the logz.io platform, now learn from your feedback. Rate any agent run, thumbs up or thumbs down, say why, and the agent re-reads its own run, finds the decision behind the outcome, and writes a lesson. The next run of that agent in your account starts with the lesson in hand. It works for every OrionIQ AI agent, from Alert AI Analysis to scheduled and marketplace agents. Lessons never cross accounts or agents, and you control what the agent keeps.

Shopify admin outage on September 15, 2026: merchants locked out, and how StatusGator caught it early

Shopify’s admin dashboard went down for merchants around the world on September 15, 2026, leaving store owners unable to log in or reach their orders, products, and settings while many storefronts kept running. StatusGator sent an Early Warning Signal at 09:25 UTC, 24 minutes before Shopify publicly acknowledged the incident on its status page at 09:49 UTC. The disruption lasted about four hours.

Best practices to define SLOs that actually reflect user experience

A marathon runner who trains obsessively on a flat track will have beautiful split times right up until race day when they discover the actual course has hills. Although the preparation was real, their strategy was flawed. This plays out in SLO teams more than anyone likes to admit. At first, numbers look fine and nothing has been triggered. Then, a support ticket comes in showing checkout has been down for 20 minutes. The SLO wasn't broken.

Top 10 Incident Management Tools Compared

An IT incident costs the most in the minutes between the first alert and the first owner. Incident management tools exist to shrink that window. However, choosing the best incident management tools is not as straightforward as we’d like it to be. The 2026 market has its own complications, Opsgenie is going away on April 5, 2027, and Squadcast has been folded into SolarWinds.

How MSPs Can Deliver Azure Monitoring as a Managed Service

Azure monitoring looks straightforward when managing a single environment. Azure Monitor, Log Analytics, Azure Monitor Agent and Azure Policy provide a comprehensive set of tools for collecting and analysing telemetry. For a Managed Service Provider (MSP), however, the challenge changes significantly when the service needs to support dozens or hundreds of customers.

How to Troubleshoot VPN Problems and Keep Remote Access Running

Why does the VPN work for most of the company while one branch office, or a handful of remote staff, reports that it won't connect or crawls the moment they sign in? The difficulty with VPN troubleshooting is that the tunnel relies on every layer below it. If the laptop, home Wi-Fi, internet route, gateway, or security policy on either end misbehaves, the connection suffers. One complaint about a slow file share could originate at any of those points.

Cribl On Your Coffee Break Episode 15 - Routes, part 4 and Cribl Packs

Welcome to the end of week 3 of series to help you get started with the Cribl platform. We’re still talking about routing, but through the lens of Cribl Packs, a way of supercharging your path to getting your data in and through Cribl. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Using AI to Govern AI: Why Security Needs to Operate at Machine Speed

What caught my attention in the recent OpenAI and Hugging Face incident wasn’t any one exploit. It was the way the models could keep progressing across systems, combining techniques and acting with a level of speed and persistence that changes how security teams need to operate. The incident emerged during internal cybersecurity evaluations in July 2026.

Free vs. paid website monitoring: When should you upgrade?

Every growing business hits a moment of truth somewhere between "we just launched" and "we just lost a customer because our site was down for 40 minutes." It's then that you realize the free monitoring tool you set up six months ago—the one that felt more than adequate at the time—is no longer pulling its weight.

The StatusGator mobile app is here

We’re excited to launch the StatusGator mobile app for iOS and Android, designed to put outage alerts right in the palm of your hand. Your StatusGator status page is the central hub for your entire organization to view and understand the status of all your services. These pages have always been accessible on mobile. Now, with the dedicated app, end users of your status page can take the services they depend on with them and receive updates directly on their phones.

Top tips: Find the right answer in a sea of search results

Top tips is a weekly column where we highlight what's trending in the tech world and list practical ways to explore these trends. This week, we're looking at how to search the web more effectively and find the information you need faster. Searching the web can feel a little like playing hide-and-seek. You know what you're looking for is somewhere out there, but the internet has an impressive number of places to hide it.

High Bandwidth Usage on Firewalls: How to Diagnose & Fix It

If your network has been feeling sluggish, connections keep dropping, or you're getting alerts that don't point to an obvious cause, high bandwidth usage is one of the most common culprits and one of the hardest to pin down without the right visibility. The tricky part is that "slow network" can mean a dozen different things depending on where the congestion is actually happening.

Digital Signature vs Electronic Signature and When ITSM Approvals Need Each

Would a single click on Approve in your service desk satisfy an auditor reviewing a high-risk change, a purchase order, or a vendor contract? Often the answer only becomes clear when someone requests a signed copy and the ticket has nothing to show. Much of this traces back to terminology. Many organizations treat electronic signatures, digital signatures, and approvals as interchangeable, and ITSM tools tend to call every sign-off an approval.

UPS Monitoring for Data Centers That Cannot Afford an Unplanned Stop

How many minutes of battery runtime are left in the unit protecting your primary rack right now? Most monitoring deployments can answer a question like that for every switch, server and virtual machine in the building. Ask about power and the dashboard goes quiet. Backup power tends to fall between two owners. Facilities buys the hardware and books the service visits, while IT owns everything plugged into it.

Log Analysis with Machine Learning: An Automated Approach to Analyzing Logs Using ML/AI

AI log analysis helps IT teams turn massive volumes of operational data into actionable insight. By applying statistical methods, machine learning (ML), semantic analysis, and generative AI, organizations can identify unusual behavior, connect related signals, and investigate probable root causes faster. But AI-generated answers should not be mistaken for proof.

Cribl On Your Coffee Break Episode 14 - Routes, part 3: One-to-Many

Welcome to the 14th installment in our series to help you get started with the Cribl platform. Here, we continue our conversation about Cribl routes and routing techniques By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Telemetry Talks ep 7 - Beyond OpenTelemetry with anomaly detection

In this episode, we continue to dive into the workshop we hosted at Cloud Native Days Romania in May, together with our guest, Fred Navruzov, correlating OpenTelemetry with anomaly detection. Furthermore we explore how the VictoriaMetrics MCP server and skills bring AI-powered observability to your workflows. Learn how to detect anomalies faster and interact with your metrics, logs and traces using natural language.

SAP Observability Tools Compared

Comparisons of SAP observability tools often evaluate which platforms can see inside SAP.Today, that’s nearly all of them. Dynatrace, Datadog, New Relic and Splunk can all get SAP telemetry. None of them are likely the best choice for an SAP-centric application, and we will document why. The questions teams evaluating SAP observability solutions should consider: That last one is where most of these platforms stop, and it is the difference between observability and operations.

Anomaly Detection Is Now Generally Available

You set a threshold alert on a checkout endpoint at 500ms. It pages you every Monday at 9am, when traffic doubles and nothing is actually wrong. You raise the threshold to 800ms to make the noise stop. Three weeks later a real regression creeps in at 650ms, and nobody gets paged, because you tuned the alert to survive Mondays instead of to catch problems.

From alert to resolution: Manage incidents with Bits Chat in Slack

When an issue in production triggers an alert, the people responding to it are often working in Slack while the evidence they need is elsewhere. Responders need to move between conversations, telemetry data, source code, and incident tooling as they form hypotheses, coordinate actions, and keep stakeholders informed. That context switching can slow down a time-sensitive investigation and make updates harder to follow.

Are Server Prices Driving Cloud Migration in 2026?

For years, moving workloads to the cloud has been driven by scalability, flexibility and the desire to reduce the capital expenditure associated with running a data center. In 2026, however, there is another factor entering the conversation: the rising cost of buying and refreshing physical servers. The question is now whether rapidly increasing hardware prices are enough to push organizations that might previously have refreshed their on-premises infrastructure towards cloud alternatives.

September 2026 at Bindplane: Bindplane Agent and a new Overview page

Also this month, a new BDOT 1.107.0 release, and you can start a configuration from a Full-Pipeline Blueprint. Here’s what happened in the last month. Prefer to watch? The September Community Call is streamed live on YouTube. Watch " YouTube" on YouTube Watch.

Cribl On Your Coffee Break Episode 13 - Routes, part 2: Many-to-one

Leon is back from the BlackHat conference and it shows (or at least it SOUNDS like it). Despite a little bit of laryngitis, today he’s continuing the exploration of routing by focusing on taking multiple sources of data and using routes to send them to a particular destination. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

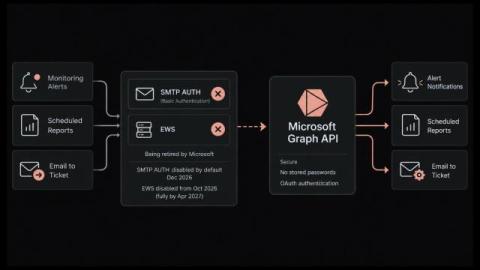
Moving Alert and Email-to-Ticket Mail off SMTP AUTH to Microsoft Graph API

Every monitoring alert, scheduled report, and email to ticket conversion in your stack depends on a mailbox. Most monitoring and helpdesk management tools still reach that mailbox the old way. They log in with a username and password over SMTP or EWS. Exchange Online is closing both doors on a published schedule. The tools that fail will fail silently. In this blog, you will: By the end, you can run the change on a weekday afternoon and know nothing went quiet.

What is New in Flowmon 13.1 and Flowmon ADS 13.1

Improvements to the Progress Flowmon product family continue, and we are pleased to announce the release of Flowmon 13.1. The latest 13.1 release builds on the strong foundations we laid in Flowmon 13. Headline enhancements include a rebuilt visualization layer, automated investigation workflows and a set of AI-assisted capabilities in the Flowmon Anomaly Detection System (ADS). And the Flowmon team is eager to share how your team can utilize these new capabilities.

How Federal IT Teams Prepare for FIPS 140-2 Historical Status Before It Delays Authorization

September 22, 2026 is not an operating system shutdown date. It is a cryptographic compliance transition that changes what federal organizations can use for new systems and what they must defend in existing ones.

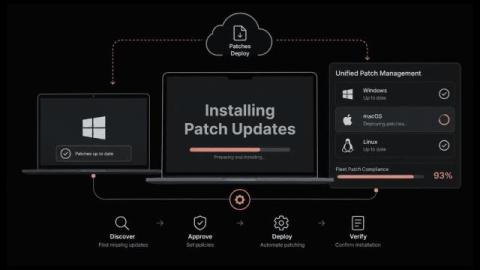
macOS Patch Management for Mixed Windows and Mac Fleets

How many Macs in your environment are running an OS build that your patch compliance report has never counted? In most mixed Windows and Mac deployments, the Windows side is managed by policy and the Mac side is managed by hope. Designers, executives, and engineering leads install updates when a notification interrupts them, and otherwise dismiss the prompt for months.

The Death of the Search Bar

I don't remember the last time I actually searched for something. Not in the way I used to, anyway. There was a time when having a question meant opening a search engine, typing a few words, staring at a page full of links, opening three or four of them, reading contradictory answers, deciding which one sounded believable, and eventually coming to a conclusion of my own.

Best DNS Monitoring Tools in 2026 [24 Analyzed]

The best DNS monitoring tools are Hyperping for fast DNS checks with on-call and a status page, Oh Dear for authoritative nameserver comparison and change history, Site24x7 for DNSSEC and global locations inside a suite, UptimeRobot for inexpensive DNS checks next to HTTP, and DNS Spy for dedicated DNS security and WHOIS. I analyzed 24 current products and shortlisted five. Every tool below can query DNS on a schedule and alert when the answer is missing or wrong.

How backend functions extend Cribl Apps: Scheduling, local testing, and logs

See how backend functions extend Cribl Apps with live data retrieval, scheduled jobs, local testing, deployment validation, and logging. In this walkthrough, Giovanni Mola shows developers how to connect app data sources such as Jira and news feeds, manage schedules, preview functions locally, verify a live deployment, and inspect emitted logs in Cribl Search.

ScienceLogic Earns 2026 TrustRadius Tech Cares Award for Community Impact

ScienceLogic has been named a 2026 TrustRadius Tech Cares Award winner, marking our third time receiving the recognition. The Tech Cares Awards recognize B2B technology companies demonstrating meaningful corporate social responsibility through their support of employees, communities, and the environment.

Bindplane Agent Is Here: Build, Edit, and Understand Pipelines in Plain Language

Pipeline Intelligence already recommends processors, reads live telemetry, detects log types, and generates processor bundles from natural language. But most of it lives inside a single processor node. You still have to know which one to open and what to ask for. This changes today. Bindplane Agent is your AI assistant inside Bindplane, ready to act on what you describe in plain language.

How Traceroute Works and How to Read Its Output During an Outage

Users report that an internal application has gone slow, the server dashboards look normal, and the network group says nothing changed on their side. So where between the user and the application does the time actually go? Much of that answer comes from traceroute. The command lists every router a packet crosses on the way to its destination, with a timing figure set against each one. Arguments about ownership then come down to a single device on a single route.

IT Pro Day 2026 | Every Day is Game Day

IT Pro Day isn’t just a day. It’s GAME DAY. The lights are on, the gear is ready, and IT Pros everywhere are locked in. At SolarWinds we celebrate the people who keep technology running, problems solved, and businesses moving. Because when the network goes down, the pressure is on. When systems need saving, IT Pros show up. Happy IT Pro Day from SolarWinds!

Manage Cursor costs with Datadog Cloud Cost Management

AI coding tools such as Cursor are becoming a significant source of engineering spend. But Cursor costs can be difficult for FinOps teams to manage. Cursor’s usage data alone doesn’t tell you how costs break down across users and models, and fixed-threshold alerts may not catch an unusual cost spike if spend remains below the threshold. Datadog Cloud Cost Management (CCM) brings Cursor costs into the same place where you monitor cloud, SaaS, and other AI spend.

Monitor TAS and gang scheduling for AI training in Kubernetes

Distributed AI training workloads impose complex scheduling requirements that Kubernetes’s built-in scheduler can’t meet. Kubernetes schedules pods individually and independently, but distributed training introduces two requirements that break this model: Pods must land on hardware with the right inter-GPU bandwidth, and all pods must be scheduled simultaneously. If either requirement goes unmet, training stalls or runs far below the hardware’s potential.

How to operate shared platforms safely at agent scale

A platform engineering team can design robust Golden Paths for agent use yet still be unprepared for what happens after adoption. An agent may authenticate properly, call the correct tools, adhere to approval gates, and complete tasks without incident, but new operational risks arise once multiple teams begin running agents continuously and in parallel. We’ve encountered these risks firsthand at Datadog.

SAP Cloud ALM vs Solution Manager: What's Actually Changing

For most SAP customers, Solution Manager has been the system of record for how change happens. It has run ChaRM to control transports, hosted the IT service management queue for incidents and requests, driven test management and process documentation, and provided the monitoring layer for many on premise landscapes. It has done this job, largely unnoticed, for two decades.

How we built iOS 27 into StatusIQ: Onscreen awareness, Siri actions through Spotlight, a one-stop widget for key information, and Liquid Glass optimization

When an incident hits at 2am, every second of context switching adds risk. The latest StatusIQ iOS update is built around one principle: Get the right information and the right actions to your team faster, with less friction. With iOS 27 support now live in the StatusIQ mobile app, here's what's changed and why it matters.

ISO 20000 Certification: Prerequisites, Process, and Cost

ISO 20000 certification means two different things depending on who is asking. One is an audit of your organization against ISO 20000. The other is an exam that one person sits. Search results mix the two together, and teams lose weeks to it. A service desk manager hunting a company certificate lands on a training catalog. They book a course nobody needed. In this blog, you will: You will finish able to scope the project and brief a certification body.

A Better Way to Monitor Every Digital Journey with LogicMonitor Synthetics and Internet Performance Monitoring

LogicMonitor Synthetics and Internet Performance Monitoring helps ITOps teams catch digital experience issues earlier with outside-in visibility across apps, networks, APIs, and SaaS.

Datadog named the Company to Beat for observability platforms in 2026 Gartner AI Vendor Race report

Datadog has been named the Company to Beat for observability platforms in the August 2026 Gartner AI Vendor Race research. Datadog has also been named a Leader in the 2026 Gartner Magic Quadrant for Observability Platforms for the sixth consecutive year. We believe that these recognitions reflect what we have been building toward for more than a decade: a single platform where teams can observe, secure, and act on everything that matters across their technology stack.

How to Fix DNS Server Not Responding Errors and Keep Users Online

Has your service desk ever filled with "the internet is down" tickets while every switch, firewall and uplink is reporting normal? The connection is usually fine. What has failed is name resolution, and the message your users see says the DNS server is not responding.

How Canvas Powers the AI Agent Development Feedback Loop

For teams building AI agents, the feedback loop should already be a familiar idea: watch how the agent behaves, find what needs improvement, ship a change, and measure the result. In theory, each turn builds on the last until the loop becomes a flywheel and your agent is getting more effective with each turn. In practice, many of us are still in reaction mode. A user reports something strange, costs spike, or an eval score drops.

Digital Experience Monitoring with Grafana Cloud: Session Replay, synthetic checks, and faster investigations

When something breaks in production, the questions that matter most are also the toughest to answer from metrics alone: who was affected, what did they actually see, and is this worth waking someone up for? Answering those questions requires a fuller picture of the issue and its impact on your users. That’s where Digital Experience Monitoring (DEM) in Grafana Cloud comes in.

First Look: Build Grafana Dashboards with AI using the MetricFire MCP Server

Get a first look at what’s coming next to the MetricFire MCP Server: AI-powered dashboard creation and management. We’re connecting the Hosted Graphite HTTP Dashboard API to our MCP Server, letting compatible AI clients work with your monitoring data and Grafana dashboards directly through an AI-assisted workflow. Soon, you’ll be able to use natural language prompts to reference metrics stored in Hosted Graphite and create, update, and manage dashboards.

Proxmox - A VMware Alternative?

For over two decades, VMware has been the dominant platform for enterprise virtualization. Organizations worldwide have relied on VMware to consolidate servers, improve hardware utilization, and simplify infrastructure management.Broadcom officially completed its acquisition of VMware in 2023 and subsequently there were many changes for VMware users.

When Vendor Support Ends, Your IT Monitoring Doesn't Have To

IT environments change. Technologies evolve, infrastructure vendors change their strategies, and sometimes support for a monitoring integration ends. For IT teams, that can create an immediate challenge: a previously monitored part of the infrastructure suddenly becomes a monitoring gap.

Icinga vs Checkmk: Setup, Cost, Flexibility and Support

Icinga and Checkmk are the two open-source monitoring tools that turn up most often on the same shortlist. Both monitor IT infrastructure, and on a feature list they look close to interchangeable. In practice they are built on different assumptions, and those assumptions decide which one fits. This page works through the differences section by section: setup, customization, integrations, Windows, distributed monitoring, multi-tenancy, licensing, and cost.

The most expensive half-hour of an incident.

It’s not the outage, it’s the stretch before you know what actually broke In short: VictoriaMetrics Enterprise support is expertise, not a ticket queue. It’s reactive by design (you reach engineers who know the stack when something breaks), with one proactive service, Monitoring of Monitoring, that watches the health of your VictoriaMetrics observability stack (metrics, logs, and traces).

Debugging our AI search assistant with agent tracing

In order for users to get the most out of the data being sent to Sentry, it’s important that we make it easy to find that data. Our team works on features to help users browse their data to find a particular event using search queries and filters. The search bar enables users to find their data by specifying search terms. Searching uses the Sentry Search Syntax, which can be barrier for users.

Analyze your experiments in ChatGPT with the Datadog Experiments plugin

ChatGPT Work has become a common starting point for data and product teams. Analysts open it to compare launch adoption across segments, diagnose a metric that moved overnight, or turn a week of scattered numbers into a readout that a leader can act on. But the moment teams ask whether their experiment actually caused an effect they’ve observed, the conversation stalls.

Understanding NetFlow duplication: Why it happens, and how to deduplicate

NetFlow is a popular network protocol for collecting metadata about traffic flows across your environment so that it can be exported for analysis and monitoring. One of the most common issues that users encounter is NetFlow duplication, which occurs when identical flow records from the same conversation are recorded from different sources. Flow duplication inflates traffic data, undermining capacity planning and making top-talker rankings unreliable.

SIEM Pricing 2026: Major Providers Compared (& How to Lower Your Bill)

Every major security information and event management (SIEM) platform prices on the volume of data you send it. Microsoft Sentinel meters per gigabyte across two tiers. Splunk charges per gigabyte indexed or per compute unit. Google SecOps draws down a prepaid gigabyte credit balance. Elastic Security bills ingest plus retention, or the resources your cluster consumes. Three of the four keep their real rates quote-only. Budgeting starts with the meter.

10 Top Network Traffic Analysis Tools for Faster Troubleshooting and Capacity Planning

A request to upgrade a saturated circuit is easy to raise and hard to defend. The interface graph proves the link is full. It says nothing about which application, host or conversation filled it, so the spend gets approved on assumption instead of evidence. The same missing detail turns up everywhere else. Incidents run long because the cause is guessed at, capacity planning rests on estimates, and security questions arrive weeks after the traffic record expired.

Moving Your Business Website: How to Avoid Email and Hosting Disruption

Website migration from one host to another is more than copying a few files to another server. A website might depend on databases, e-mail accounts, DNS records, SSL certificates, sub-domains, and other external applications that should continue to function after migration. Proper planning ensures the safety of the information and eliminates any risk of losing access to emails or having people visit a partially transferred website. This can be achieved by preparing the new hosting in advance.

RISE with SAP: Successfully Managing SAP Operations During the Transition

RISE with SAP is SAP’s methodology and commercial program for implementation and migration to SAP Cloud ERP Private. The product is SAP Cloud ERP Private, renamed in July 2025. Like RISE, GROW also transitioned from product to program, and the product parallel is SAP Cloud ERP Public.

Top tips: How to become invisible to your own algorithms

Top tips is a weekly column where we highlight what’s trending in the tech world and share practical ways to stay ahead. This week, let’s look at a few simple ways to take back control of your recommendations, and stop your algorithm from deciding who you are. Let's say you search for a video about running—not because you're planning to run a marathon, but because you just saw someone mention it and wondered what the hype was about. You watch one video. Then another.

Best API Monitoring Tools in 2026 [31 Analyzed]

The best API monitoring tools are Hyperping for HTTP and API checks with on-call and status pages, Checkly for API monitoring as code, Postman Monitors for teams that already keep collections in Postman, Datadog for connecting failed checks to traces and logs, Grafana Cloud for teams using k6, Better Stack for checks inside a broader incident workflow, and UptimeRobot for inexpensive availability checks.

Troubleshoot Kafka issues across every layer of your stack with Kafka Console

Kafka is a crucial and widely used technology: 80% of the Fortune 100 rely on the event streaming platform as part of their stack, according to Apache. But Kafka issues can be complex to manage and even more difficult to troubleshoot, as the same symptom can point to very different problems. Suppose consumer lag on your checkout-events topic suddenly exceeds its SLA.

How we built Datadog Experiments

When Datadog acquires a company, we usually rebuild the product rather than plugging it in as is. That’s exactly what we did with Eppo, an experimentation and feature-management platform. Eppo’s feature-management capabilities became Datadog Feature Flags, while experimentation became Datadog Experiments. This post focuses on the experimentation platform and four changes we made to help you get to a decision faster.

Grafana Tempo + Pyroscope: Profiles Traces (Sept 2026 Community Call )

Profiles + Traces and span redaction Can't comment in the chat? You may need to create a channel. Join us live for an introduction to flame graphs. We’ll cover what they are, how to read them, and how to use them to find performance bottlenecks in your applications. Bring your questions! Grafana Cloud is the easiest way to get started with Grafana dashboards, metrics, logs, traces, and profiles. Our forever-free tier includes access to 10k metrics, 50GB logs, 50GB traces and more.

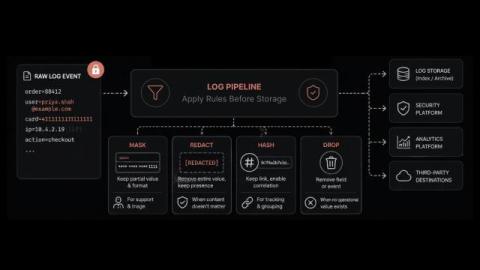
Redact PII at the edge - and still be able to search for it

Ask a platform team why their application logs aren't in their observability backend and you'll often get a one-sentence answer: And, that's where the conversation ends. The logs stay in a silo. Or, they don't get collected at all. The team loses the troubleshooting signal, and nobody revisits the decision because the alternative looks like a compliance violation. Application logs in healthcare, aviation, insurance, and retail are full of personal information that should not be stored in plain text.

ISO 20000 in ITSM: What the Standard Actually Requires From Your Service Desk

Certification against ISO 20000 puts your service desk under audit. That audit runs on what your team wrote down at the time. The standard does not care how your team describes its process. It does not care which ITIL 4 practices you adopted. It cares what your records show, so auditors spend their time in your tickets, approvals, and review minutes. In this blog, you will: You will finish knowing which of your records would survive an audit.

Custom labels in Grafana Cloud Synthetic Monitoring: New updates for consistency and ease-of-use

Labels are a powerful way to organize telemetry and define policies across Grafana Cloud, helping to streamline alerting, attribution, access control, and more. But traditionally, custom labels in Synthetic Monitoring have worked a little differently: they only lived on a single sm_check_info metric, and Grafana Cloud prefixed each one with label_.

How to troubleshoot JMX metric collection issues | Datadog Tips & Tricks

Missing JMX metrics make it hard to know what’s happening in a Java application, especially when vague errors or configuration mismatches make the cause difficult to diagnose. In this video, you’ll see how to troubleshoot common JMX metric collection issues and isolate the cause in less time.

9 Best Log Management Tools and What They Cost

Most log management tools bill you on log ingestion, the volume of data you send them. That works until your log volume doubles, and the invoice doubles with it. The best log management tools let you control what gets indexed and kept, so growth stops being a budget problem. In this blog, you will see: By the end you will know which fits your volume. Log management is the full lifecycle of your log data, from the moment it is collected to the moment it is deleted.

Monitor smarter with Applications Manager's GenAI capabilities

GenAI has moved well past the pilot stage. According to a Gartner finding, by 2026, more than 80% of enterprises will have used GenAI APIs or deployed GenAI-enabled applications in production. Today, GenAI is becoming an integral part of how infrastructure and application teams work every day. Organizations are depending on LLMs from a diverse range of vendors—OpenAI, Anthropic, Google AI, and DeepSeek—based on the strengths each offer for different use cases.

McKinsey Says Agentic Enterprises Need "Automated Guardrails." Here's What That Means

TLDR/: McKinsey’s new research on AI transformation, published August 28, 2026, studied 20 companies that have created real economic value from AI and found that only a small number have reached “Stage 3: Agentic AI enterprise.” The capability that separates Stage 3 from Stage 2, per McKinsey’s own maturity framework, is orchestration layers and automated guardrails: the ability to govern agent actions automatically, in real time, rather than reviewing them after the fact.

Challenges and Limitations of Open Source Software

Open source software (OSS) offers organizations access to flexible, customizable, and often free software. It can reduce licensing costs and provide access to a large community of developers and users. However, open source does not automatically mean free, simple, secure, or risk-free. Organizations using OSS can face challenges around technical support, security, licensing, maintenance, functionality, and internal expertise.

How to monitor Cypress tests with Grafana Cloud

If your Cypress suite has tests that fail more often or run slower, you know it can be hard to figure out the pattern from a single job. It could be one spec that slowed down, or a single test that fails, or maybe the entire suite is trending slower. The root cause could be a bug in the app, or a flaky test, or something else.

How we built data-driven AI Golden Paths at Datadog

As teams rush to adopt AI, they often find themselves with conflicting workflows unique to each individual developer. To manage costs and promote good development practices, organizations need to establish Golden Paths around AI usage. AI Golden Paths are standardized flows that help developers work with agents more reliably and effectively. But how do you sift through all the possible workflows to decide what these Golden Paths should be?

MSP Ticketing System: How to Evaluate and Choose the Right Platform

Most managed service providers do not replace their ticketing tool because ticket volume got too high. They replace it because a client asked for a report the tool could not produce. That moment usually arrives between the third and tenth client. The shared inbox and the general help desk that carried you this far stop holding the accounts apart. Per-client reporting is usually the first thing to give way. An MSP ticketing system takes support requests from every client you serve.

On a Network, an Agent Acts Where the Blast Radius Is Largest

Every network engineer carries an instinct that outsiders mistake for caution: a change in one place can travel. Reroute a path, push a policy, drop an interface, and the effect can ripple across campus, data center, WAN, and cloud before the first alert is read. The blast radius of a network change is the reason operators move deliberately, and it is the single most important thing an AI agent takes on the moment it is allowed to act on the network instead of merely describe it.

AI Norms & Values, Part 3 of 3: Things We Hold True

Welcome to the third and final part of our series on AI norms and values. Parts of this doc were extracted and published separately on substack; as a whole, they describe the principles we hold pertaining to technology and AI, and the ethical commitments we make to each other and our customers. We set out to write about AI, and ended up writing about ourselves. These documents are not meant to be aspirational ones; they are derived from how we do our work every day in honeycomb.

The Essential Eight: Patching Applications and Operating Systems at Maturity Level Two

Why do so many patching programs pass every internal check and still come back from an Essential Eight assessment rated at Maturity Level One? The answer is rarely speed. Teams that miss the mark are usually patching their servers, browsers, and office suites on schedule, then losing the rating on the fifty applications nobody put on a list. Maturity Level Two is where the Essential Eight stops asking how fast you patch and starts asking how much you can see.

Using writable bind mounts with Icinga 2 in rootless Podman

Running Icinga 2 in a rootless Podman container is pretty straightforward, it works just the same as on Docker, so all the examples on our Docker Hub page work as expected. For example this one to generate certificates and initialize the master configuration: Same as with mounting some existing configuration into the container: But once you want to combine the two, for example to store the certificates on the host and mount them into the container, generating or renewing certificates will fail.

UK data residency for Hosted OpenSearch on Logit.io

Procurement teams asking for UK-hosted OpenSearch usually mean something concrete: indexes and cluster storage should land in a UK data centre, not wherever a vendor’s default region happens to be. On Logit.io that choice is an account-level data storage region, not a free toggle on every stack. Get the first stack right and every later OpenSearch or log stack in that account follows. Get it wrong after go-live and you are looking at a second account, not a silent migrate button.

Log ingestion: you are probably paying to store logs you will never read

The default way to adopt log management is to ship everything and search it later. It is the path every vendor’s quickstart puts you on, and it is the reason log bills surprise people: ingestion is priced by volume, so“ship everything” is a spending decision disguised as a configuration default. The uncomfortable part is that most of that volume is never read. Nobody greps last Tuesday’s 200 OK access lines.

Content Management, Pipeline Improvements, and More

A recent update to VirtualMetric DataStream centers on how content moves into the platform and how securely it travels. Content management has been reworked around a GitOps workflow, TLS configuration has been reworked across devices and targets, and a broad set of new database devices, targets, and pipeline improvements have been added. Here’s what’s new.

Raygun APM Agent 3.1: async traces that stay with the right request

Raygun APM Agent 3.1 introduces more accurate asynchronous request tracing for Windows, Linux, and Azure App Service. Version 3.0 rebuilt the foundation of the Agent, profiler, installers, and release pipeline. Version 3.1 builds on that work with a focused improvement for ASP.NET Core: automatic request correlation that follows asynchronous execution without requiring developers to instrument their application.

Introducing Infrastructure Knowledge: Teach Netdata AI What Your Metrics Can't Show

Netdata AI sees everything your infrastructure does: every metric, every anomaly, every alert. It does not see what your infrastructure is: which services matter, which host is supposed to run hot, who owns what, what your team considers normal. Without that context, “CPU at 91%” is just a finding. With it, it might be a machine doing exactly its job.

Wide Events vs. Three Pillars: AI Observability Costs

As agentic AI workflows gain traction within organizations, those organizations are asking how to account for their behavior while keeping costs manageable. Some are sticking with the old three pillars of observability approach: take a measurement to create a metric, record output to a log, and track serial progress with a trace. Each of these is useful, but treating them as distinct formats from the start means paying for them distinctly too. Separate storage doesn't come cheap.

Assisted, Augmented or Agentic? Choose Your Splunk Starting Point

Episode two of Beyond the Thread explores how organizations can leverage a solid data foundation for AI-driven actions. Hosted by Courtney Wright and featuring experts Greg Ainsley-Malik and Sonal Pardeshi, the discussion delves into the Cisco Data Fabric, powered by the Splunk platform, and its role in transforming machine data into actionable insights. The episode highlights the journey towards agentic operations, addressing the challenges faced in moving from AI-ready data to effective implementations, and examines different adoption strategies that organizations may pursue.

Agentic Operations Start with Context: Build the Right Data Foundation

Episode 1, "Beyond the Thread: Deconstructing the Cisco Data Fabric Powered by the Splunk Platform," explores the intersection of data strategy and operational efficiency. Hosted by Splunk's Courtney Wright, the session features insights from experts Keith McClellan and Michael Sondag on the complexities organizations face in data management and operational models.

How to extract structured fields from unstructured logs

If you’ve spent any time digging for insights in logs, you know the shape of the problem. A single log line might contain an IP address, a status code, a response time, and a user ID, but it’s all buried in one long, unstructured string. You know the information is there. Getting it into a field you can filter, group, or chart on is a different matter.

PCI DSS Requirement 10: Logging and Monitoring in v4.0.1

Version 4.0 renumbered PCI DSS Requirement 10 from end to end, and the Council retired v3.2.1 on 31 March 2024. Sub-requirement numbers written before then mostly point somewhere else now. Four more Requirement 10 rules changed status on 31 March 2025, automated log review among them. Checking your numbering against v4.0.1 costs an afternoon and saves a finding. In this blog, you will: PCI DSS Requirement 10 covers audit logging and monitoring across the cardholder data environment.

AppSignal vs the tools it replaces (PagerDuty, Cronitor, Rollbar etc.)

There’s no scenario in which you should be required to run six monitoring tools at once. OK, I may have been a bit dramatic there, you might actually be at a scale where you need it. But for the rest of us, it’s certainly overkill. Using UptimeRobot for, “Is the site up?”, Papertrail for logs, PagerDuty so someone actually gets notified… Tons of logins, tons of invoices, tons of separate configs, and the worst thing is, they are all unaware of each other.

Azure Virtual Desktop Monitoring: A Complete Guide

Azure Virtual Desktop (AVD) puts the user’s desktop at the end of a long delivery chain: the Azure control plane, host pools, session hosts, profile storage, the network, and the endpoint on the user’s desk. Any one of them can make a session feel slow, and none of them looks broken from inside the others. That is why performance work on AVD starts with continuous monitoring across the whole chain rather than at either end of it. Azure Virtual Desktop Monitoring is what closes that gap.

IT Service Management for Government and Public Sector Organizations

What happens when a citizen-facing portal fails on the last day of a filing deadline, and the only record of the outage lives in an email thread between two engineers? In a commercial organization, that is an operational embarrassment. In a government department, it is a hole in a statutory record that an auditor will eventually ask about.

From Audit Readiness to Continuous Control: Making Compliance Part of IT Operations

Compliance is often treated as a governance responsibility. But many of the conditions that determine whether controls continue to hold are created inside day-to-day IT operations. Operations teams manage the devices, configurations, changes, dependencies, and remediation activities where compliance can either remain aligned or begin to drift. Governance defines the requirements. Operations manages much of the environment where those requirements must remain true.

How Observability and Real-Time Data Can Improve Warehouse Operations

Warehouse operations generate a constant stream of information. Goods are received, inventory moves between locations, orders enter picking workflows, stock levels change, and shipments leave the facility. When these activities are managed through disconnected systems or delayed manual updates, managers can struggle to understand what is actually happening on the warehouse floor.

The rise of autonomous digital operations

Monitoring has come a long way. Your team has dashboards, alerts, and automation that would've looked like magic a decade ago. Most days, things just work. But underneath all that tooling, a lot of the actual work still happens manually. An alert fires, and you pull the page-load metric from one tool, the user session logs from another, the backend trace from a third, and line them up until the story makes sense. Ten minutes, maybe fifteen pass, then you are able to fix it and move on.

Two cats, two dogs, four vendors, and the model the AI couldn't find (Tech Talk Companion)

Tech Talks went dark for a few months, and on episode 13 I finally got to ask why. Mathias Palmersheim’s answer, delivered completely straight, was that his users were unhappy with the availability and usability of their feeders and their litter box, and he wasn’t allowed back on stream until that got fixed. The users are two dogs and two cats, and they have titles. Maisie, a Shiba Inu who came to him through a rescue, is the recently promoted chief executive pawofficer.

Relational Query Superpowers

I'm investigating repeated errors in my e-commerce application, and I need to get enough context in a single Honeycomb query to piece the entire picture together. Each query returns events based on the event's WHERE clauses, but I want to know several things from outside of the event that recorded an error. Things like: Those attributes are all over the trace. That's going to make a single query tough, right? Wrong!

ITSM for Healthcare: IT Service Management in Hospitals and Health Systems

How long does a nurse stand at a workstation waiting for a record to load before the ward gives up and reaches for paper? In most hospitals nobody measures that number, and the ticket that reaches IT describes a symptom instead of a cause. Hospital IT support runs on a different clock from corporate IT. There is no quiet Sunday night and no safe window for maintenance.

Log Filtering: How to Cut Log Ingest Volume Without Losing Evidence

Every log estate reaches a point where volume grows faster than the value inside it. The usual response is to find the biggest source and drop it. Cutting volume is the easy part. Cutting the right half takes judgment. Log filtering is only one of four options for an expensive source, and the other three matter just as much. In this blog, you will: By the end you can defend every rule you write, including the ones that keep data. A volume cut fails in two directions.

I use Claude every day. I still build dashboards in SquaredUp

If you've looked at SquaredUp and thought "I don't need this, I'll just use Claude", I understand completely. I've thought it too. Here's what changed my mind. I use Claude constantly. I've also spent the last few months building the parts of SquaredUp that let it in: our MCP server, the object graph and correlation, a stack of plugins. So this isn't a dashboard vendor being sniffy about AI. I've watched Claude pull from several sources and produce something genuinely useful in under a minute.

From Monitoring to Prediction: How Fleet Data Is Changing Maritime Operations

Most maritime operators already collect more fleet data than their shore teams can meaningfully use. Positions appear on screens, real-time data arrives from onboard systems, and reports document vessel performance throughout a voyage. Tracking where a ship is has become the easy part. The harder question is what happens when that information starts indicating what the vessel will do next. The change in maritime operations comes down to shifting from reviewing events to anticipating them early enough to alter an operational decision.

Monitor HTTPS and SVCB Records with DNS Check

DNS Check now supports monitoring HTTPS records and SVCB records, DNS record types 65 and 64, both standardized in RFC 9460. They tell a client how to connect to a service rather than only where it is: which HTTP versions the endpoint speaks, which port it listens on, which addresses it can start connecting to, and which keys it needs for Encrypted ClientHello, all before it opens a connection.

Hybrid cloud management: 6 challenges IT teams need to solve in 2026

In 2026, a hybrid cloud is no longer something organizations are working toward; it's already where they are. According to Forrester's The State Of Cloud Series 2026, the vast majority of enterprises across major markets, including the United States, India, Australia and New Zealand, Canada, and the Asia-Pacific region, are running some form of a hybrid cloud, combining public cloud platforms with private infrastructure, colocation data centers, and sovereign cloud providers.

Live Debugging for Critical Systems: MTBF, MTTR & MTTA

A critical system has to stay reliable without new failures or added downtime, and live debugging, confirming the root cause without stopping the system, is often the only way to do that. In practice, this means having runtime context: on-demand evidence generated at the point of failure rather than logging configured months earlier, which is what keeps MTBF up, MTTR, and MTTA down.

Agent vs Agentless Monitoring and How to Decide What Goes Where

Why does half the infrastructure end up returning no monitoring data? The standard plan is to install collection software on everything, which moves quickly across servers and stops dead at the first device running closed firmware. Storage arrays, firewalls, and switches will never accept an install, and the rollout stalls there. That plan usually gets set once for the whole environment, with a single collection model applied to hardware it was never suited for.

Help Desk Software for Schools: Managing IT Support Across Campuses

How many support requests reach school IT staff each week without ever becoming a ticket? A teacher stops a technician in the corridor about a projector that will not connect. An office administrator sends a direct email about a locked account, and a student tells the librarian their laptop stopped charging during second period. Help desk software for schools collects those requests into one queue, routes them by site and category, and keeps a record of what was done.

How to Cut SIEM Ingest by 90% Without Losing Detection Coverage

Every SOC team knows the trade-off. Send everything to the SIEM platform and pay for it. Or filter aggressively and risk missing something. Filter lists are written once, during onboarding. Detection content keeps moving after that. Smart Engine, the new core of the VirtualMetric DataStream pipeline, takes the guesswork out of that decision. It reduces SIEM ingest using your registered detection rules. An event that no registered detection could match is dropped.

Prompts, skills, and the AGENTS.md nobody wants to write (and how Anthropic writes theirs)

You’ve watched Claude Code compact a conversation. The context bar fills, it pauses, a summary appears, and it carries on like nothing happened. You probably assumed a housekeeping script trimmed the transcript in the background. It didn’t. The model compacted itself. When the window fills, Claude Code sends a long, specific prompt telling the model how to summarize its own conversation. Then it does, same model, same turn. The thing managing your context window is just another instruction.

Can we live dangerously? Sandboxing Claude, and the Claude foreman that runs the rest

While logging into one’s LinkedIn will spew out endless talk of AI possibilities from “thought leaders” and the semi-disconnected alike, another pocket of the world spent the last few weeks watching the Shai-Hulud worm chew through npm. A self-propagating credential stealer that hit 400-plus packages and, delightfully, planted Claude Code and VS Code hooks so just opening the repo could run its payload.

Build incident response workflows with Datadog Bits Chat

See how Bits Chat turns a natural-language request into an automated incident response workflow. In this demo, Bits Chat builds a workflow that investigates a monitor alert, identifies whether a recent deployment caused the issue, rolls it back when appropriate, and sends a summary to Slack.

Reliability Is the Test Agentic NetOps Has to Pass

It is 2:14 a.m. An agent has correlated a latency spike to an asymmetric routing condition and is ready to reroute traffic away from the affected path. The plan looks right. The only question that matters to the on-call SRE is whether to let it run, and that question is not really about the agent. It is about whether the picture the agent reasoned from is complete enough to trust at 2 a.m. with production on the line.

Top Tips: How to be a tech-savvy traveler

Top tips is a weekly column where we highlight what’s trending in the tech world and share ways to stay ahead. This week, let's look at a few ways you can be a tech-savvy traveler. Being a traveler is not easy, but with today's modern technology, it has become much easier. When we travel to places with no network, we sometimes forget about the ways we can use technology. Excluding the more familiar, I'm going to list some lesser-known tips. 1.
Sponsored Post

Raygun APM Agent 3.0.14: faster, simpler, and ready for ARM64

Today we are releasing Raygun APM Agent 3.0.14 for Windows, Linux, and Azure App Service. This release is the result of a substantial modernization of the Agent, profiler, installers, and release pipeline. It makes Raygun APM easier to deploy, reduces overhead in several critical paths, adds native Linux ARM64 support, and lets developers investigate APM data through Raygun API v3 and the Raygun MCP server. If you are upgrading from version 2.3.0, there is much more here than a version-number change.

Cribl On Your Coffee Break Episode 4 - Gathering REST data

In the 4th installment of our series, Leon looks at Cribl’s ability to collect REST API data. By the time the month (and the series) is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed your body weight in caffeinated beverages...

Automate Product Analytics reports with your agent and the CX CLI

Every page view, click, and session your RUM SDK captures lands in Coralogix as a log event under the cx_rum subsystem — the raw data behind how people actually use your product. You can turn it into a shareable report without writing a single query. Just ask your coding agent. Your agent queries that data through the CX CLI and writes the report for you: describe what you want in plain English, get a formatted report back — without leaving the terminal.

10 Top Website Monitoring Tools for Uptime, Page Speed and Real User Data

Your uptime tool reports the site as available all month. Support reports something else, because customers in one region spent the morning unable to complete a checkout. Both records are accurate, and that is the problem. An external check confirms the page answered. It cannot tell you that the answer took nine seconds for everyone routed through one CDN edge, or what caused the delay.

The pager shouldn't be what starts the investigation

Authored by Greg Janco, Engineering Manager at Mezmo I've always thought there was something backwards about incident response. An alert fires at 3 a.m. PagerDuty does its job. Somebody wakes up, grabs a laptop, connects to the VPN, opens the alert, and then starts answering the same basic questions we ask at the beginning of almost every incident. What changed? What else is broken? Have we seen this before? Some of those need a human eventually. A lot of the first pass doesn't.

Build and run Datadog workflows from Bits Chat or AI agents

Teams use AI coding agents and Bits Chat to troubleshoot systems and handle complex tasks, often uncovering repetitive work worth automating. But turning those routines into workflows can still require switching tools and recreating context manually. Through the Datadog MCP Server, Workflow Automation now lets you build workflows from Bits Chat or AI coding agents like Claude Code, Cursor, and Codex.

How to use Grafana auto grid dashboard option for flexible layout across devices

Learn how to use the auto-grid option, a flexible panel layout that adapts to varying screen sizes and dynamic content. Creators can now define the max number of columns or max height of panels, making dashboard layouts more responsive and maintainable.

August 2026 Early Warning Signals

August brought notable outages across developer platforms, SaaS tools, communications services, and cloud applications. StatusGator detected 789 Early Warning Signals during the month. Of those, 153 incidents (19.39%) were acknowledged by providers, while 636 (80.61%) were not officially acknowledged. StatusGator’s Early Warning Signals often surface service disruptions before providers post an official update.

Monitor prompt caching to optimize your token usage

Datadog’s 2026 State of AI Engineering report showed organizations’ LLM inputs swelling rapidly as context engineering expands. In March 2026, 69% of all input tokens in Datadog customer traces were for system prompts: internal instructions, policy definitions, and tool guidance providing context and guardrails around the user input. This suggests that most context engineering spend among Datadog customers is going toward optimizing repeating system prompts in heavily scaffolded agent systems.

Getting Started with InfluxDB 3 and Grafana Tutorial

Summary This guide walks through an end-to-end Grafana and InfluxDB 3 integration using a realistic dataset you generate yourself. The tutorial covers getting data in, transforming it, connecting Grafana, and building real dashboards. Table of Contents InfluxDB and Grafana are the most common pairing in time series monitoring, and division of labor between them is simple.

Icinga Web SSO walkthrough

The ability to log into all corporate applications with one username and password is pretty convenient, even compared to a password manager. As a benefit, the IT department can centrally enforce one desired two-factor auth mechanism. Now we, Icinga, also provide a so-called OpenID Connect integration for single sign-on. By the end of this text you’ll know how to connect your Icinga Web instance to the ID provider of your choice.

6 Signs a Dedicated Log Tool Fits Better Than a Full Observability Platform

Most growing teams eventually consolidate onto a full observability platform, and for teams correlating logs, metrics, and traces across a complex system, that’s often the right call. But a dedicated log tool still wins for a specific set of teams: ones that need to move fast, keep costs simple, and get real answers from logs without carrying the weight of a platform they don’t fully need yet. Here’s when that’s you.

SAP HANA Monitoring Tools 2026: How to Compare Options and Simplify Monitoring

If your team works with SAP HANA, the main challenge usually isn’t finding another dashboard. The real difficulty is identifying which tool can quickly help you trace vague complaints about slow transactions to their root cause. In many setups, SAP HANA monitoring is divided among native SAP interfaces, cloud monitoring, infrastructure dashboards, and the broader monitoring systems used by the rest of IT. This fragmented approach can slow down root cause analysis.

PII Redaction in Logs: Mask, Redact, Hash, or Drop?

Sensitive values reach your logs without anyone deciding they should. A debug line prints a whole request object. An error message carries the query string. A customer email address is suddenly stored in three systems. PII redaction in logs then gets treated as one setting to switch on. In practice it covers four separate treatments. The value is already inside the message before log ingestion finishes. In this blog, you will: By the end you can write a rule for each field and defend it.
The six pillars of AI-ready telemetry

“AI-ready” is everywhere right now, attached to nearly every product in every category. The catchy label rarely means anything specific, just as additional questions are warranted when vendors claim to be “AI-native”. After fighting through all the marketing jargon, there needs to be a standard, not a slogan. And the definition changes depending on what the data is for. AI-ready for a data warehouse and AI-ready for live operational telemetry are not the same problem.

Latest BGP Hijack Targets Hosting Software Vendor

This post analyzes the technical details of the BGP hijack against Softaculous Ltd, the company behind the Softaculous auto-installer and the Virtualizor VM management platform. The hijack enabled an attacker to fraudulently obtain a TLS certificate and use it to deliver a malicious Virtualizor update to a portion of the company’s customer base.

Why you should (not) build your own observability stack

If you are able to build it better than your vendor, then change your vendor. Not build it. Rishi builds large-scale observability systems at Last9, focusing on reliable and cost-efficient telemetry infrastructure, and writes about the practical lessons learned while operating ClickHouse, VictoriaMetrics, and OpenTelemetry in production.

Cribl On Your Coffee Break Episode 3 - Configuring Prometheus Remote-Write

In day 3 of our coffee break series, Leon continues to explore common observability data types and how to get them into Cribl. Today, we’ll look at setting up a simple Prometheus ingestion. By the time the month (and the series) is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed your body weight in caffeinated beverages...

Log Processing: What Happens to a Log Line Before You Can Search It

A log line arrives as plain text and leaves as a record you can query. Six steps sit between those two states. Each one adds something useful, and each one costs you time, CPU, or storage. Most teams never look at that chain until a search comes back empty. Here is what log processing does to an event, step by step: By the end you can look at your own chain. You will know what each step buys you. Six steps turn a raw log line into a searchable record.

Cloud Cost Management for Observability: A Practical Guide

Observability spend is outgrowing infrastructure budgets. What drives the cost up, how pricing models work, and a practical framework to manage it. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

Notes from the Field: Incomplete Monitoring Data After Upgrading to Citrix VAD 2603

As part of our EUC Managed Support & Consultancy Services, we regularly test new Citrix releases and investigate changes that could impact the environments we support. While upgrading a Citrix Virtual Apps and Desktops site to version 2603 in our lab, we noticed unexpected behavior in Citrix Director. After completing the upgrade, the Connections overview showed incomplete session information.

Azure integration now supports service principal authentication

We’ve released some improvements to our Azure status integration. StatusGator can now read your Azure Resource Health events via a service principal. Previously the only supported authentication mechanism was OAuth. Both pull the same data and produce the same alerts – the difference is who the connection belongs to, and what happens to it over time.

Bringing the Most Advanced Sampling to the OpenTelemetry Collector

Sampling is a core skill that everyone who runs an observability pipeline at scale will learn. There are lots of tradeoffs within the various decisions you'll make from reducing bandwidth, CPU, and memory, to reducing costs and making the observability backend's performance better for users. Historically, there have only been three mechanisms, each with their own tradeoffs: However, there is a secret fourth option: adaptive tail sampling—which changes those tradeoffs.

From traces to experiments: A loop for improving AI agents

Let’s say your team shipped a support agent last quarter. The launch demo went well, stakeholders were pleased, and everyone moved on. A few months later, things start to look off. Summaries of long conversations are truncated, and monitors show latency spikes on tool calls to the billing API. Your team’s first instinct is to ship fixes such as tweaking prompts or upgrading the model.

We Let AI Agents Rewrite a 92M-Message-a-Day Service in Go. Zero Incidents.

Our Results Daemon processes about 92 million messages a day. We recently rewrote it from Node.js to Go, and we let Claude Code write it. We wanted to know whether we could trust an agentic rewrite for a critical, high-throughput production service rather than a prototype. It shipped with zero incidents, a 70% reduction in running pods, and a lighter database load.

Best Storage Monitoring Software: 10 Tools Compared

Storage rarely fails loudly. A pool fills. Latency climbs on one LUN. The first to notice is a user whose application timed out. The best storage monitoring software catches it earlier. It watches capacity, IOPS, latency and drive health across your arrays, which is what storage resource monitoring is for. In this blog, you will see: By the end you will know which one fits. Storage monitoring software tracks the health, capacity and performance of your IT storage.

Compliance Doesn't Fail on Audit Day. It Drifts Every Day in Between.

For CIOs, compliance is no longer simply a box to check at audit time. It has become part of the operating standard for resilient, accountable, and well-managed enterprise IT. The reason is straightforward: enterprise technology environments change continuously. Infrastructure scales. Configurations change. Cloud resources move. Exceptions accumulate. Dependencies evolve across hybrid and distributed architectures.

How NIST Compliance Turns Observability Data Into Audit Evidence

Can you prove, on demand, which production systems were under continuous monitoring last quarter? Buyers, auditors, and insurers all ask a version of that question, and the answer decides contracts as often as audit findings. NIST compliance means aligning security controls and operations with standards from the National Institute of Standards and Technology, then holding evidence that the alignment stayed continuous. The frameworks are precise about outcomes and quiet about mechanics.

Visualize how CUPED adjusts experiment results with Datadog

CUPED (Controlled-experiment Using Pre-Experiment Data) is a powerful tool that can reduce metric variance and help teams obtain precise experiment results with less data. However, the difference between an experiment’s CUPED-adjusted lift and raw lift can be difficult to explain, especially when an experiment uses many pre-exposure metrics and subject properties. The CUPED adjustments visualization in Datadog Experiments breaks the difference into a sequence of specific adjustments.

AI is changing how organizations operate

AI is changing how organizations operate, but one thing has not changed: critical services cannot fail. Whether it is financial markets, healthcare, or other mission critical environments, organizations need observability that delivers value quickly, not weeks or months later. In this clip with theCube, Virtana CEO Paul Appleby explains how Virtana combines high fidelity telemetry with AI-driven intelligence to discover dependencies, correlate relationships, and deliver actionable insights within hours.

Cribl On Your Coffee Break Episode 2 - Setting up Syslog

In our second video Leon picks on Syslog (because honestly, it deserves it). Cribl is the perfect tool to whip that disorganized, loud, unruly mess of a data stream into shape. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Application Metrics caught my broken size estimator

There’s a very specific kind of frustration that comes from waiting several minutes for a video to encode, dragging it into a message, and getting hit with a “file too large” error. Then you’re blindly trying to shave off a few more megabytes by re-encoding, maybe at a lower resolution or a smaller bitrate, hoping you won’t have to do it more than one or two more times. Here’s how I used Sentry’s Application Metrics to make a more accurate video size estimator.

Data-Driven Decisions Accelerate IT Results

Modern IT teams, having moved beyond the traditional reliance on hunches and personal experience that once shaped their day-to-day choices, no longer operate on intuition, since every meaningful decision now rests upon measurable, verifiable evidence gathered from their systems and workflows. Every deployment, capacity change, and incident response now depends on measurable evidence, not guesswork. Companies that base their operations on concrete numbers ship faster, recover quicker, and allocate budgets with far greater accuracy.