Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Incident Management, On-Call, Incident Response and related technologies.

That 2am incident cost you more than downtime

It's 2:14am. A pager alert wakes an on-call engineer for a checkout failure hitting a slice of customers. By the time they've pulled the right logs, cross-checked the deploy history, and finally gotten the bug to happen again in front of them, the sun's coming up. The incident report will list two hours of downtime. It won't say anything about the day that engineer just lost, or the fact that nobody on your team could have told you in advance how long that reproduction step was going to take.
AI-Powered Incident Communications

Publish internal and external status page updates without leaving your Slack incident channel. SRE Agent brings in Scribe Agent to capture the bridge call and channel discussion, drafts the update from that context, and surfaces it in Slack for a responder to review and publish. Stakeholders stay informed. Responders stay on the fix. Now in rolling GA for customers using Slack and Status Pages.#IncidentManagement.

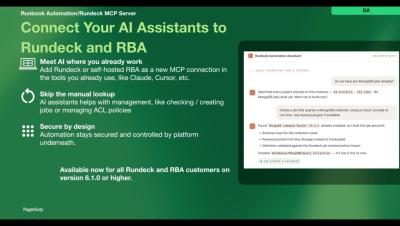
The Rundeck MCP Server: AI where your Automation lives

This blog post is part of PagerDuty’s ongoing series on how we’re helping customers navigate their journey towards autonomous operations. Read on to learn about how PagerDuty’s Runbook Automation / Rundeck MCP Server recently announced in GA builds towards this vision.

Beyond Traditional Observability: Turning Technical Insight into Operational Intelligence

Observability has become a central part of modern IT operations and for good reason. Metrics, logs and traces give technical teams detailed evidence about how applications, infrastructure and services are behaving. Such evidence helps them investigate performance degradation, identify abnormal behavior and understand what changed around the time an issue occurred.

Automated Medical Answering Services: Cost and Setup Guide

After-hours calls can create missed messages and send urgent issues to the wrong clinician. For private medical practices, that risk grows when call answering and on-call escalation rely on the same loosely defined workflow. Answering service receives an inbound call, captures information, and categorizes the request. On-call routing identifies the responsible clinician, delivers the message, and escalates it when the clinician does not respond.

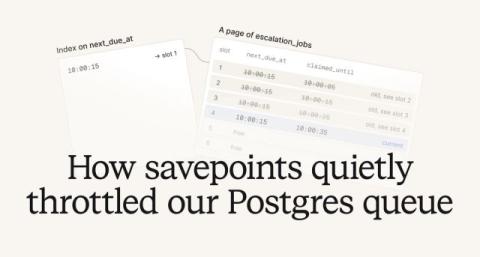
How savepoints quietly throttled our Postgres queue

At incident.io we are huge fans of Postgres; we've written about it a lot over the years, including how to choose the right indexes and how we're proud of being boring (The Pet Shop Boys). We use Postgres as our primary transactional database, which as of today has ~900 tables, and counting! The vast majority of our codebase does something along the following lines: read some data from Postgres, execute some business logic, then write that data back to Postgres. It is not, however, always that simple.

New features: ilert AI SRE GA, ilert CLI, Compass and more

ilert AI SRE is now generally available. Alongside it, this quarter brings Compass, a lifecycle assistant that surfaces the next move during an incident, a dedicated space for postmortems, rich incident cards in Microsoft Teams and Google Chat, on-call schedules that follow support hours and holidays, a new CLI, and dark mode. Here's everything that shipped.