Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

Go, Logs and the Engineering Behind VictoriaLogs Performance

What actually makes a logging system fast? That was the question behind Tech Talk. And if you were expecting the answer to be a collection of clever Go optimizations, Jesús Espino, Principal Engineer at VictoriaMetrics, made an important point pretty early in our conversation: A huge part of VictoriaLogs’ performance comes from architecture and data structures. The micro-optimizations come later. Now that gave my Tech Talk partner in crime, Mathias Palmersheim, and me plenty to dig into.
Splunk Observability Cloud and Ansible Automation Platform - How to Remediate Alerts with Ansible

Close the AIOps loop with Splunk Observability Cloud and Red Hat Ansible Automation Platform. Explore how OpenTelemetry and Event-Driven Ansible turn alerts into automated fixes, reducing manual firefighting and speeding up incident resolution.

Scout Trails Is in Beta: See What Your AI Coding Agents Are Doing

session start tool call tool call cost outcome AI coding agents have quietly become part of most engineering teams. They open files, run commands, call tools, and push changes, often for hours at a time. Yet when you want to know what an agent actually did, the answer usually lives in one developer’s terminal history, and it disappears when that session closes.

Meet Artist

Every network team keeps a dashboard backlog. A war room needs a view of one incident. A service owner wants path health for a single application. An executive review needs business impact on one page. Each request becomes a ticket for the tooling team, and the view often arrives after the moment that needed it has passed. Artist is the dashboard agent in Selector Foundry, the agentic NetOps platform built on Selector Analytics.

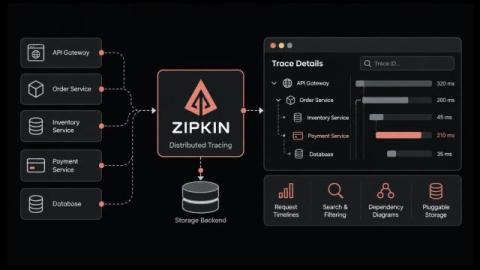
What is Zipkin and How does Distributed Tracing Speed Up Incident Resolution

If a checkout slows down or an API call fails, why can the cause stay hidden for so long while every service dashboard looks fine? One customer click in a microservices setup may hit a gateway and a few backend services first, then a queue or a database. Every hop logs its own events, yet none of those logs points back to the original request. Distributed tracing was created to solve exactly this. Zipkin arrived early, as one of the first open-source tracers.