Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

Autonomous IT: Data, Context, and Governed Action | 2H Announcement from LogicMonitor

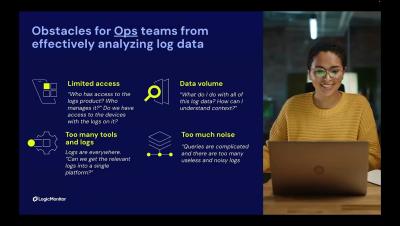
Autonomous IT requires three things: complete, AI-ready data; connected context; and governed action. In LogicMonitor's 2H announcement, we show enterprise IT and ITOps leaders how each layer works. LogicMonitor is the AI-first platform for Autonomous IT. This update covers the three layers behind autonomous IT operations as the category moves from systems of intelligence to systems of action. Your team decides when Edwin AI moves from recommending an action to taking it.
LM Logs Tips: Alert-to-Logs Workflow for Ops Team | Logs for Lunch

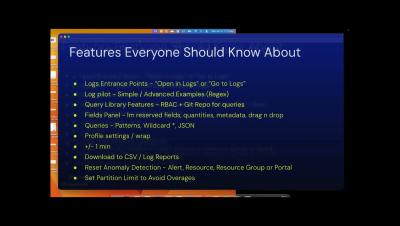
LM Logs troubleshooting starts at the alert. This Logs for Lunch session shows ITOps teams an alert-to-logs workflow and lesser-known LM Logs tips. Ryan Matuszewski demos a Tomcat application error. From the alert's Logs tab, he moves through log anomaly detection, All Logs, Log Patterns, and Log Analysis sorted by sentiment. He then opens the Logs page with the alert time range, and the same steps work for any alert type.

Cloud Log Monitoring & Root Cause Analysis | Logs for Lunch

Cloud log monitoring in LogicMonitor connects a service alert to the log event behind it. This Logs for Lunch July demo is for ITOps, CloudOps, and SRE teams. Tom Chavez hosts Ismath Mohideen (Product Marketing) and Nick Doane (Senior Sales Engineer). They cover cloud observability and multi-cloud monitoring across AWS, Azure, GCP, and OCI in LM Envision, using cloud provider APIs with no extra collectors.

SNMP Traps as Logs and Network Troubleshooting | Logs for Lunch

SNMP traps as logs, AI log anomaly detection, and network troubleshooting are the focus of Logs for Lunch: August 2026, for network and IT ops teams and LogicMonitor users. Tom Chavez introduces LM Logs, which keeps logs and metrics together. Cameron Compton troubleshoots dropped tunnel packets from a network operations dashboard, and Ron Scinta ingests SNMP traps through the Collector. Patrick Sites and Kerry DeVilbiss answer questions on load balancing, OTel and Cribl forwarding, MSP log sources, and search performance.

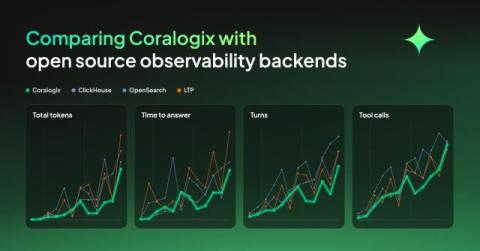
Comparing Coralogix with open source observability backends

We put the same OpenTelemetry data into four backends, Coralogix, ClickHouse, OpenSearch and a Loki, Tempo and Prometheus stack, then set an agent twelve questions against each one, from counting spans to working out what is wrong in a system it has never seen. Then we forced the agents to continue investigating until they got to the right answer. In this experiment, what separated them was the time, tokens, tool calls and turns it took to get there.

How to Find and Recover Missed Backlink Opportunities

Building a strong online presence requires more than publishing quality content and hoping other websites will link to it. Backlinks play an important role in search engine optimization (SEO), helping search engines understand a website's credibility and relevance. However, businesses often overlook valuable opportunities to earn links from websites already discussing their brand, products, or expertise. Identifying and recovering these missed opportunities can strengthen SEO performance without requiring an entirely new content strategy.
Sponsored Post

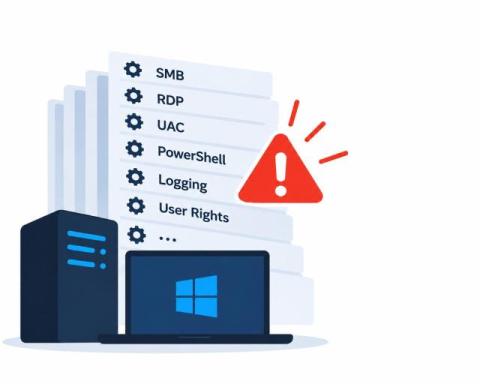
Windows Hardening & Continuous Compliance: Keeping 200+ Security Settings Secure 24/7

Every Operating System – not even counting the software installed on top of it – has a myriad of configuration settings that affect security. Windows Server alone has 4000+ configurable options, out of which 200+ are important for security & compliance efforts. They include: These settings are at the very core of all of your security & compliance efforts – and they are surprisingly often ignored.

What Is Observability? It's More Than Metrics, Logs, and Traces

Modern systems, due to their distributed nature, rarely fail in simple ways. A request might pass through an API gateway, several microservices, a database, a message queue, and a third-party service before a response ever reaches a user. When something slows down or breaks, knowing that something is wrong is only the beginning. You need to figure out.