Operations | Monitoring | ITSM | DevOps | Cloud

Latest posts

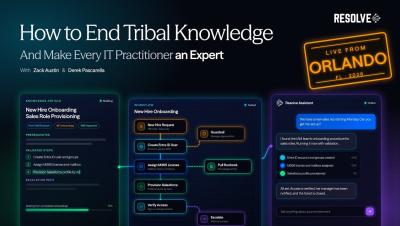
How to End Tribal Knowledge and Make Every IT Practitioner an Expert

Every IT organization has a small group of people who hold the answers everyone else depends on, and that dependency carries a cost that never appears on a dashboard. It shows up in constant interruptions, on-call rotations that keep routing back to the same names, investigations rebuilt from scratch every time an incident resurfaces, and the pressure carried by the one person who knows how the environment behaves under stress.

Self Healing Agentic Pipeline | Bitbucket Blitz | Atlassian

Ever had a broken test stop your flow? In this Bitbucket Blitz video, we look at how to setup self-healing pipelines using Bitbucket and Bitbucket Agentic Pipelines. Instead of just failing and waiting for a human, the pipeline triggers an agent when a build or test breaks on a feature branch. The agent reads the logs, finds the root cause in the source code, creates a fix branch, and opens a pull request ready for review.

Harness AI Agents

AI is writing code faster than ever. But what happens after the code is written? Harness CEO Jyoti Bansal introduces four AI agents built to automate the software delivery lifecycle: Software Delivery Agent – Automate builds, deployments, and infrastructure management. Security Testing Agent – Find, prioritize, and fix vulnerabilities with AI. Runtime Protection Agent – Protect applications, APIs, and AI agents in production.

How to Ensure Reliability of Data in the Cloud

The reliability of data is crucial when managing files in the cloud, especially for businesses, enterprises, and even the data reliability of your own personal files. In this article, we’ll cover everything about data reliability: what it is, why it’s important, assessing the reliability of data, and cloud storage solutions to keep your data protected, accurate, and complete.


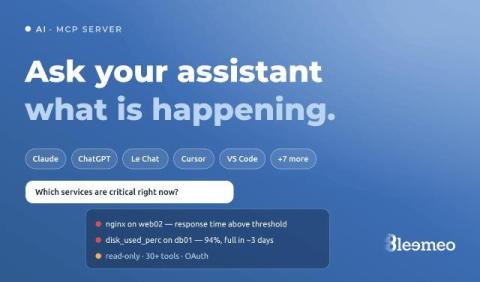
Ask Claude or Le Chat what is happening on your servers: the Bleemeo MCP server

The first minutes of an incident are spent asking questions a monitoring tool can answer but rarely in the form you asked them: which servers are in trouble right now, is it the same thing as last night, what did memory do on the web servers before it started? Each answer is a few clicks away, on a different page.

Top on-call practices for SREs (by SREs)

This September, we hosted a few of our customers at the ilert headquarters in Cologne. The plan was to share where we're heading, have real-life conversations, and give them more room to ask us questions and share their thoughts. ‍ One part of the day was a discussion about on-call culture with some of the greatest minds in SRE (source: they chose ilert as their incident management tool). We asked our customers: what are your top practices for on-call?

Best Multi-Cloud and Multi-Region Failover Solutions (2026)

The best failover solution keeps your application serving users from another location without a manual cutover. The strongest approach is active-active across two or more locations, where every location already serves live traffic, rather than restoring from backups after an outage.

The hidden cost of environment drift

Two teams, same company, same platform, same quarter. Team A ships to production three times a day. Their environments are defined in code, provisioned the same way every time, and a new engineer can get a working setup before lunch. Team B ships once every two weeks, if the release window holds. Their staging environment has diverged from production in ways nobody fully remembers approving. Getting a new engineer set up takes a week of Slack messages to whoever still remembers how it was done last time.