Operations | Monitoring | ITSM | DevOps | Cloud

Grafana Pages: Turn data into interactive experiences with the next evolution of Grafana

Teams often spend as much time preparing information as discussing it: gathering charts, checking business reports, and finding the GitHub activity that explains a change. Every follow-up question can lead to yet another round of work. That's why, as part of ObservabilityCON 2026, we're excited to introduce Grafana Pages, a new feature in Grafana Cloud that gives you a canvas to describe what you need and build a live app in minutes, based on your real data, context, and interactions.
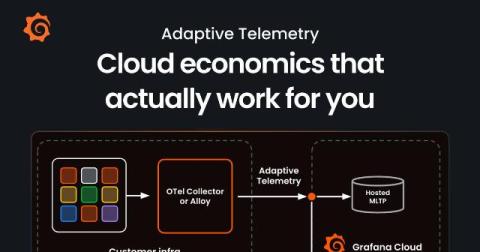
Break the link between data volume and your observability bill with Adaptive Telemetry

In the AI era, where telemetry is generated by every model call, tool invocation, and agent step, organizations need more help than ever when it comes to navigating the economics of observability. For a lot of teams, the default response is a "data diet" of shorter retention, which leaves services or environments out of collection, or basic sampling, which is more guesswork than strategy. Either way, you end up cutting to control the bill, and you risk losing the very data you need during an incident.

Full-stack observability in Grafana Cloud: More connections, richer context, and faster investigations for users and agents

Most teams have telemetry from across their stack, but connecting those signals to understand what's happening and how it affects users isn't always easy. Critical context about service dependencies, ownership, and past incidents often lives across tools, runbooks, and conversations between team members. That’s why, today at ObservabilityCON 2026, we’re announcing new capabilities that advance full-stack observability across Grafana Cloud.

Expand what's possible with Grafana: The Grafana Marketplace is now generally available

Earlier this year, we launched the Grafana Marketplace, a platform that gives independent software vendors, systems integrators, and developers in the Grafana community a new way to sell and distribute plugins built for Grafana. The Marketplace builds on our existing plugin catalog by enabling third-party partners and developers to earn revenue from their plugins and invest further in their development.

7 Best Tools for Parallel AI Coding Across Repos (2026)

Running five AI coding agents in parallel across three repositories sounds like a productivity breakthrough. In practice, it creates a coordination headache: conflicting file edits, orphaned branches, and zero visibility into which agent finished what. Parallel AI coding tools exist to solve exactly this, and Kepler by GitKraken gives you one surface to orchestrate every agent from backlog to merged pull request. This guide compares seven tools built for multi-repo, multi-agent development.

Engineering ops review agendas for startups and enterprises

It’s 9 p.m. on Sunday, and an engineering manager is pasting PagerDuty counts and Datadog graphs into a slide deck for Monday’s engineering ops review. On Monday, the first incident readout eats half the hour, the VP drops off for another call, and nobody gets to last week’s action items. Two quiet weeks later, someone cancels the meeting because nothing broke.

How to Troubleshoot TLS Handshake and Encrypted Traffic Issues with Packet Analysis

I remember the good old days, when troubleshooting application traffic often meant I could examine much of the conversation between a client and server in clear text. Not anymore. Today, nearly everything is encrypted. That is obviously a good thing for security and privacy, but it has also created a common misconception that packet analysis is no longer useful because engineers cannot see the application headers and payload.

How we used Agentic Pipelines to turn test coverage into a daily habit

Engineers write tests for the logic that worries them and let the small details slide. One of our commerce engineering teams now has a scheduled agent that finds the thinly tested files, writes the missing tests, and opens a pull request for review. Nobody decides to skip a unit test. The core logic gets covered, the small details don’t make the cut, and most days that’s a fair trade.

Service Mesh Observability: Istio, Linkerd and Envoy Metrics

Service mesh observability guide: the metrics Istio, Linkerd and Envoy proxies emit, what ambient mode changes, and why tracing still needs app changes. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

How to Ensure Reliability of Data in the Cloud

The reliability of data is crucial when managing files in the cloud, especially for businesses, enterprises, and even the data reliability of your own personal files. In this article, we’ll cover everything about data reliability: what it is, why it’s important, assessing the reliability of data, and cloud storage solutions to keep your data protected, accurate, and complete.