Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Observabilty for complex systems and related technologies.

Observability Never Really Shifted Left

We made software development faster. Now we need to make validation faster, too. For the last decade we have shifted development left. Testing, security, performance, and CI/CD all moved closer to the developer. Observability mostly did not. It still starts after deployment (we covered the incident side of this in Your Observability Stack Found the Fire), which means the people writing the code rarely have meaningful production behavior to observe while they build.
Honeycomb Adds Another AWS Competency: Resilience Technology

We're excited to share that Honeycomb has achieved yet another Amazon Web Services (AWS) Competency—the Resilience Technology Competency—which recognizes our ability to help customers detect, investigate, and recover from failures in production systems running on AWS. While receiving the competency designation is a fantastic recognition of the capabilities of the Honeycomb platform (we also received one in Financial Services earlier this year), it's ultimately not the point.

The Root Cause Agent: Bring an agentic approach to observability

For years, engineering teams have faced the same challenge during incidents: the systems generating alerts are becoming more complex, but the investigation that follows is still largely manual. Monitors are good at telling us that something is wrong. The harder question is why. When an alert fires, an engineer still has to work out where to look, which signals matter, what hypothesis to test, and how the evidence across logs and metrics fits together.

The Business Side of Observability: Ramazan Karadavut on Customer Value and SolarWinds

In this episode of SolarWinds World Tour Conversations, we sit down with Ramazan Karadavut, Founder & Senior Architect at Consolit, to discuss his 20-year journey with SolarWinds and the power of end-to-end IT management. We explore real-world enterprise use cases, including monitoring large-scale banking networks across 10,000+ branches, and thousands of ATMs. We will also explore why moving beyond basic alerting into inventory management, change management, and investment reporting is essential for complex environments.

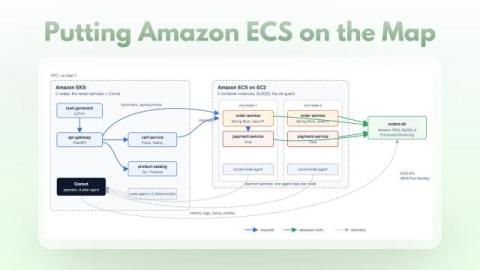
Putting Amazon ECS on the map

Say "ECS" and most people picture serverless containers: no nodes to manage, and nothing underneath you are allowed to touch. For an eBPF-based agent that is a dead end. There is no host to run on, no privileged containers, no kernel to attach to. But ECS is not always serverless. With the EC2 launch type you bring the nodes and ECS brings the scheduler: task definitions, services, rolling deployments, daemons, placement.

Observability is a data problem

TL;DR Metrics, logs, and traces each have a different shape, so each needs a different backend. Aiven for Metrics handles metrics and alerting, Aiven for OpenSearch handles keyword search across logs, and Aiven for ClickHouse handles analysis of high-volume, high-cardinality events. All three are upstream open source engines on the same Aiven platform, so you can start with one and add the others as your needs change.

We Ran Minecraft on 4 Raspberry Pis with Kubernetes and Monitored it with Open Source

Why did we do this? Not important: jump to 1:31 to see the Pis. TL;DR: We stuck Minecraft on kubernetes running on 4 Raspberry Pis in a 3D-Printed case, and monitored it with open source observability. Huge thanks to Percona DBA Ivan Zaitsev for putting the demo together for Percona University, Montevideo. Coroot automatically collects and visualizes all your telemetry data: logs, metrics, traces, profiles, and a complete map of your services. With the complete context of eBPF, it can diagnose the exact cause of an incident in seconds, and show you the exact commands to fix it.

OpenTelemetry Collector Configuration for LLM Observability

Your LLM application emits telemetry unlike anything else in your stack. Model calls, tool invocations, retrieval steps, and token usage arrive as spans whose attributes carry entire prompts and completions. That data is bulky, it's full of user content you may not be allowed to export, and depending on which instrumentation each service uses, the same fact can arrive under different attribute names.