Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

Incident Response Automation: A Practical Playbook

A stage-by-stage playbook for automating incident response: what to automate at detection, triage, and remediation, what to deliberately leave manual, and a checklist to run against your current setup. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.
Observability Masterclass | Trust Before Autonomy: A Framework for AI in Observability

How to Prepare for Human-in-the-Loop AI in Observability AI is rapidly reshaping IT operations, but pushing forward blindly introduces massive risks. To scale automation safely, your teams need the right foundation in place. Join SolarWinds experts for a tactical session on how to strengthen data quality, eliminate tool fragmentation, and establish clear governance guardrails. Discover how to confidently transition from human-managed workflows to safe, guided AI autonomy.

Cribl On Your Coffee Break Episode 1

In this first episode (or at least the first REAL episode, yesterday’s “episode 0” doesn’t count) of Cribl on your coffee break, Leon does what we all do when we unwrap a shiny new data, telemetry, observability, or monitoring tool: He takes the shortest path to jamming some data into that thing and seeing what it looks like. Is it sophisticated? Nuanced? Well-thought-out? Hell no! But it scratches an itch. There will be time to do more real-world stuff tomorrow.

Smarter Device Refresh Decisions with Teneo Managed Digital Employee Experience (DEX)

How do you know which employee devices really need to be replaced? Teneo Managed Digital Employee Experience (DEX) gives IT teams the visibility and data they need to make smarter device refresh decisions based on actual device health and user experience.

Why Most Enterprise AI Agent Programs Overspend, and What Actually Fixes It

Enterprise AI agent programs overspend because leaders optimize token costs, which represent just 20-25% of variable run costs. Human oversight accounts for 70-75%. The real fix is reducing exception rates and embedding governance directly into agent execution from the start.

How Bits Database Optimization proves a query rewrite is faster

A frequently encountered issue when exploring database optimizations is proving that a proposed query rewrite is actually faster than the existing query. Often, proving this isn’t just as simple as running both queries and comparing their execution times. When your hot queries are measured in milliseconds, factors such as cache states, concurrent queries competing for CPU and I/O, and noisy neighbors can mask the true performance difference between query versions.

Troubleshoot and secure your code faster with Datadog's Bitbucket Cloud Source Code integration

Developers and SREs who use Bitbucket Cloud often need to move between their source code, observability data, test results, and security findings to investigate a problem. Connecting an error or slow method to the correct repository, file, and commit takes time. Teams may also discover vulnerabilities, infrastructure misconfigurations, coverage regressions, or flaky tests only after code has progressed further through the software development life cycle, when remediation is more disruptive.

NestJS v12 Ships Native Observability: What It Means for Your APM

NestJS 12 dropped last week with ESM packages, Standard Schema validation, a rebuilt CLI, and a brand-new observability SDK. That last one is the most interesting part for anyone running NestJS in production with an APM tool. At Scout Monitoring, we instrument NestJS applications through our Node.js agent. A framework shipping its own observability layer changes the conversation for every APM vendor in the ecosystem, including us. Here is what you need to know.

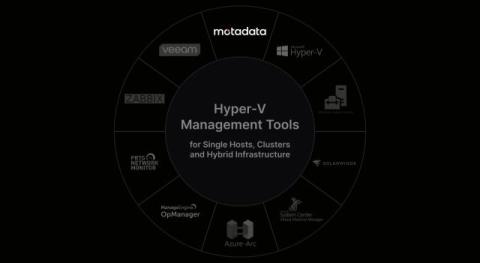
10 Top Hyper-V Management Tools for Single Hosts, Clusters and Hybrid Infrastructure

An application slows down every month-end. You open Hyper-V Manager, the virtual machine looks healthy, and the ticket closes without a cause. Next month it happens again. Native consoles show live state and keep no history behind it, so nobody can prove whether the fault was the guest, the host, or a storage path shared with nine other workloads. That gap sets what a Hyper-V deployment costs to run, measured in unplanned downtime and in engineering hours spent guessing. This guide covers.