Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Containers, Kubernetes, Docker and related technologies.

Sharing GPUs without Flying Blind: Kubernetes Patterns for AI Inference

GPU sharing is quickly becoming a practical requirement for Kubernetes-based AI inference, as many modern workloads don’t need a full GPU to deliver value. But safely placing multiple containers on the same accelerator brings new challenges: scheduling, fairness, isolation, observability, and noisy-neighbor behavior. This 20 min session explore the GPU sharing landscape across Kubernetes: time-slicing, MPS, MIG, KAI Scheduler, and HAMi, and dives into the harder problem: operating shared GPUs in production, from tracking usage to enforcing fairness as demand shifts.
Private cloud disaster recovery: How to design for business continuity without public cloud dependency

Disaster recovery (DR) is one area where organizations often assume public cloud has the answer already. Multi-region deployments, managed backup services, automated failover - the hyperscaler catalog is full of DR-flavored offerings, and the marketing suggests that resilience is a solved problem once you're on cloud infrastructure. For many workloads, this is roughly true.

The Pod Was Cheaper. The Service Wasn't.

A smaller Kubernetes pod can lower allocation cost while completing less work. Green status codes and matching schemas can hide it. This walkthrough combines OpenCost allocation data with proxymock behavior and performance evidence. A candidate passes only when behavior and throughput hold while unit cost falls.

Digital Sovereignty: Is your data really yours?

Digital sovereignty is one of the most talked-about terms in cloud and AI right now. But what does it actually mean in practice? Civo Product Director Russ Smith gives his honest take: sovereignty isn't just about where your data is stored. It's about whether someone else can switch it off, access it, manipulate it, or determine what you can do with it. If they can, it's not sovereign.

Data localization for Indian Fintech: RBI rules and your cloud choice

Indian fintech operates under one of the most specific data localization regimes in the world. The Reserve Bank of India has published progressive guidance since 2018 requiring payment system data to be stored in India, with subsequent extensions to other categories of financial data. The rules aren't optional. For fintechs operating in India - whether payment providers, lending platforms, wealth managers, or neo-banks - the localization requirements shape fundamental infrastructure choices.

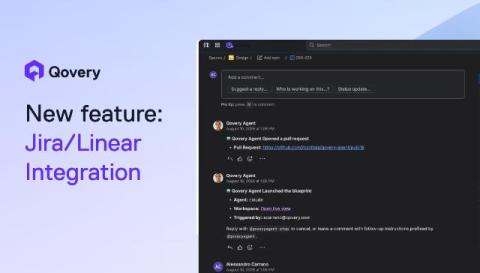
Jira and Linear Are Now a Trigger Into Your Governed Infrastructure

Agent Triggers extend Qovery's control plane to a new entry point: a ticket. Tag it on Jira or assign it on Linear, and it triggers the execution of a governed environment on your own infrastructure, where an agent performs whatever action it's configured for, given the context of that ticket, under the same guardrails as any other workload. Alessandro leads product at Qovery. He drives the changelog, roadmap, and product strategy - turning customer feedback into platform capabilities.

India's DPDP Act: What it means for where you host your data

India's Digital Personal Data Protection Act, passed in 2023 and enforced through subsequent rules, has reshaped the landscape for data hosting decisions for anyone processing personal data of Indian residents. The Act creates specific obligations that map directly onto infrastructure choices: where data can be stored, how consent has to be managed, what security measures are required, and what happens if things go wrong.

Inference Optimization Techniques. Ray vs. vLLM vs. KubeRay

Serving large language models at scale is fundamentally a distributed systems problem. A single GPU, or even a single node, is rarely enough once you need multiple models, multiple replicas, tensor-parallel sharding across GPUs, or high-availability rollouts. Kubernetes solves general container orchestration well, but it has no native concept of a GPU-aware, actor-based compute cluster.

GPU Cloud security: Isolation, multi-tenancy, and protecting sensitive training data

GPU cloud security tends to get discussed as if it's the same problem as general cloud security. It isn't. GPUs sit between processes in ways CPUs don't. Training data passes through them in patterns that create specific exposure. Model weights derived from sensitive data are themselves sensitive material in ways most procurement processes don't recognize. And the multi-tenant nature of public GPU cloud creates failure modes that don't exist in CPU-only environments.

Kernel-Level Visibility Without Instrumentation: What eBPF Changes for Container Security

Containers have changed how applications are built and deployed, but they have also made security visibility more difficult. Workloads are short-lived, services communicate constantly, and application behavior is distributed across containers, nodes, APIs, processes, and open-source dependencies. This is why many security teams are pairing eBPF with application-level runtime security. eBPF observes activity from the Linux kernel without requiring teams to modify every application, while runtime application security explains which code caused that activity.