The best open source LLMs by family: DeepSeek V4 for frontier reasoning under MIT, Qwen3.8 and Gemma 4 for clean Apache 2.0 licensing, GLM-5.3 for coding, Kimi K3 for long context, Llama 4 for single-GPU scale. The real ranking depends on your deployment lane and token volume, and this guide prices all three lanes. At CloudZero, Bill Buckley, our SVP of Engineering, gives every engineer a $5,000 monthly AI token budget and published the math behind it.
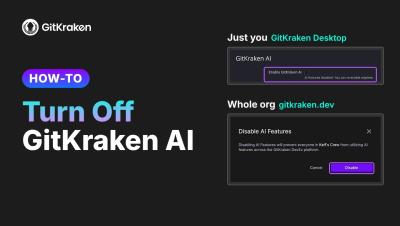
Let's talk about 2 ways to turn off GitKraken AI: for your own account in GitKraken Desktop, and for everyone in your organization from gitkraken.dev. Turn off GitKraken AI for your account (GitKraken Desktop) Turn off GitKraken AI for your organization (admins and owners) Optional: limit AI providers On the same Security controls page, under Enforce AI providers, turn off any provider you don't want your organization to use.
Developers use Bitbucket Cloud every day to turn plans into working software. Code lives in repositories, feedback happens in pull requests, and Bitbucket Pipelines helps teams validate changes before they move forward. For an AI assistant to help with this work, it needs access to the same information. Without a direct connection, developers have to gather pull request details, pipeline results, logs, and links before the assistant can help.
It’s 2:14 am, and checkout latency at your largest retail store has tripled. Your observability platform’s agent has already posted to Slack that there is a connection pool exhaustion on the orders database, with a link to the trace. Your cloud provider’s agent reports a degraded network path in one availability zone. The AI SRE tool one of your product teams adopted last spring points to a deploy that went out at 1:50.
AI Is Writing More Code. So Why Aren't Teams Moving Faster? AI can generate 10x, 100x, or even 1,000x more code. But there's a problem: companies aren't necessarily delivering software any faster. As AI accelerates development, it's exposing the bottlenecks, technical debt, and outdated processes that have been slowing engineering teams down all along. So what happens when the solution isn't more developers or better AI tools, but actually smaller teams?
Using more AI and adding lots of contributions, but not understanding the project, will not scale long-term. OpenTelemetry, like other OSS and cloud native projects, is looking for contributors who care about the ecosystem and genuinely want to learn and support the project. Resources for Further Learning.
At home I run fully automated coding loops on a few side projects. They use more than 100-million tokens a day. At Claude Opus 5.5 prices, that costs more than $5,300 a month. For hobby projects. The same usage on DeepSeek V4.1 Flash cost about $330 a month, one sixteenth of the price. If we want to keep scaling how much we use AI, most of those tokens have to run on open models, period.