Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Cloud monitoring, security and related technologies.

Top 10 Heroku Alternatives

Heroku is not shutting down. On February 6, 2026, Heroku CPO Nitin T Bhat announced that the platform was moving to a sustaining engineering model: new feature development has stopped, but Heroku remains actively supported and production-ready. There is no announced EOL date or migration deadline, existing apps can keep running, credit-card customers can continue using the service, and existing Enterprise customers can renew. What changed is the roadmap, not immediate availability.

The 5 Levels of Running Coding Agents

If you're trying to run more than a few AI coding agents at once, the real problem shifts from prompting to managing where they live and what they can reach. This video walks through the five levels of agent management, from the IDE all the way to a fleet running in the cloud with access to your own services.

Hybrid cloud management: 6 challenges IT teams need to solve in 2026

In 2026, a hybrid cloud is no longer something organizations are working toward; it's already where they are. According to Forrester's The State Of Cloud Series 2026, the vast majority of enterprises across major markets, including the United States, India, Australia and New Zealand, Canada, and the Asia-Pacific region, are running some form of a hybrid cloud, combining public cloud platforms with private infrastructure, colocation data centers, and sovereign cloud providers.

DHCP tells you what was leased. It does not tell you what is answering.

Your DHCP server knows which addresses it assigned. It does not know which of those addresses are answering on the wire right now. That gap shows up in every hybrid network where static devices, reservations, and stale leases sit beside active workloads. Leased and live are different questions. DHCP scopes answer the first. Subnet ping-sweep answers the second. Together they give IPAM fresher last-seen context without handing an NMS credentials across the network.

GPT-6 Astra pricing: What OpenAI's new flagship costs in 2026

GPT-6 Astra is OpenAI's flagship reasoning model, released September 3, 2026. It costs $10 per million input tokens and $50 per million output tokens on the standard API tier, with cached input at $1 and cache writes at $12.50. That is 2.5 times GPT-5.6 Sol's promotional rate and matches Anthropic's Fable 5.1 on both headline numbers. Batch and Flex halve those rates, Fast mode doubles them, and any prompt past 272K input tokens reprices the entire request.

AI cost calculator: estimate your total spend

An AI cost calculator for the whole wallet adds four lanes: seats and subscriptions, API and token usage, cloud AI services, and GPU infrastructure. Average 2026 totals run $25 per employee per month at light adoption, $100 to $150 at active adoption, and $300 or more at AI-heavy companies. Getting to your number takes four lane subtotals and three corrections.

How to verify your Azure Application Gateway is zone-redundant

Having a redundant failsafe is one of the best things you can do to ensure high availability in the cloud. It’s rare for cloud regions to go offline, but it can happen, even on major platforms like Azure. While you might not have control over your provider’s reliability, you do have control over your own, and redundancy is a key part of that. Here’s how you can check if your Application Gateways are availability zone (AZ) redundancy, and how to verify redundancy using active testing.

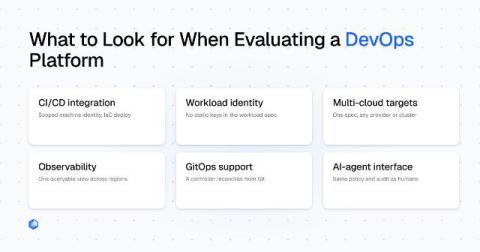
What to Look for When Evaluating a DevOps Platform

DevOps platform feature lists increasingly look alike. CI/CD, multi-cloud, observability, GitOps, and AI-friendly automation can all appear as checkboxes while the implementation burden still falls on your team. The useful signal appears when you ask how each capability actually works, what evidence a vendor can show, and which parts your team still has to build. Can pipelines authenticate with a scoped machine identity? Can workloads reach cloud APIs without static keys?

Making Shared GPUs Even Safer with Kubex and HAMi-core

Table of Contents A few months ago, we introduced Kubex support for the KAI Scheduler to improve GPU sharing for production inference workloads. The basic model is simple: The KAI Scheduler handles placement and GPU sharing. Kubex continuously observes usage and adjusts those allocations as demand changes. KAI provides the scheduling foundation. It lets multiple workloads share a GPU while accounting for the amount of GPU each workload requests. Kubex then closes the loop.