Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Observabilty for complex systems and related technologies.

How Observability and Real-Time Data Can Improve Warehouse Operations

Warehouse operations generate a constant stream of information. Goods are received, inventory moves between locations, orders enter picking workflows, stock levels change, and shipments leave the facility. When these activities are managed through disconnected systems or delayed manual updates, managers can struggle to understand what is actually happening on the warehouse floor.

Relational Query Superpowers

I'm investigating repeated errors in my e-commerce application, and I need to get enough context in a single Honeycomb query to piece the entire picture together. Each query returns events based on the event's WHERE clauses, but I want to know several things from outside of the event that recorded an error. Things like: Those attributes are all over the trace. That's going to make a single query tough, right? Wrong!

Live Debugging for Critical Systems: MTBF, MTTR & MTTA

A critical system has to stay reliable without new failures or added downtime, and live debugging, confirming the root cause without stopping the system, is often the only way to do that. In practice, this means having runtime context: on-demand evidence generated at the point of failure rather than logging configured months earlier, which is what keeps MTBF up, MTTR, and MTTA down.

Cribl On Your Coffee Break Episode 4 - Gathering REST data

In the 4th installment of our series, Leon looks at Cribl’s ability to collect REST API data. By the time the month (and the series) is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed your body weight in caffeinated beverages...

Cribl On Your Coffee Break Episode 3 - Configuring Prometheus Remote-Write

In day 3 of our coffee break series, Leon continues to explore common observability data types and how to get them into Cribl. Today, we’ll look at setting up a simple Prometheus ingestion. By the time the month (and the series) is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed your body weight in caffeinated beverages...

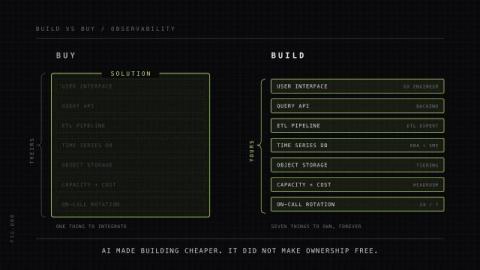
Why you should (not) build your own observability stack

If you are able to build it better than your vendor, then change your vendor. Not build it. Rishi builds large-scale observability systems at Last9, focusing on reliable and cost-efficient telemetry infrastructure, and writes about the practical lessons learned while operating ClickHouse, VictoriaMetrics, and OpenTelemetry in production.

Cloud Cost Management for Observability: A Practical Guide

Observability spend is outgrowing infrastructure budgets. What drives the cost up, how pricing models work, and a practical framework to manage it. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

Bringing the Most Advanced Sampling to the OpenTelemetry Collector

Sampling is a core skill that everyone who runs an observability pipeline at scale will learn. There are lots of tradeoffs within the various decisions you'll make from reducing bandwidth, CPU, and memory, to reducing costs and making the observability backend's performance better for users. Historically, there have only been three mechanisms, each with their own tradeoffs: However, there is a secret fourth option: adaptive tail sampling—which changes those tradeoffs.