Operations | Monitoring | ITSM | DevOps | Cloud

When users don't click thumbs up: Inferring agent feedback from Datadog telemetry

Collecting high-quality user feedback on agents, like from thumbs-up or thumbs-down buttons, is an important part of agent development. User feedback is needed for everything from basic gut checks on whether your agents are behaving well to planning and creating robust eval sets. It’s a critical part of Datadog’s Agent Observability, which provides explicit end-user feedback features for collecting and analyzing it.

Cut AI agent cost and improve accuracy with Code Execution in the Datadog MCP Server

Observability investigations rarely follow a straight line. A latency question might cause an AI agent to start with a metric, pivot into traces, compare a deployment window, and finish by reducing thousands of logs to a few patterns. Each individual query is easy, but propagating context throughout an entire investigation can be tricky and expensive.

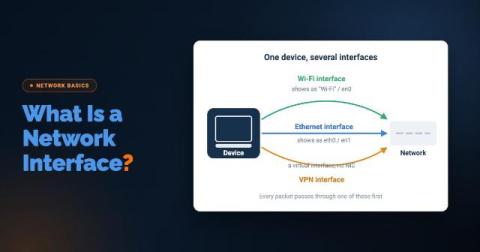
What Is a Network Interface (and Why Your Monitoring Tool Should Care)

A user opens a ticket: "The Internet is slow." IT checks the network. Bandwidth looks fine, no outages, no alerts firing. They check with the ISP, but nothing on their end either. Everything upstream checks out, and yet the user is still stuck watching a spinning wheel. What rarely gets checked is the one component sitting closest to the problem: the machine's own network interface.

17: There's No Life Without AI: Agents, MCP, and the Future of Automation With Viktor Farcic

On this episode of Kubex Talks, technology critic Viktor Farcic returns to talk with Andrew Hillier about the rapidly changing landscape in tech. Viktor has gone from AI skeptic to believer, claiming that there really is no life without AI anymore, from a professional standpoint.

How to Send Critical Alerts to the OnPage App | 3 Ways

What are the different ways to send a critical alert to the OnPage app? This video shows three ways people and external systems can trigger a high-priority OnPage mobile alert that's also HIPAA compliant (secure or healthcare use cases): These options are particularly useful for users with OnPage mobile licenses who do not have a Silver or Gold plan.

Best LLM inference providers 2026: 16+ on cost per outcome

An LLM inference provider hosts open-weight models like Llama, DeepSeek, and Qwen behind a pay-per-token API, handling GPUs, scaling, and serving for you. The same Llama 3.3 70B model ranges from $0.10 to $1.04 per million input tokens depending on who serves it, so provider choice is a pricing decision. Top picks as of September 2026: Groq and Cerebras for speed, DeepInfra for price, Together and Fireworks for breadth, Baseten for custom models.


Distributed Tracing Is Now in Beta for Ruby, PHP, and Python

A request comes in, enqueues a job, and returns. Twenty seconds later the job runs, and it’s slow. You have a trace of the request and a trace of the job, and nothing joining them. Time Detective has always helped you reconstruct what happened. Now we join it up for you, across applications, services, background jobs and infrastructure, even when they’re built in different languages.