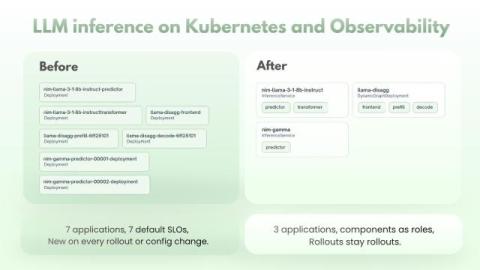
LLM inference on Kubernetes and observability
Running an LLM on Kubernetes is rarely just a Deployment with vLLM in it anymore. A whole layer of frameworks and operators has grown up for it: KServe, NVIDIA Dynamo, Ray Serve, Kthena, llm-d. Each one adds its own custom resource that describes a model deployment, with routing, autoscaling and the split of a model across pods built in, and each one turns that resource into ordinary Kubernetes objects in its own way.