Operations | Monitoring | ITSM | DevOps | Cloud

The 5 levels of the AI software factory for enterprises | EVOLVE 2026 keynote

Everyone online seems to have a fully autonomous SDLC. Most enterprises are still at level 3, and they'll be there for years. In the EVOLVE 2026 opening keynote, Cortex co-founders Anish Dhar (CEO) and Ganesh Datta (CTO) lay out a practical maturity model for getting from AI coding agents to an AI software factory without blowing up cost, quality, or security along the way. They've watched hundreds of engineering orgs adopt AI over the last two years. This talk distills what separated the successful rollouts from the chaotic ones.
Governing AI Agents From the Inside: What We Learned Building AgentIQ

When every employee is building AI agents, seeing what they did afterward isn't enough. AgentIQ's in-flow governance runs inside the agent's execution flow—pausing for human approval, enforcing policies by value, masking PII, and stopping runaway agents before costs spiral.

Seer Agent: Get Answers. Take Action.

This video walks through what it looks like to treat Sentry's Seer agent the way you already treat a chatbot, asking it plain language questions about your own production application. From Slack or inside your Sentry account, Seer Agent can answer questions with real context: the affected spans, the recent release, the likely cause. Seer doesn't stop at answering questions. Ask it to act on what it just told you and it completes that work inside Sentry, serving as an assistant to your projects, team workflows, and your future self.

Solving AI Latency and Cost Problems with Valkey - Aiven Webinar

LLM providers charge you for caching, and they do it on their terms. You can run it yourself for a fraction of the cost. In this Aiven webinar, Jay Miller (Staff Developer Advocate) shows how to use semantic caching and semantic routing on Valkey to cut prompt costs + latency. You'll see a working demo, "Template Scout", that searches GitHub for deployable repos and picks the cheapest model that can answer each question.

Governing AI Agents From the Inside: What We Learned Building AgentPatrol

When every employee is building AI agents, seeing what they did afterward isn't enough. AgentPatrol's in-flow governance runs inside the agent's execution flow—pausing for human approval, enforcing policies by value, masking PII, and stopping runaway agents before costs spiral.

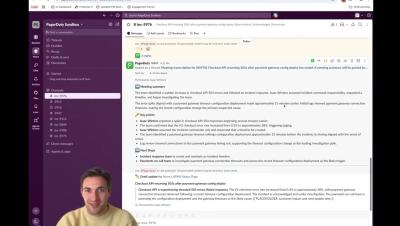
AI-Powered Incident Communications

Publish internal and external status page updates without leaving your Slack incident channel. SRE Agent brings in Scribe Agent to capture the bridge call and channel discussion, drafts the update from that context, and surfaces it in Slack for a responder to review and publish. Stakeholders stay informed. Responders stay on the fix. Now in rolling GA for customers using Slack and Status Pages.#IncidentManagement.

OpenTelemetry Collector Configuration for LLM Observability

Your LLM application emits telemetry unlike anything else in your stack. Model calls, tool invocations, retrieval steps, and token usage arrive as spans whose attributes carry entire prompts and completions. That data is bulky, it's full of user content you may not be allowed to export, and depending on which instrumentation each service uses, the same fact can arrive under different attribute names.

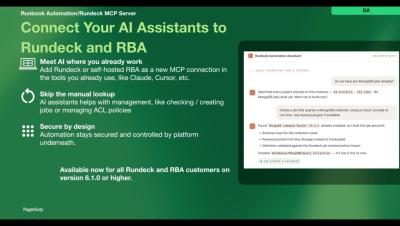
The Rundeck MCP Server: AI where your Automation lives

This blog post is part of PagerDuty’s ongoing series on how we’re helping customers navigate their journey towards autonomous operations. Read on to learn about how PagerDuty’s Runbook Automation / Rundeck MCP Server recently announced in GA builds towards this vision.