Operations | Monitoring | ITSM | DevOps | Cloud

7 Best Tools for Parallel AI Coding Across Repos (2026)

Running five AI coding agents in parallel across three repositories sounds like a productivity breakthrough. In practice, it creates a coordination headache: conflicting file edits, orphaned branches, and zero visibility into which agent finished what. Parallel AI coding tools exist to solve exactly this, and Kepler by GitKraken gives you one surface to orchestrate every agent from backlog to merged pull request. This guide compares seven tools built for multi-repo, multi-agent development.
Engineering ops review agendas for startups and enterprises

It’s 9 p.m. on Sunday, and an engineering manager is pasting PagerDuty counts and Datadog graphs into a slide deck for Monday’s engineering ops review. On Monday, the first incident readout eats half the hour, the VP drops off for another call, and nobody gets to last week’s action items. Two quiet weeks later, someone cancels the meeting because nothing broke.

How to Troubleshoot TLS Handshake and Encrypted Traffic Issues with Packet Analysis

I remember the good old days, when troubleshooting application traffic often meant I could examine much of the conversation between a client and server in clear text. Not anymore. Today, nearly everything is encrypted. That is obviously a good thing for security and privacy, but it has also created a common misconception that packet analysis is no longer useful because engineers cannot see the application headers and payload.

How we used Agentic Pipelines to turn test coverage into a daily habit

Engineers write tests for the logic that worries them and let the small details slide. One of our commerce engineering teams now has a scheduled agent that finds the thinly tested files, writes the missing tests, and opens a pull request for review. Nobody decides to skip a unit test. The core logic gets covered, the small details don’t make the cut, and most days that’s a fair trade.

Service Mesh Observability: Istio, Linkerd and Envoy Metrics

Service mesh observability guide: the metrics Istio, Linkerd and Envoy proxies emit, what ambient mode changes, and why tracing still needs app changes. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

How to Ensure Reliability of Data in the Cloud

The reliability of data is crucial when managing files in the cloud, especially for businesses, enterprises, and even the data reliability of your own personal files. In this article, we’ll cover everything about data reliability: what it is, why it’s important, assessing the reliability of data, and cloud storage solutions to keep your data protected, accurate, and complete.

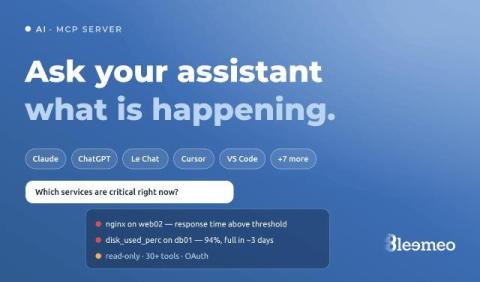
Ask Claude or Le Chat what is happening on your servers: the Bleemeo MCP server

The first minutes of an incident are spent asking questions a monitoring tool can answer but rarely in the form you asked them: which servers are in trouble right now, is it the same thing as last night, what did memory do on the web servers before it started? Each answer is a few clicks away, on a different page.

Top on-call practices for SREs (by SREs)

This September, we hosted a few of our customers at the ilert headquarters in Cologne. The plan was to share where we're heading, have real-life conversations, and give them more room to ask us questions and share their thoughts. ‍ One part of the day was a discussion about on-call culture with some of the greatest minds in SRE (source: they chose ilert as their incident management tool). We asked our customers: what are your top practices for on-call?

Best Multi-Cloud and Multi-Region Failover Solutions (2026)

The best failover solution keeps your application serving users from another location without a manual cutover. The strongest approach is active-active across two or more locations, where every location already serves live traffic, rather than restoring from backups after an outage.