Operations | Monitoring | ITSM | DevOps | Cloud

Marketing Got an On-Call Rotation

A broken campaign used to be a Monday problem. Someone spotted the dead landing page on the way into standup, a producer paged the agency, and the fix landed by lunch. The team that caused it wrote a note to themselves and moved on. That worked when a campaign was something you shipped and then watched. It falls apart when the campaign is a live system: a retargeting pool refreshing every fifteen minutes, a generative answer that reads your product pages overnight, a chatbot quoting last quarter's pricing because nobody updated the source doc.
Top on-call practices for SREs (by SREs)

This September, we hosted a few of our customers at the ilert headquarters in Cologne. The plan was to share where we're heading, have real-life conversations, and give them more room to ask us questions and share their thoughts. ‍ One part of the day was a discussion about on-call culture with some of the greatest minds in SRE (source: they chose ilert as their incident management tool). We asked our customers: what are your top practices for on-call?

5 Signs Your In-House Ops Team Has Hit Its Ceiling (And What to Do Next)

Every small ops team reaches a point where the work outgrows the people. Tickets arrive faster than they close, the pager goes off at 2 a.m. for the third time this week, and the roadmap quietly slips another quarter. Leadership sees missed deadlines. The team sees a system with no slack left in it. The hard part is spotting the ceiling before it turns into attrition or an outage. This article covers five warning signs that a team is stretched too thin, then shows how to decide what to keep in-house and what to hand off.

Your On-Call Rotation Has a Single Point of Failure, and It Gets the Flu Every Winter

Most teams design on-call for the failures they can see in a dashboard. A region goes down, a deploy goes sideways, a certificate expires at 2 a.m. The rotation exists so that someone is always there to catch it. Far fewer teams design for the failure that takes out the catcher: the on-call engineer wakes up with a fever, and the plan for that is usually a Slack message and hope. Treat a sick engineer the way you would treat any other dependency outage. It is predictable, it is seasonal, and it has a blast radius that grows with every shortcut in the rotation design.

The Context Switching Cost of On-Call Work, and How Teams Reduce It

Ask an engineer what on-call costs them and most will describe a page at three in the morning. Those nights are real, and they are also comparatively rare on a healthy rota. Teams plan for them, compensate for them, and talk about them openly. The larger cost is quieter and almost never discussed, because it does not look like an incident. It is what happens to an ordinary Tuesday when you are carrying the pager: work arrives in fragments, nothing deep gets finished, and by Friday you have been busy for five days without being able to say what you built.

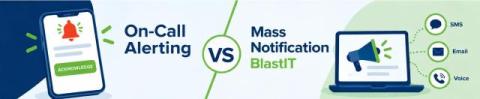
On-Call Alerting vs. Mass Notification: What's the Difference?

When an urgent situation occurs, organizations need more than a way to send a message. They need a communication strategy that considers who needs to receive the message, whether they need to take action and how quickly they need to respond. This is where the difference between on-call alerting and mass notification becomes important. A critical IT incident, for example, may require an immediate response from a specific on-call engineer or incident response team.

Google Calendar On-Call Rotation Template

Most teams building an on-call rotation template in Google Calendar get the first two steps right and the third one wrong. Creating a shared calendar is easy. Inviting the team is easy. Expressing "four people, one week each, forever, handing off Monday morning" as a set of recurring events is where it falls apart, usually into a mess of one off entries that someone has to rebuild by hand every quarter.

24/7 On-Call Coverage With a Small Team

Running 24/7 on-call coverage with a small team is first of all an arithmetic problem, and most teams avoid doing the arithmetic because the answer is uncomfortable. There are 168 hours in a week. Your engineers work roughly 40 of them. Somebody has to be reachable for the other 128, and if you have four engineers, that somebody is each of them, one week in four, thirteen weeks a year.

How to Design an On-Call Escalation Policy That Works

An on-call escalation policy is the part of your incident response that runs when nobody is looking. It fires at 3:14am, decides who gets woken up, decides how long to wait before waking up somebody else, and decides when to stop trying. Most teams write one in an afternoon, wire it to a rotation, and never touch it again until an incident goes badly and the retro asks the uncomfortable question: why did it take forty minutes for a human to acknowledge?

How to Write Runbooks Your On-Call Team Actually Uses

Most engineering teams have on-call runbooks. Very few have on-call runbooks that anyone opens during an actual incident. The document exists, it was written with good intentions during a quiet sprint, it is linked from a wiki page called "Operations", and when the pager fires at 3 in the morning the responder ignores it completely and starts guessing in a terminal instead.