The importance of structured communication in the world of SRE
How you communicate helps build your 9s. In the world of Site Reliability Engineering, this is crucial. How do you do it?


The latest News and Information on Service Reliability Engineering and related technologies.
How you communicate helps build your 9s. In the world of Site Reliability Engineering, this is crucial. How do you do it?
In data management, numerous roles rely on and regularly use observability data. The Site Reliability Engineer is one of these roles. Site Reliability Engineers (SREs) work on the digital frontlines, ensuring performant experiences by using observability data to maintain stability and awareness of software running in various environments across organizations.
As we settle into the time of year when we reflect on what we're thankful for, we tend to focus on important basics such as health, family and friends. But on a professional level, IT operations (ITOps) practitioners are thankful to avoid disastrous outages that can cause confusion, frustration, lost revenue and damaged reputations. The very last thing ITOps, network operations center (NOC) or site reliability engineering (SRE) teams want while eating their turkey and enjoying time with family is to get paged about an outage. These can be extremely costly - $12,913 per minute, in fact, and up to $1.5 million per hour for larger organizations.
Our industry has always had localized expressions for work that was necessary but didn’t move the company forward. The SRE movement calls this type of work “toil.” The concept of toil is a unifying force because it provides an impartial framework for identifying — then containing — the work that takes up our time, blocks people from fulfilling their engineering potential, and doesn’t move the company forward.
We spoke with two members from the SRE team, Alex Blyth and Zulhilmi Zainudin, to learn more about their role at Civo. Through this series, we aim to provide you with an overview of the different roles we have at Civo and what advice our team has. You can discover more about our team in our “day in the life of a Go Dev” and “day in the life of an Intern” blog.
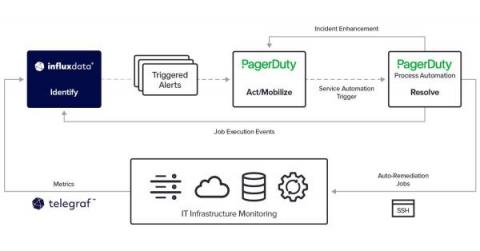
Mean time to resolution (MTTR) is a metric that transcends industry and technology. It’s a measure of how quickly, on average, support teams identify, act, and resolve IT issues and incidents. Because MTTR directly relates to service quality, maintaining a low MTTR is a critical goal for DevOps and SRE teams. These teams have a vested interest in resolving issues quickly because escalating incidents to higher levels of the support team increases response and resolution times.
I’ve had the honor and privilege of authoring The SRE Report for the last three years. For the 2023 version, this included working with some amazing individuals like Anna Jones, Kurt Andersen, and Steve McGhee. Download The SRE Report 2023 here (no registration required).