Operations | Monitoring | ITSM | DevOps | Cloud

IT Offboarding and How to Revoke Access Without Leaving Security Gaps

When someone leaves your organization, how sure are you that every account they could reach was closed? Most IT offboarding starts by disabling the employee's main login account, and that step usually works. The risk comes from the other accounts, tools and devices the person used that the main account does not control. These include personal API tokens, shared vendor portal logins, laptops still with a courier and SaaS tools bought on a department card.
How to Fix Slow DNS Lookups Across Clients, Resolvers and Networks

Why does every page, login and business application hesitate before anything loads, even when bandwidth graphs look healthy? That pause usually comes from name resolution: no connection starts until its hostname has been translated into an IP address, and whatever time that translation takes is added to the request. Slow DNS seldom shows up as a clear error.

Latest Log Management Strategies in 2026: From Raw Logs to Business Value

Discover the latest log management strategies for 2026 and learn how AI and automation turn raw logs into actionable insights. See how modern log management can reduce investigation time, improve incident response, control costs, and strengthen visibility across hybrid and multi-cloud environments.

What is a CRC Error and How to Find the Faulty Link Before It Slows the Business

Why does a switch port look healthy on every dashboard while people on that floor keep reporting dropped calls and slow file transfers? Often the cause is CRC errors, a port counter that most dashboards do not show by default. Each CRC error means a unit of data arrived damaged and the switch discarded it. Put simply, a CRC error tells you the receiving device noticed the data changed somewhere in transit.

ITSM to Deep Observability with ServiceOps & ObserveOps | Motadata Webinar

In this webinar recording, discover how ServiceOps and ObserveOps connect IT service management with deep observability. Learn how IT teams can identify root causes faster with unified visibility across incidents, metrics, logs, traces, applications, and infrastructure. Don't forget to like, share, and subscribe for more insights on ITSM, observability, AIOps, and IT operations.

How to Check Bandwidth Usage Across Your Network

Most bandwidth problems get investigated after the complaints arrive, and by then the traffic that caused them has moved on. The numbers you need sit in several places at once. A laptop knows its own traffic. The router knows what leaves for the internet, and only the switches see how much network bandwidth moves inside the building. Checking bandwidth usage at the right layer saves hours of guessing. Most of the methods ship with hardware you already own.

What Is Shadow IT? Meaning, Risks, and How It Shows Up in Your Asset Inventory

Most shadow IT starts with a marketing team that needed a file-sharing tool on Tuesday. The next procurement cycle was six weeks away. That gap keeps widening. According to Gartner, 75 percent of employees will acquire, modify or create technology outside IT's visibility by 2027, up from 41 percent in 2022. Shadow IT is the name for that tech. IT asset discovery is where it first shows up. In this blog, you will: By the end, you can turn shadow IT into a weekly review queue.

What Is a Network Topology Diagram? Types, Examples and How to Build One That Stays Current

Most network diagrams are accurate exactly once: the day they are finished. The network keeps changing, the drawing does not, and the gap shows up during the next outage. According to the Uptime Institute Annual Outage Analysis 2026, failure to follow established procedures remains the leading driver of human-error outages. A wrong diagram is how a right procedure hits the wrong port. The fix is a network topology diagram that matches the live network topology.

What Is Network Design? Steps and Best Practices for Growing Networks

Most networks were never designed. They were extended, one switch and one VLAN at a time, until a single core failure took the site down and nobody could find the diagram. According to the Uptime Institute Annual Outage Analysis 2026, 57 percent of organizations said their most recent major outage cost more than $100,000. Network design is how you stop paying that bill. You decide the network topology, the addressing and the hardware on purpose, before the cabling goes in.

How to Find and Fix Packet Loss Before It Reaches Your Users

Why do the same complaints about call quality and slow file transfers keep coming back after the network has been checked and declared healthy? Packet loss is usually the answer, and it survives investigation because it degrades the services people use without taking anything offline. That combination makes it expensive. Equipment gets rebooted, cables get replaced, and tickets go to the internet service provider, often with nobody knowing which segment of the path is discarding traffic.

Top 10 Incident Management Tools Compared

An IT incident costs the most in the minutes between the first alert and the first owner. Incident management tools exist to shrink that window. However, choosing the best incident management tools is not as straightforward as we’d like it to be. The 2026 market has its own complications, Opsgenie is going away on April 5, 2027, and Squadcast has been folded into SolarWinds.

How to Troubleshoot VPN Problems and Keep Remote Access Running

Why does the VPN work for most of the company while one branch office, or a handful of remote staff, reports that it won't connect or crawls the moment they sign in? The difficulty with VPN troubleshooting is that the tunnel relies on every layer below it. If the laptop, home Wi-Fi, internet route, gateway, or security policy on either end misbehaves, the connection suffers. One complaint about a slow file share could originate at any of those points.

UPS Monitoring for Data Centers That Cannot Afford an Unplanned Stop

How many minutes of battery runtime are left in the unit protecting your primary rack right now? Most monitoring deployments can answer a question like that for every switch, server and virtual machine in the building. Ask about power and the dashboard goes quiet. Backup power tends to fall between two owners. Facilities buys the hardware and books the service visits, while IT owns everything plugged into it.

Digital Signature vs Electronic Signature and When ITSM Approvals Need Each

Would a single click on Approve in your service desk satisfy an auditor reviewing a high-risk change, a purchase order, or a vendor contract? Often the answer only becomes clear when someone requests a signed copy and the ticket has nothing to show. Much of this traces back to terminology. Many organizations treat electronic signatures, digital signatures, and approvals as interchangeable, and ITSM tools tend to call every sign-off an approval.

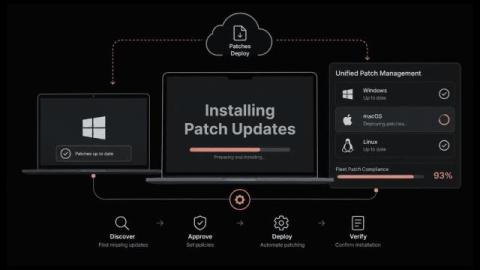
macOS Patch Management for Mixed Windows and Mac Fleets

How many Macs in your environment are running an OS build that your patch compliance report has never counted? In most mixed Windows and Mac deployments, the Windows side is managed by policy and the Mac side is managed by hope. Designers, executives, and engineering leads install updates when a notification interrupts them, and otherwise dismiss the prompt for months.

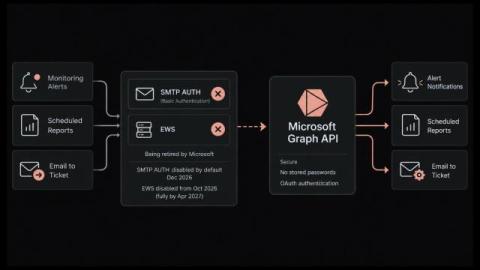
Moving Alert and Email-to-Ticket Mail off SMTP AUTH to Microsoft Graph API

Every monitoring alert, scheduled report, and email to ticket conversion in your stack depends on a mailbox. Most monitoring and helpdesk management tools still reach that mailbox the old way. They log in with a username and password over SMTP or EWS. Exchange Online is closing both doors on a published schedule. The tools that fail will fail silently. In this blog, you will: By the end, you can run the change on a weekday afternoon and know nothing went quiet.

How Traceroute Works and How to Read Its Output During an Outage

Users report that an internal application has gone slow, the server dashboards look normal, and the network group says nothing changed on their side. So where between the user and the application does the time actually go? Much of that answer comes from traceroute. The command lists every router a packet crosses on the way to its destination, with a timing figure set against each one. Arguments about ownership then come down to a single device on a single route.

ISO 20000 Certification: Prerequisites, Process, and Cost

ISO 20000 certification means two different things depending on who is asking. One is an audit of your organization against ISO 20000. The other is an exam that one person sits. Search results mix the two together, and teams lose weeks to it. A service desk manager hunting a company certificate lands on a training catalog. They book a course nobody needed. In this blog, you will: You will finish able to scope the project and brief a certification body.

How to Fix DNS Server Not Responding Errors and Keep Users Online

Has your service desk ever filled with "the internet is down" tickets while every switch, firewall and uplink is reporting normal? The connection is usually fine. What has failed is name resolution, and the message your users see says the DNS server is not responding.

10 Top Network Traffic Analysis Tools for Faster Troubleshooting and Capacity Planning

A request to upgrade a saturated circuit is easy to raise and hard to defend. The interface graph proves the link is full. It says nothing about which application, host or conversation filled it, so the spend gets approved on assumption instead of evidence. The same missing detail turns up everywhere else. Incidents run long because the cause is guessed at, capacity planning rests on estimates, and security questions arrive weeks after the traffic record expired.

ISO 20000 in ITSM: What the Standard Actually Requires From Your Service Desk

Certification against ISO 20000 puts your service desk under audit. That audit runs on what your team wrote down at the time. The standard does not care how your team describes its process. It does not care which ITIL 4 practices you adopted. It cares what your records show, so auditors spend their time in your tickets, approvals, and review minutes. In this blog, you will: You will finish knowing which of your records would survive an audit.

9 Best Log Management Tools and What They Cost

Most log management tools bill you on log ingestion, the volume of data you send them. That works until your log volume doubles, and the invoice doubles with it. The best log management tools let you control what gets indexed and kept, so growth stops being a budget problem. In this blog, you will see: By the end you will know which fits your volume. Log management is the full lifecycle of your log data, from the moment it is collected to the moment it is deleted.

MSP Ticketing System: How to Evaluate and Choose the Right Platform

Most managed service providers do not replace their ticketing tool because ticket volume got too high. They replace it because a client asked for a report the tool could not produce. That moment usually arrives between the third and tenth client. The shared inbox and the general help desk that carried you this far stop holding the accounts apart. Per-client reporting is usually the first thing to give way. An MSP ticketing system takes support requests from every client you serve.

The Essential Eight: Patching Applications and Operating Systems at Maturity Level Two

Why do so many patching programs pass every internal check and still come back from an Essential Eight assessment rated at Maturity Level One? The answer is rarely speed. Teams that miss the mark are usually patching their servers, browsers, and office suites on schedule, then losing the rating on the fifty applications nobody put on a list. Maturity Level Two is where the Essential Eight stops asking how fast you patch and starts asking how much you can see.

PCI DSS Requirement 10: Logging and Monitoring in v4.0.1

Version 4.0 renumbered PCI DSS Requirement 10 from end to end, and the Council retired v3.2.1 on 31 March 2024. Sub-requirement numbers written before then mostly point somewhere else now. Four more Requirement 10 rules changed status on 31 March 2025, automated log review among them. Checking your numbering against v4.0.1 costs an afternoon and saves a finding. In this blog, you will: PCI DSS Requirement 10 covers audit logging and monitoring across the cardholder data environment.

IT Service Management for Government and Public Sector Organizations

What happens when a citizen-facing portal fails on the last day of a filing deadline, and the only record of the outage lives in an email thread between two engineers? In a commercial organization, that is an operational embarrassment. In a government department, it is a hole in a statutory record that an auditor will eventually ask about.

ITSM for Healthcare: IT Service Management in Hospitals and Health Systems

How long does a nurse stand at a workstation waiting for a record to load before the ward gives up and reaches for paper? In most hospitals nobody measures that number, and the ticket that reaches IT describes a symptom instead of a cause. Hospital IT support runs on a different clock from corporate IT. There is no quiet Sunday night and no safe window for maintenance.

Log Filtering: How to Cut Log Ingest Volume Without Losing Evidence

Every log estate reaches a point where volume grows faster than the value inside it. The usual response is to find the biggest source and drop it. Cutting volume is the easy part. Cutting the right half takes judgment. Log filtering is only one of four options for an expensive source, and the other three matter just as much. In this blog, you will: By the end you can defend every rule you write, including the ones that keep data. A volume cut fails in two directions.

Agent vs Agentless Monitoring and How to Decide What Goes Where

Why does half the infrastructure end up returning no monitoring data? The standard plan is to install collection software on everything, which moves quickly across servers and stops dead at the first device running closed firmware. Storage arrays, firewalls, and switches will never accept an install, and the rollout stalls there. That plan usually gets set once for the whole environment, with a single collection model applied to hardware it was never suited for.

Help Desk Software for Schools: Managing IT Support Across Campuses

How many support requests reach school IT staff each week without ever becoming a ticket? A teacher stops a technician in the corridor about a projector that will not connect. An office administrator sends a direct email about a locked account, and a student tells the librarian their laptop stopped charging during second period. Help desk software for schools collects those requests into one queue, routes them by site and category, and keeps a record of what was done.

10 Top Website Monitoring Tools for Uptime, Page Speed and Real User Data

Your uptime tool reports the site as available all month. Support reports something else, because customers in one region spent the morning unable to complete a checkout. Both records are accurate, and that is the problem. An external check confirms the page answered. It cannot tell you that the answer took nine seconds for everyone routed through one CDN edge, or what caused the delay.

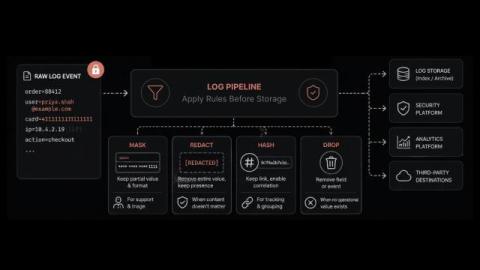
PII Redaction in Logs: Mask, Redact, Hash, or Drop?

Sensitive values reach your logs without anyone deciding they should. A debug line prints a whole request object. An error message carries the query string. A customer email address is suddenly stored in three systems. PII redaction in logs then gets treated as one setting to switch on. In practice it covers four separate treatments. The value is already inside the message before log ingestion finishes. In this blog, you will: By the end you can write a rule for each field and defend it.

Log Processing: What Happens to a Log Line Before You Can Search It

A log line arrives as plain text and leaves as a record you can query. Six steps sit between those two states. Each one adds something useful, and each one costs you time, CPU, or storage. Most teams never look at that chain until a search comes back empty. Here is what log processing does to an event, step by step: By the end you can look at your own chain. You will know what each step buys you. Six steps turn a raw log line into a searchable record.

How NIST Compliance Turns Observability Data Into Audit Evidence

Can you prove, on demand, which production systems were under continuous monitoring last quarter? Buyers, auditors, and insurers all ask a version of that question, and the answer decides contracts as often as audit findings. NIST compliance means aligning security controls and operations with standards from the National Institute of Standards and Technology, then holding evidence that the alignment stayed continuous. The frameworks are precise about outcomes and quiet about mechanics.

Best Storage Monitoring Software: 10 Tools Compared

Storage rarely fails loudly. A pool fills. Latency climbs on one LUN. The first to notice is a user whose application timed out. The best storage monitoring software catches it earlier. It watches capacity, IOPS, latency and drive health across your arrays, which is what storage resource monitoring is for. In this blog, you will see: By the end you will know which one fits. Storage monitoring software tracks the health, capacity and performance of your IT storage.