Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Cloud monitoring, security and related technologies.

Railway vs Render vs Your Own Cloud Account: What Actually Fits a Scaleup Outgrowing Managed PaaS

An honest 2026 comparison of Railway, Render, Fly.io and deploying into your own AWS, GCP, Azure or Scaleway account - with the six measurable signals you have outgrown managed PaaS, a priced cost model, and a four-step framework with if-then verdicts. Romaric founded Qovery to make Kubernetes accessible to every engineering team. He writes about platform strategy, developer experience, and the future of cloud infrastructure.
Our Customer Success AI bill tripled. Here's why we're spending more.

Pop quiz: If you spend $40,000 per month on Anthropic, and you’ve got two customers, what’s your cost per customer? If you bypassed the easy answer of $20,000 and said, “Scott, you old trickster, that’s not enough information to answer that question,” you’ve won today’s prize: a lesson in the perils of average costs. Let’s flesh out the situation: You put an AI feature in your product, a document assistant powered by Claude.

Shipped: Rightsize Kubernetes workloads without leaving your MCP client

Changing a Kubernetes resource request takes two numbers: what the workload requests, and what it uses. The CloudZero MCP server now returns both, by cluster, namespace, or workload. This gives you a number you can defend. Usage comes back as P95 over the date range you query, 30 days by default. When an engineering lead asks whether a service runs on a smaller request, that is the figure that settles it. Over-provisioning and under-provisioning show up on the same query.

LLM token cost: pricing per token explained

LLM token cost is the price a provider charges per token a model reads or writes, quoted in dollars per million tokens. Input and output bill at separate rates, with output priced at roughly 5x input. As of September 2026, published rates range from under $0.10 to more than $180 per million tokens on top-end reasoning tiers. In late 2025, Hardik Sonetta of Thomson Reuters Labs published a warning about the most common prompt caching mistake in production.

Why compliance keeps slowing your releases (and what to change first)

A team ships at a steady pace for most of the year. Then an audit approaches, and delivery slows. Engineers get pulled off feature work to support the audit, producing the configuration exports, logs, and environment checks that the evidence depends on. The slowdown lasts as long as the audit does. It is tempting to read this as a team that needs to move faster or be bigger. It is usually neither.

Cloud Cost Management for Observability: A Practical Guide

Observability spend is outgrowing infrastructure budgets. What drives the cost up, how pricing models work, and a practical framework to manage it. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

Moving Beyond OOM Kills: Introducing Memory QoS in Kubernetes 1.37

Table of Contents For most of Kubernetes’ history, memory management has been a blunt instrument. Cross your limit, and the kernel kills your container. There has been no equivalent to CPU throttling, no graceful backpressure, just a hard stop. With Kubernetes 1.37, that changes: Memory QoS, built on cgroups v2, graduates to Beta and is enabled by default.

For whoever has to explain the cloud bill to finance every month.

As infrastructure gets more complex, with workloads spread across clouds, regions, and providers, every hop your data takes between them adds up. Where do these costs actually come from? Has your team ever traced a surprise bill back to data movement? With Megaport, cloud egress costs are minimized by routing data privately between providers, avoiding the higher transfer rates associated with public internet routing.

SaaS Sprawl Is Becoming an IT Problem: Here's How to Bring It Under Control

For most organizations, SaaS sprawl does not begin with a bad technology decision. It starts with a useful tool. Marketing needs a new analytics platform. Sales adopts prospecting software. HR adds an applicant tracking system. Engineering signs up for another monitoring service. Someone discovers an AI tool that saves several hours a week and puts it on a company card. Each purchase makes sense on its own.

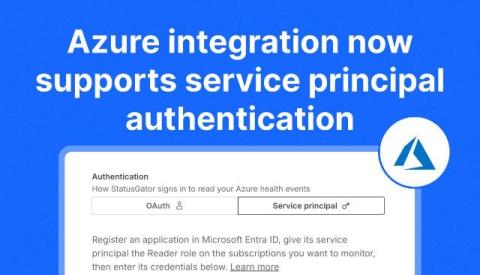
Azure integration now supports service principal authentication

We’ve released some improvements to our Azure status integration. StatusGator can now read your Azure Resource Health events via a service principal. Previously the only supported authentication mechanism was OAuth. Both pull the same data and produce the same alerts – the difference is who the connection belongs to, and what happens to it over time.