Operations | Monitoring | ITSM | DevOps | Cloud

Designing Safe Traffic Flows for On-Premise Data Centers

On-premise data centers handle massive amounts of hardware and infrastructure. Managing the physical layout requires serious attention to movement and safety. Heavy servers, delivery crates, and technical teams move through these spaces daily. Creating a smooth flow minimizes accidents and protects valuable digital assets. Clear pathways make daily operations predictable and safe for everyone on site.
Structured Information Architecture and Communication Logic in Corporate Websites

Corporate websites function as essential platforms for organizations to establish credibility and convey their core identity. Unlike transactional spaces, they prioritize the delivery of structured information that supports informed decision-making by stakeholders, including investors, partners, and industry professionals. Their mission centers on building lasting trust through information clarity, presenting complex organizational details in an accessible and logical manner that reflects stability and transparency.

Build WireMock mappings fast from real traffic

I’m a big fan of service mocking. I’ve been working in and around software for about 25 years, and one thing never changes: when you sit down to work on your code, you almost never have everything available. The database, the third-party API, the message queue, the service two teams over. Something’s missing. So you’ve got to stub it out or mock it out and keep moving.

Introducing the New Galileo Website: A Better Resource for IT Visibility, Optimization, and Planning

That's why we've launched a completely redesigned Galileo website. The new site isn't just a fresh look but rather a reflection of our commitment to helping IT teams gain the visibility, insight, and guidance they need to manage modern infrastructure more effectively.

5 Alternatives to Prometheus in 2026

Prometheus is a battle-tested, flexible and, most importantly, free tool that has long been the go-to open-source monitoring solution. Much of its popularity came down to its simplicity. A few years have gone by, though, and the APM space has gotten pretty crowded. Developers are now starting to move away from the complexity of self-hosting, and OpenTelemetry stands out as one of the CNCF’s fastest-expanding projects. In fact, it’s now among the most adopted telemetry frameworks out there.

Cloud Storage vs Local Storage: Everything You Need to Know

In 2026, the world is expected to generate roughly 450 to 500+ million terabytes of data per day due to continued rapid growth in: All this data needs to be stored somewhere, but is cloud storage or local storage best to manage your data? Throughout this article, we will cover This way, you will gain a deeper understanding of both storage models and determine which best suits your personal, business, or enterprise use case.

Troubleshooting ActiveMQ Producer Flow Control Blocks

The alert comes in at 2 AM: your order processing service is unresponsive. The application is not crashed, threads are running, the JVM is healthy, but no messages are being sent. Your operations team traces it to a blocked send() call on an ActiveMQ connection. Hours later, after restarting the application, someone finds this line in the broker log from 11 PM the previous day.

The Second Edition of Observability Engineering Is Here

IT’S HERE it’s here it’s here it’s here!!!! The second edition of Observability Engineering is available for download, and since Honeycomb is the sponsor, you can now download it from our website (the dead tree version will take another month). This is a strange time to be writing a book.

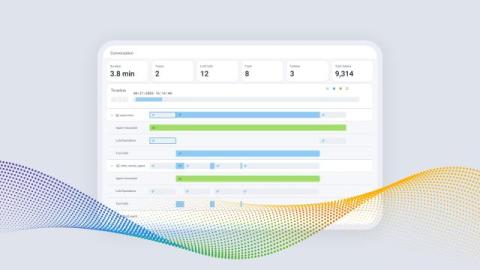
Agent Timeline Is Now Generally Available

A few weeks ago I wrote about a customer’s refund request that stopped halfway through at 11:47 p.m. on a Tuesday night. That post walked through the 40 minutes it took to work out what happened when an agentic application had a problem: a tool retried against a rate-limited payments API, the error responses filled up the context window, and the agent gave up. The whole reason we built Agent Timeline was to turn that 40 minutes into five. To reduce MTTR. To solve the problem and get back to sleep.

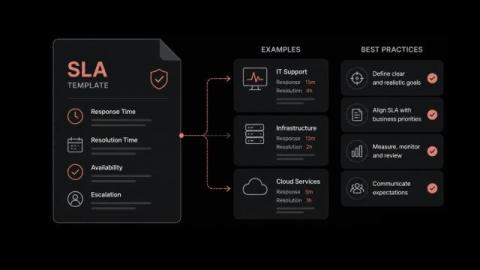
Service Level Agreement (SLA) Templates: Examples, Metrics, and Best Practices

How quickly should your team resolve a critical ticket, and what are the consequences when it misses the target? That is exactly where Service Level Agreements (SLAs) come into play. An SLA turns service expectations into measurable commitments by defining clear response and resolution targets. Rather than starting from scratch, an SLA template provides a structured foundation for establishing those commitments and tracking performance against agreed standards. Why does that matter?