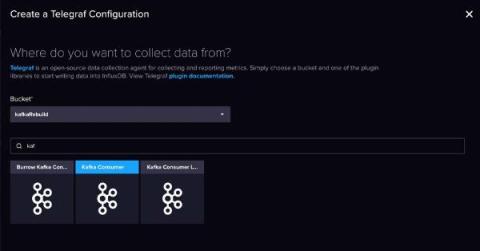
InfluxDB and Kafka aren’t competitors – they’re complimentary. Streaming data, and more specifically time series data, travels in high volumes and velocities. Adding InfluxDB to your Kafka cluster provides specialized handling for your time series data. This specialized handling includes real-time queries and analytics, and integration with cutting edge machine learning and artificial intelligence technologies. Companies like as Hulu paired their InfluxDB instances with Kafka.
The challenge for every organization is gathering actionable observability information from all your systems, in a timely manner, without creating a substantial operational burden for the teams managing the collection tooling. While each observability solution has its unique benefits and challenges, the one common burden expressed by teams is the management of the metadata of the metrics, traces, and logs.
Data growth has significantly out-pacing budgets; the products we use, have to do more. This is where optimization comes into play. Generally, optimization is associated with reduction which may be intimidating…what if something important is reduced? How can you identify what should be reduced? Reduction isn’t about removing context, but about removing repetitive data, meaningless fields, or even flattening JSON.