Operations | Monitoring | ITSM | DevOps | Cloud

Datadog named a Leader in the Forrester Wave: AIOps Platforms, Q4 2026

Datadog has been named a Leader in The Forrester Wave: AIOps Platforms, Q4 2026. We believe this placement reflects Datadog’s commitment to transforming observability into autonomous operations with a single integrated platform where AI agents detect, investigate, and remediate production issues, while engineers stay in control. Close dialog.
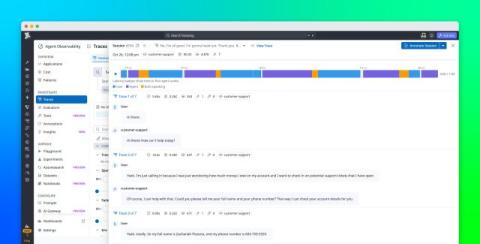
Trace voice agents with Datadog Agent Observability

A voice agent can return the right words and still deliver a poor experience. It might leave a caller in silence, speak over them, or stop midway through a response. A transcript may look correct even when the audio the user heard was delayed, incomplete, or different from the text on screen. These problems are difficult to diagnose from text traces alone. Voice conversations also involve more than a single request and response.

Default to serverless for AI agents, then let production data decide what moves

Serverless should be the first execution model teams evaluate for AI agent workloads. Many agents spend much of their lifetime waiting, and always-on compute forces teams to pay for every idle minute. In a study of more than 35,000 production coding-agent sessions, the median session ran LLM or tool calls for only 20% of its lifetime. The rest of the time, it sat idle between steps, with its sandbox still allocated.

Match monitoring depth to workload needs with Infrastructure Basic

A back-office server that runs out of disk space can interrupt an important internal workflow. A process that stops on a staging host can delay development. Although workloads like these might not require application-level instrumentation, teams still need to know when the hosts that support them require attention. Without a monitoring solution tailored to these requirements, teams have to apply more monitoring than the workload needs, maintain a separate tool, or accept a gap in visibility.

Measuring What Matters in AI Applications

AI has become incredibly sophisticated and changed the way we build and power applications. But it has also introduced volatile complexity that challenges how we ensure reliability and protect user experiences. Join our panel of experts as they discuss the realities of building AI-powered applications. They’ll talk about how testing has evolved, share insights into how they do evals and experiments, and offer advice on how to get better visibility into how your AI is performing.

The Deconstructed Database at Datadog

As Datadog scaled to handle over a hundred trillion daily events, our engineering teams built their own custom query engines to keep things fast. While this helped teams move quickly, it also created silos that made it tough to analyze data across different products. To keep growing and support AI, we had to find a way to bring these engines together using open standards without slowing anyone down or risking reliability.

Best practices for scaling A/B testing with experiment protocols

Running one A/B test well is manageable. Scaling A/B testing to hundreds of experiments across dozens of teams is harder, because teams may make different decisions about metrics, randomization, rollout, and analysis. Experiment protocols in Datadog Experiments turn an approved methodology into a reusable configuration, giving experiments of the same type a consistent starting point. In this post, you’ll learn how to.

Monitor Oracle AI Database across clouds with Datadog

Organizations can use Oracle AI Database@AWS, Oracle AI Database@Azure, and Oracle AI Database@Google Cloud to run Oracle databases co-located with the cloud applications they support rather than managing the databases on premises. However, running applications in a cloud provider’s environment while hosting databases on Oracle Cloud Infrastructure (OCI) can lead to visibility gaps. When application performance degrades, identifying the source of the problem can be difficult.

Optimize AI costs with Agent Observability

AI agent costs accumulate along more dimensions than a model-call count. Spend is a product of both which models you call and how the agent is architected: how many turns the loop runs, how many tools it invokes, how much retrieved context it carries, and how much of that context is re-sent on every turn. Provider bills tell you how much you spent, but they’re keyed to API keys and models instead of the applications and workflow steps that generated the calls.