Operations | Monitoring | ITSM | DevOps | Cloud

How AI agents help teams deliver better digital experiences

The moment your page slows down, two clocks start. One is yours: time to alert, time to investigate, time to fix. The other belongs to the user staring at the slow page. Yours is measured in minutes. Theirs runs out in seconds. That gap is what AI agents close. Zia Agents in OpManager Nexus detects an issue, works out the cause, and runs the fix on its own, often before your users feel a thing. This blog looks at how that changes the experience you deliver.
Top Tips: Staying productive during a slow work week

Top tips is a weekly column where we highlight what’s trending in the tech world and share ways to stay ahead. This week, we’re looking at what you can when you’re having a slow-paced, less hectic workweek. We’ve all been there at intermittent intervals of our jobs: You check into the office right after the weekend only to realize you’re having one of those slow, relatively low-pressure weeks. So what do you do to stay productive?

Generative AI in Banking: Balancing innovation, risk, and operational readiness

Generative AI (GenAI) is moving quickly into banking. According to a 2025 survey by McKinsey, 52% of financial institutions surveyed already consider GenAI a priority, while another 39% are interested but have not yet made it a top priority. As adoption grows, banks need to think carefully about what AI agents can access, which identities it uses, what actions it can take, and whether those activities can be traced when something goes wrong.

Azure Monitor pricing: What you pay vs. what you get

Azure Monitor doesn't have a price. It has a bill and those are very different. There's no plan tier to pick, monthly set fee, or simple number to sanity-check against your budget. Instead, you're charged across a handful of separate meters: log ingestion, log queries, retention, alert rules, web tests, and custom metrics. Each of these metrics scale independently. Most teams don't see the full cost until the bill arrives.

Why Is GPU Utilization Low During AI Training? 6 Bottlenecks to Check

You bought the GPUs to make AI training faster. So why are they sitting idle? When GPU utilization drops during a training run, the obvious answer is to blame the accelerator. Maybe the workload is too small. Maybe the GPU isn't powerful enough. Maybe it's time to add more hardware. But what if the GPU isn't the problem at all? A training workload is only as fast as the infrastructure feeding it.

Autonomous IT operations: Scaling business without scaling IT complexity

Autonomous IT operations use AI, operational data, observability, and automation to enable IT environments to detect issues, understand their context, determine the appropriate response, and act with minimal human intervention. As businesses grow, IT environments rarely stay simple. More employees, endpoints, applications, and cloud services generate even more alerts, incidents, and operational work. The traditional model scales linearly: more environment means more manual effort.
Sponsored Post

How to cut AI infrastructure spending without reducing GPU capacity

Every infrastructure leader running AI workloads is staring at the same problem: GPU spending keeps climbing, the finance team wants a justification, and the operations team is caught between proving the infrastructure is necessary and explaining why the returns aren't keeping pace with the investment. The instinctive response is to either procure more capacity to handle growing demand or cut back on what's already deployed. Neither actually solves the problem.

Best Kubernetes monitoring tools compared in 2026: A buyer's guide for SRE, platform engineering, and ITOps teams

Monitoring Kubernetes in production is structurally different from monitoring traditional servers: pods are ephemeral, nodes autoscale, and the layered resource model—containers, pods, nodes, namespaces, deployments, services—creates an observability challenge that tools built for static infrastructure were never designed to handle.

The human we find in our machines

There is a peculiar moment that happens when talking to AI. You ask it to rewrite an email, it does a good job, and you type, "Thanks!" Then, almost without thinking, you add, "Sorry, one more thing." It is software. It cannot be kept waiting, interrupted, or offended. Still, somehow, you have developed the manners. Then the questions get a little more personal.

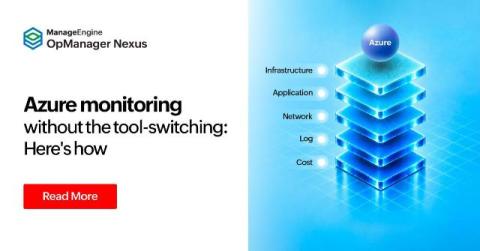
Fragmented Azure visibility? One Azure monitoring tool that tracks every layer

Most Azure monitoring setups look the same: Azure Monitor for metrics, Application Insights for apps, Log Analytics for logs, a separate tool for network, and another for cost. Each works in isolation. None of them talk to each other when something breaks. The Azure monitoring tool in ManageEngine OpManager Nexus consolidates infrastructure, application, network, log, and cost visibility data into a single console.