Operations | Monitoring | ITSM | DevOps | Cloud

8 Best AI SRE Tools in 2026 for Incident Investigation and Reliability

The best AI SRE tools to evaluate in 2026 include Sherlocks AI, Resolve AI, Traversal, Cleric, Rootly AI SRE, Komodor Klaudia, Datadog Bits Investigation, and Dynatrace Intelligence. Each addresses a different part of reliability work, from investigating alerts across multiple systems to diagnosing Kubernetes failures or validating production changes. Choosing the right tool starts with a practical question: where does your team lose time during an incident?
How a Solutions Architect Brought Multi-Cloud Migration to OpenSearch | Tony Piazza

Aiven Senior Solutions Architect Tony Piazza joined the company in March. Within months he had merged five PRs adding Google Cloud support and Terraform-based provisioning to the OpenSearch Migration Assistant, a tool that previously only worked on AWS. Tony talks with Jay Miller about: Why he went from consulting to open source contribution. How a consultant’s habit of finding project risks early shaped the work. His first conference keynote at OpenSearchCon. What contributing as a vendor-neutral company looks like. Where he’s contributing next, including ML Commons, Data Prepper and the docs.

Unify data across Datadog BYOC with cross-cluster queries for teams and AI agents

Organizations may need to keep data in specific regions or infrastructure they control, whether because of data residency requirements, internal policies, or transfer costs. Datadog Bring Your Own Cloud (BYOC) extends the Datadog platform into those environments. Each BYOC deployment runs as a Kubernetes cluster with its own object storage, keeping data close to its source.

Building Reliable IT Infrastructures

Downtime is expensive, and it’s getting harder to avoid. Every year, enterprise IT environments grow more distributed, dynamic, and difficult to maintain with legacy tools and manual processes. With unplanned outages costing enterprises nearly $25,000 per minute, establishing and maintaining a resilient IT infrastructure is essential. Enterprises have already invested heavily in resilient architecture.

What Is High Availability? How It Works and How Many Nines You Actually Need

High availability (HA) is a system’s ability to keep serving users when individual components fail, from a single server up to a whole cloud region or provider. It is measured in nines: 99.9% allows about 8 hours 46 minutes of downtime a year, 99.99% about 52 minutes, and 99.999% about 5 minutes 15 seconds. HA works by removing single points of failure through redundancy, health checks, automatic failover, and replicated data.

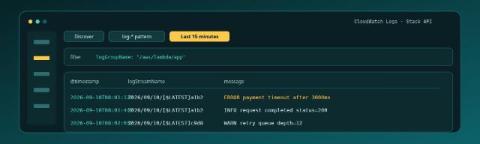
First CloudWatch Logs on Logit.io

CloudWatch already holds the lines from your Lambda, ECS task, or unified agent. The first useful win on Logit.io is not a migration spreadsheet. It is one Log Group, the documented Lambda shipper posting to this stack's API, and rows in OpenSearch Dashboards Discover that show logGroupName, logStreamName, and message. If you are still proving that a Logs stack can accept anything at all, start with First Logs on Logit.io; this post assumes CloudWatch is the source and the Stack API is the pipe. Contents.

How to Integrate NinjaOne with a SIEM

In this episode of NinjaOne01, Jeff Hunter, Field CTO at NinjaOne, walks through NinjaOne’s new SIEM Exporter App. The app is a dedicated place to set up and monitor the webhooks that send NinjaOne activity data to your third-party SIEM (Security Information & Event Management) system. Note: this is an early access feature, so contact your account manager to have it enabled for your account. What this video covers.

Why AI SRE Agents Need More Than Observability Data with Groundcover | Civo Navigate London

Your AI agent can read every log, metric and trace in seconds. It still can't tell you why things broke. At Civo Navigate London, James Herbert of groundcover explains why AI SRE agents need that context to travel the whole development lifecycle. He shows how agents embedded in the tools where software is built and run can move from isolated tasks to investigating and acting with the full picture.