Operations | Monitoring | ITSM | DevOps | Cloud

Agents Need Context: Introducing Canvas Connectors, Fleet-wide AI Agent Visibility, and More

Earlier this year, we introduced more capabilities to support agents in production, a more chaotic, complex environment that requires a tremendous amount of context to understand. Unlike tools that capture shallow, pre-aggregated metrics, or cannot join a metric, trace, and log in one query, Honeycomb retains the context and connective tissue from telemetry data to build a nuanced view of production.
Introducing AI Ecosystem: Zoom Out to See Your Whole AI Agent Fleet

A few months ago, we launched Agent Timeline to close the gap between knowing an agent failed and understanding why. It took the tangled reality of a multi-agent, multi-trace workflow and rendered it as a single, readable conversation: every LLM call, tool invocation, handoff, and downstream system span laid out in the order they happened.

Cribl On Your Coffee Break Episode 20 - Keep learning, keep growing, keep Cribl-ing!

As we wrap up our month-long series, we look at the resources that will help you keep learning and growing - from Cribl University to Sandboxes to the Cribl Community and beyond. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Cribl On Your Coffee Break Episode 19 - A Cribl Grab bag: Guard, API/SDK, Insights, and FinOps

In our penultimate episode of the series we try to hit all the things that didn’t fit anywhere else - Cribl Guard, the API/SDK, Insights, and the FinOps center. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

ITSM to Deep Observability with ServiceOps & ObserveOps | Motadata Webinar

In this webinar recording, discover how ServiceOps and ObserveOps connect IT service management with deep observability. Learn how IT teams can identify root causes faster with unified visibility across incidents, metrics, logs, traces, applications, and infrastructure. Don't forget to like, share, and subscribe for more insights on ITSM, observability, AIOps, and IT operations.

Correlating Business and IT Events: The Path to Business Process Observability

At 9:40 on a Tuesday morning, an order sits unconfirmed in the fulfillment process. Two systems away, a queue depth ticks upward in the integration layer. Both events are recorded. Neither is connected to the other, so nobody escalates nothing is technically down. By 2 PM, order confirmations have stalled across a region. The CFO is asking why the daily revenue number looks soft. Customer service is fielding calls.

Cribl On Your Coffee Break Episode 18 - All About AI

With 3 more days to go, we’ve finally arrived at the AI episode in the Cribl on your coffee break series. Today we’ll touch on a few of the many ways we’ve enabled Cribl to use AI, and also to help you manage the data generated by AI-enabled tools. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...
Sponsored Post

Synthetic Monitoring Is Broken. Your Production Traffic Can Fix It.

Synthetic monitoring has been a critical part of application reliability for years. It gives engineering and operations teams a way to proactively test applications, APIs, and critical customer journeys before users encounter problems. But there is a fundamental limitation with the traditional approach: Someone has to create the tests. As applications become more distributed and customer journeys become more complex, organizations can end up maintaining hundreds or even thousands of synthetic scripts. Every new feature, API, dependency, or change to a customer journey can require another update.

Cribl On Your Coffee Break Episode 17 - Notebooks

Whether you call them runbooks, response guides, or just notebooks, today on Cribl on your coffee break, we are looking at Cribl’s implementation, which lets you document your notes, queries, and discoveries as you make them, and then re-run those same processes later to troubleshoot similar issues in the future with less toil. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

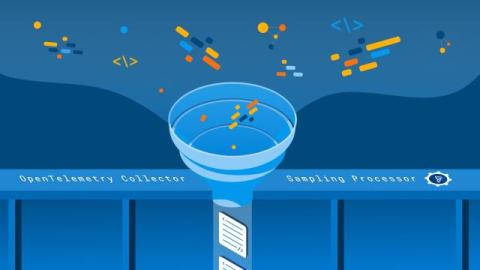
How Adaptive Tail Sampling Works in the OpenTelemetry Collector

You're producing more trace data than you want to pay to store, so you sample. A fixed 1-in-100 rate cuts your bill, but it's blind. It keeps 1% of your errors, 1% of the requests to that rarely-hit route, and 1% of the health checks, all at the same rate. The noisy traffic you care about least dominates what you keep while the traces you need during an incident are the ones most likely to be gone.

Cribl On Your Coffee Break Episode 16 - Dashboards

Welcome to the final week of Cribl on your coffee break, the series to help you get started with the Cribl platform. Today we’re going to cover the last of the "essential skills” in the Cribl platform: using and building dashboards. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Cribl On Your Coffee Break Episode 15 - Routes, part 4 and Cribl Packs

Welcome to the end of week 3 of series to help you get started with the Cribl platform. We’re still talking about routing, but through the lens of Cribl Packs, a way of supercharging your path to getting your data in and through Cribl. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

Cribl On Your Coffee Break Episode 14 - Routes, part 3: One-to-Many

Welcome to the 14th installment in our series to help you get started with the Cribl platform. Here, we continue our conversation about Cribl routes and routing techniques By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

SAP Observability Tools Compared

Comparisons of SAP observability tools often evaluate which platforms can see inside SAP.Today, that’s nearly all of them. Dynatrace, Datadog, New Relic and Splunk can all get SAP telemetry. None of them are likely the best choice for an SAP-centric application, and we will document why. The questions teams evaluating SAP observability solutions should consider: That last one is where most of these platforms stop, and it is the difference between observability and operations.

Cribl On Your Coffee Break Episode 13 - Routes, part 2: Many-to-one

Leon is back from the BlackHat conference and it shows (or at least it SOUNDS like it). Despite a little bit of laryngitis, today he’s continuing the exploration of routing by focusing on taking multiple sources of data and using routes to send them to a particular destination. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

How backend functions extend Cribl Apps: Scheduling, local testing, and logs

See how backend functions extend Cribl Apps with live data retrieval, scheduled jobs, local testing, deployment validation, and logging. In this walkthrough, Giovanni Mola shows developers how to connect app data sources such as Jira and news feeds, manage schedules, preview functions locally, verify a live deployment, and inspect emitted logs in Cribl Search.

Datadog named the Company to Beat for observability platforms in 2026 Gartner AI Vendor Race report

Datadog has been named the Company to Beat for observability platforms in the August 2026 Gartner AI Vendor Race research. Datadog has also been named a Leader in the 2026 Gartner Magic Quadrant for Observability Platforms for the sixth consecutive year. We believe that these recognitions reflect what we have been building toward for more than a decade: a single platform where teams can observe, secure, and act on everything that matters across their technology stack.

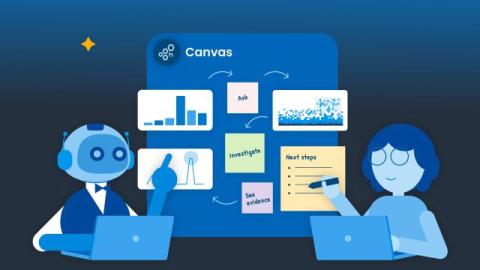
How Canvas Powers the AI Agent Development Feedback Loop

For teams building AI agents, the feedback loop should already be a familiar idea: watch how the agent behaves, find what needs improvement, ship a change, and measure the result. In theory, each turn builds on the last until the loop becomes a flywheel and your agent is getting more effective with each turn. In practice, many of us are still in reaction mode. A user reports something strange, costs spike, or an eval score drops.

Five Ways to Use OpenTelemetry Beyond Observability

OpenTelemetry graduated from the CNCF in May 2026 as, in the foundation’s own words, the de facto observability standard. The JavaScript API package alone did 1.36 billion downloads in twelve months. That kind of win has a side effect nobody plans for. Once a wire format is everywhere, has a receiver for every source, a transform language, and an agent your platform team already operates, people start putting things on it that have nothing to do with knowing whether a service is healthy.

AI Norms & Values, Part 3 of 3: Things We Hold True

Welcome to the third and final part of our series on AI norms and values. Parts of this doc were extracted and published separately on substack; as a whole, they describe the principles we hold pertaining to technology and AI, and the ethical commitments we make to each other and our customers. We set out to write about AI, and ended up writing about ourselves. These documents are not meant to be aspirational ones; they are derived from how we do our work every day in honeycomb.

Wide Events vs. Three Pillars: AI Observability Costs

As agentic AI workflows gain traction within organizations, those organizations are asking how to account for their behavior while keeping costs manageable. Some are sticking with the old three pillars of observability approach: take a measurement to create a metric, record output to a log, and track serial progress with a trace. Each of these is useful, but treating them as distinct formats from the start means paying for them distinctly too. Separate storage doesn't come cheap.

How Observability and Real-Time Data Can Improve Warehouse Operations

Warehouse operations generate a constant stream of information. Goods are received, inventory moves between locations, orders enter picking workflows, stock levels change, and shipments leave the facility. When these activities are managed through disconnected systems or delayed manual updates, managers can struggle to understand what is actually happening on the warehouse floor.

Relational Query Superpowers

I'm investigating repeated errors in my e-commerce application, and I need to get enough context in a single Honeycomb query to piece the entire picture together. Each query returns events based on the event's WHERE clauses, but I want to know several things from outside of the event that recorded an error. Things like: Those attributes are all over the trace. That's going to make a single query tough, right? Wrong!

Live Debugging for Critical Systems: MTBF, MTTR & MTTA

A critical system has to stay reliable without new failures or added downtime, and live debugging, confirming the root cause without stopping the system, is often the only way to do that. In practice, this means having runtime context: on-demand evidence generated at the point of failure rather than logging configured months earlier, which is what keeps MTBF up, MTTR, and MTTA down.

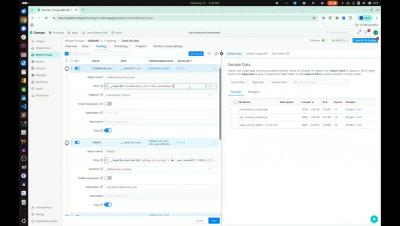
Cribl On Your Coffee Break Episode 4 - Gathering REST data

In the 4th installment of our series, Leon looks at Cribl’s ability to collect REST API data. By the time the month (and the series) is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed your body weight in caffeinated beverages...

Cribl On Your Coffee Break Episode 3 - Configuring Prometheus Remote-Write

In day 3 of our coffee break series, Leon continues to explore common observability data types and how to get them into Cribl. Today, we’ll look at setting up a simple Prometheus ingestion. By the time the month (and the series) is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed your body weight in caffeinated beverages...

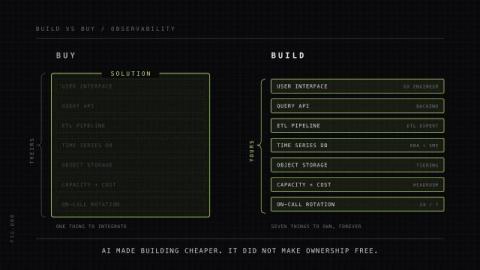
Why you should (not) build your own observability stack

If you are able to build it better than your vendor, then change your vendor. Not build it. Rishi builds large-scale observability systems at Last9, focusing on reliable and cost-efficient telemetry infrastructure, and writes about the practical lessons learned while operating ClickHouse, VictoriaMetrics, and OpenTelemetry in production.

Cloud Cost Management for Observability: A Practical Guide

Observability spend is outgrowing infrastructure budgets. What drives the cost up, how pricing models work, and a practical framework to manage it. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

Bringing the Most Advanced Sampling to the OpenTelemetry Collector

Sampling is a core skill that everyone who runs an observability pipeline at scale will learn. There are lots of tradeoffs within the various decisions you'll make from reducing bandwidth, CPU, and memory, to reducing costs and making the observability backend's performance better for users. Historically, there have only been three mechanisms, each with their own tradeoffs: However, there is a secret fourth option: adaptive tail sampling—which changes those tradeoffs.

Cribl On Your Coffee Break Episode 2 - Setting up Syslog

In our second video Leon picks on Syslog (because honestly, it deserves it). Cribl is the perfect tool to whip that disorganized, loud, unruly mess of a data stream into shape. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...