Operations | Monitoring | ITSM | DevOps | Cloud

Cloud Monitoring and Incident Response: A Guide to AWS, Azure, and Google Cloud

Effective cloud monitoring and incident response starts with understanding service health, collecting useful diagnostic data, and establishing a clear process for investigating and resolving problems. Whether you use AWS, Azure, Google Cloud, or several providers, the goal is to understand how your systems are performing and take action when reliability is at risk. A dashboard showing healthy virtual machines does not necessarily mean customers can complete a transaction.
Democratizing Incident Response with AI at Riot Games - SRE Track

Senior engineers are the pillars of SRE programs—not only do they have the leadership to manage incidents well, they also have the tribal knowledge to understand the technical causes of tricky issues. But when the know-how is confined to a few individuals, it greatly limits the effectiveness of your SRE team.

Accelerating Resolution with Autonomous Incident Response v1

Incident response often spans a patchwork of tools, handoffs, and manual steps. An engineer gets paged, a team investigates the issue, the incident commander coordinates the response, SREs document decisions, and somebody (anybody!) writes the postmortem. Every handoff introduces more context switching, increasing the risk of critical information loss, and ultimately slowing resolution.

What DFIR Certification Should You Get First?

Your first digital forensics and incident response (DFIR) certification should match the investigations you want to run. If you want to examine Windows systems as a forensic analyst, start with FOR500 and the GIAC Certified Forensic Examiner (GCFE) exam. If you want a broader SOC analyst role first, a lower-cost practical credential such as BTL1 or PSAA is the better entry point. We compared five routes below: FOR500 toward GCFE, Centri BTL1, TCM Security PSAA, Hack The Box CDSA and CyberDefenders CCDL1. Each section covers pros, cons, why we picked it and the published price.

Run incident response in your FedRAMP High environment

Earlier this year, Datadog for Government achieved FedRAMP High certification, extending our GovCloud environment (US1-FED) to the federal government’s most sensitive civilian workloads. That certification now covers Datadog Incident Response, bringing paging, incident coordination, automation, and postmortem workflows into US1-FED. When a government system goes down, responders need to reach the right people, coordinate a fix, and keep stakeholders informed.

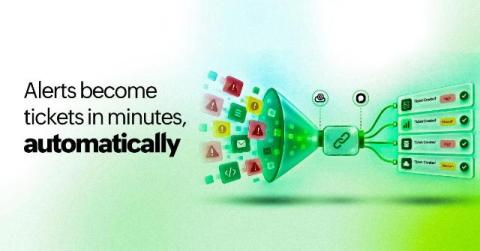
Site24x7 meets HaloITSM: Turn your monitoring alert into a HaloITSM ticket, automatically

Every IT incident response starts the same way. Something breaks, an alert fires, and someone has to act on it. The faster that chain completes, the better your team looks on the SLA reports and the less your users feel it. If you're using HaloITSM, a service desk platform built for enterprise IT operations, that chain now has one fewer link.

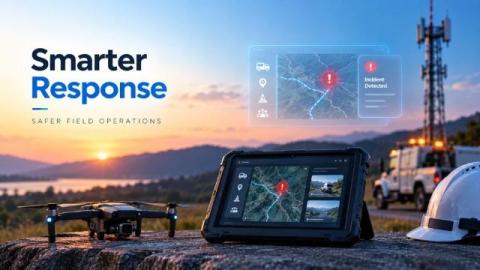
Building a Smarter Incident Response Framework for Field Operations

A field incident rarely arrives as a clean message explaining exactly what happened and what should happen next. It may begin with a vehicle stopping unexpectedly, a worker missing a check-in, a machine reporting unusual pressure, or a camera detecting movement inside a restricted area.

Incident Response Metrics Worth Tracking (Beyond MTTR)

Most engineering teams track exactly one incident response metric, and it is usually MTTR. It appears on the quarterly slide, it goes up or down by a few minutes, someone says "we need to bring that down," and nothing about the next incident changes. The problem is not that teams measure the wrong thing out of laziness. The problem is that incident response metrics are genuinely hard to design, and a single average duration is the easiest number to produce from an incident tracker.

Incident Chat and Virtual War Rooms: How to Improve Incident Response

How do you keep incident communication organized during a critical incident? Effective incident response requires more than getting an alert to the right person. Once responders are engaged, they need a shared place to exchange information, coordinate actions, and track decisions. A dedicated incident chat – or virtual incident war room – keeps that collaboration tied directly to the incident instead of scattering it across email, Microsoft Teams, Slack, text messages, and phone calls.

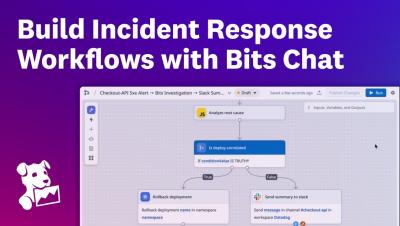
Build incident response workflows with Datadog Bits Chat

See how Bits Chat turns a natural-language request into an automated incident response workflow. In this demo, Bits Chat builds a workflow that investigates a monitor alert, identifies whether a recent deployment caused the issue, rolls it back when appropriate, and sends a summary to Slack.