Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Service Reliability Engineering and related technologies.

How Cortex can help SRE teams amplify their reach

Site reliability engineers can amplify their reach and influence across teams with Cortex in their toolbox. With the ability to define clear standards and drive progress, Cortex enables everyone at an organization to adopt an SRE mindset. Make sure to visit us at SREcon to learn more about how Cortex can serve as a single source of truth for your SRE team!
How We Define SRE Work, as a Team

Last year, I wrote How We Define SRE Work. This article described how I came up with the charter for the SRE team, which we bootstrapped right around then. It’s been a while. The SRE team is now four engineers and a manager. We are involved in all sorts of things across the organization, across all sorts of spheres. We are embedded in teams and we handle training, vendor management, capacity planning, cluster updates, tooling, and so on.

8 SRE Best Practices to Help Developers Troubleshoot Kubernetes

Maintaining reliable Kubernetes systems is not easy, especially for people who are not Kubernetes experts. This blog, part 2 of 3 in the “8 SRE Best Practices to Help Developers Troubleshoot Kubernetes” series, explains 8 simple best practices SREs can follow to help developers and other SREs build knowledge and effectively troubleshoot issues in applications running on Kubernetes.

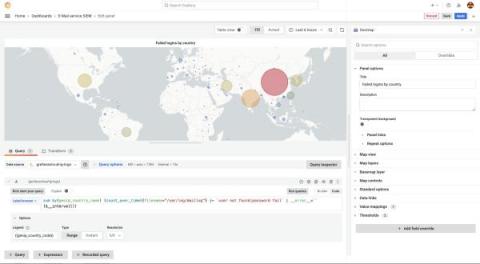
Protect PII and add geolocation data: Monitoring legacy systems with Grafana

Legacy systems often present a challenge when you try to integrate them with modern monitoring tools, especially when they generate log files that contain personally identifiable information (PII) and IP addresses. Thankfully, Grafana Cloud, which is built to work with modern observability tools and data sources, makes it easy to monitor your legacy environments too.

Datadog On Reliability Engineering

There are many different ways to implement Site Reliability Engineering (SRE). From team structures to roles and responsibilities to planning and prioritization flows, there’s no golden path for how to organize things. As Datadog has shifted from a startup to a quickly-growing public company, we’ve seen our own SRE practice evolve. With over 22,000 customers sending trillions of data points each day, keeping Datadog reliable is critical to our business.

Site Reliability Engineer: Responsibilities, Roles and Salaries

DevOps gained popularity in order to combat siloed workflows, decreased collaboration and a lack of visibility across the software development lifecycle. While establishing a culture of DevOps has helped teams collaborate better and deliver reliable software faster, DevOps teams don’t necessarily have someone specifically dedicated to developing systems that increase site reliability and performance. That’s where a site reliability engineer (SRE) comes into the picture.

SRE Report 2023: Findings From the Field - Toil

Toil. Few other words have the same visceral impact for SREs as their four-letter nemesis: toil. Although pretty much everyone recognizes and agrees that toil is bad, it is a term that is frequently misused in colloquial use. In common English usage, toil is defined as “long strenuous fatiguing labor”. As a term of art in the SRE profession, “toil” has several very specific characteristics which distinguish it from other sorts of work which people spend time on.