Operations | Monitoring | ITSM | DevOps | Cloud

DevOps vs. SRE: What's the Difference?

Despite there being significant differences in the roles, DevOps and Site Reliability Engineering are often lumped together because many people assume they do similar work. Although both attempt to reduce the issues arising from software development processes, their goals, skill sets, and approaches are actually quite different. DevOps engineers focus on the development pipeline, and their goal is to enable better development processes and workflows.
Sponsored Post

The Importance of Observability for Site Reliability Engineers (SREs)

Site reliability engineers (SREs) play a crucial role in ensuring the reliability of systems. From creating software to improving system reliability in production, responding to incidents, and fixing issues, SREs are responsible for guaranteeing the health of applications.. And observability helps support SREs'. Because an observable system allows them to identify and fix issues promptly, resulting in SRE's being better equipped to fast-track development cycles.

SRE vs DevOps: Can they coexist or do they compete?

Systems fail, sometimes publicly and at great cost. Airlines have experienced system-wide ticketing outages, causing hundreds of flight cancellations and significant inconvenience to customers. Retailers have experienced website crashes on the busiest shopping days of the year, costing millions in lost revenue and customer goodwill. It is vital to understand both DevOps and SRE and the roles they play in preventing such outages.

Using Observability with Kubernetes to Automate Site Reliability Engineering

In this video, Anthony Evans, solution architect, explains how the StackState topology-powered observability platform can help SREs to automate site reliability, putting their organizations on the path to becoming a zero-downtime enterprise. See how StackState helps to unify and correlate data across your stack, visualize your entire IT environment, instantly pinpoint root cause, reduce alert storms and with AIOps capabilities, even prevent problems proactively. It's all here!

What are the four Golden Signals?

When it comes to building reliable and scalable software, few organizations have as much authority and expertise as Google. Their Site Reliability Engineering Handbook, first published in 2016, details their practices to maintain reliability as Google scaled. But when you have over a million servers running thousands of services across more than twenty data centers, how do you monitor them in a consistent, logical, and relevant way?

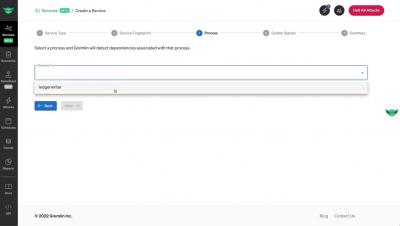
How to add a Golden Signal to a service in Gremlin RM

In this video, we show you how to add a Golden Signal to a service. Gremlin uses your Golden Signals to ensure your services are still healthy and responsive during reliability tests. You can configure Golden Signals to use an existing monitor in your observability tools, such as Datadog, New Relic, or Prometheus. We recommend adding all four Golden Signals to each of your services to ensure comprehensive coverage.