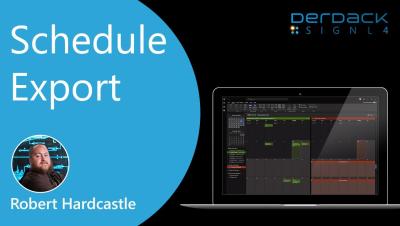
SIGNL4 Schedule Export
A short demo video on how to Export your SIGNL4 Schedule and import it into your personal calendar to help keep track of your scheduled shifts.


The latest News and Information on Incident Management, On-Call, Incident Response and related technologies.
Have you ever wondered about your IT team’s efficiency in detecting incidents? Your Mean Time to Detect (MTTD) is an incident management Key Performance Indicator (KPI) that reveals your productivity during the first stage of incident resolution and enables investigation into opportunities for improvement. ITOps and DevOps teams that can lower their MTTD can more quickly identify issues, minimize potential downtime, and maintain system reliability too.
A wise person once said, “What’s measured is what matters.” This couldn’t be more true than in the high-stakes world of IT operations, where the ability to swiftly measure, analyze, and respond to events is crucial for improving IT operational performance. This blog delves into defining IT event analytics, guiding you on getting started, showcasing real-world examples, and introducing essential methods to transforming your incident response strategy.
Constantly juggling IT incidents can be exhausting as you try to track and resolve them before they escalate into disruptions. With each incident demanding prompt and precise attention, keeping up takes significant work. However, you can manage these challenges more efficiently and with less stress and less risk by optimizing your incident-tracking process.
Although FireHydrant has spent five years focused on what happens after your team (erg, I mean service 🙄) gets paged, the topic of alerting often comes up in discussions with our community. People are tired of paying big bucks for software that’s expensive, bloated, and hasn’t seen much innovation. Clearly, there’s a problem here – and we’re tackling it head on.