Operations | Monitoring | ITSM | DevOps | Cloud

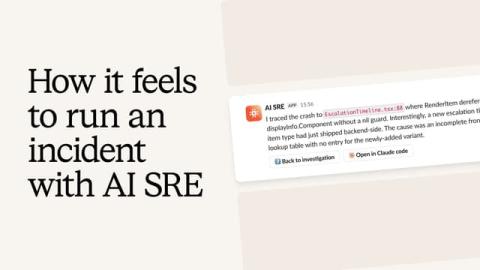
How it feels to run an incident with Investigations

We've been building the broader incident.io platform for several years now, and one thing we've learned is that UX matters more here than almost anywhere else. When an incident fires, there's no room for poorly designed interfaces or fumbling through features you haven't touched in a while — every second of the incident response lifecycle counts. The product has to be ergonomic: easy to pick up, easy to navigate, with the right things at your fingertips at exactly the right moment.
Why post-mortem action items die

You can run the best debrief of your life. Honest timeline, blameless tone, real insights. People leave the room nodding. And then nothing happens. This is the last mile problem of post-mortems - and it's an easy trap to fall into. When you've just been through a stressful incident, getting it back up is the priority. Once it's over, the post-mortem itself can feel like the finish line. You've documented what happened, been honest about it, identified what went wrong. It feels like the work is done.

How to migrate your paging tool without breaking your team

Most engineering teams don’t migrate their on-call and paging systems unless absolutely necessary. No matter how painful their current solution, it's one of those changes that people put off for as long as possible because the cost is real. The disruption, the retraining, the risk of missing a critical page during the transition. It's not something you do on a whim.

How Catalog changes the game for long-term maintenance

Every incident platform needs to know who owns what. Which team owns which service. Which backlog to send follow-ups to. Which escalation path to page when something breaks. The problem is that most platforms encode this ownership logic separately in every configuration: alert routing, workflows, ITSM ticket syncing, and more. Each one maintains its own copy of the same information, in its own format.

Beyond the pager: what to do when Opsgenie sunsets

OpsGenie is going away in 2027, forcing a migration decision for thousands of teams. But this isn't just a tooling swap — it's a rare chance to upgrade how you respond to incidents. Because the real pain in incident response isn’t paging. It’s everything that happens after the alert: coordination, clarity, communication, ownership, and follow-through. Most teams solve this through heroics and tool-juggling across chat, tickets, and docs. That approach doesn't scale.

incident.io product showcase: Post-mortems

A full walkthrough of our completely rebuilt post-mortems experience. We cover AI-generated first drafts from your incident data, accuracy review, inline rewriting, a collaborative editor with live incident context, meeting notes with Scribe, and management tooling including dashboards, exports, and analytics. Post-mortems are included in incident.io Response. AI features and Scribe are available on Pro and Enterprise plans.

Win by Being Bold

Everyone your sales team is reaching out to is drowning in emails. The way to cut through isn't to send more of them. It's to get personal, get creative, and get bold. That's the philosophy baked into incident.io's sales culture: experiment constantly, celebrate the inputs as much as the wins, and never play it safe. This video gives you a real look at what it's like to be part of a sales team at one of the most exciting startups right now. There are many more wins to come, and we want the right people here for them.

The post-mortem problem

Post-mortems are one of the most consistently underperforming rituals in software engineering. Most teams do them. Most teams know theirs aren't working. And most teams reach for the same diagnosis: the templates are too long, nobody has time, and nobody reads them anyway. These aren't wrong observations. But they're symptoms, not causes. The actual problem is that somewhere along the way, the post-mortem stopped being a piece of communication and became a compliance artifact.

Keeping it boring: the incident.io technology stack

At incident.io we run a deliberately simple technology stack. Keeping things boring has allowed us to scale from a few hundred customers to several thousand, while having only two platform engineers. In this post I'll walk through the stack, explain some of the choices we've made, and touch on the challenges we're facing as we grow.

Secure access at the speed of incident response

Picture this: it's 2am, your pager goes off, and you're staring at a production database that's on fire. You know exactly what's wrong. You know exactly how to fix it. But you can't touch anything because you're waiting on someone to approve your access request. Meanwhile, your customers are down, your SLAs are bleeding out, and you're refreshing Slack hoping someone in security is awake to click "approve." This is the incident response tax that too many teams pay.