I pulled every core-service outage AWS, Azure, and GCP published from January 2025 through September 2026 and measured what each deployment pattern would have saved.
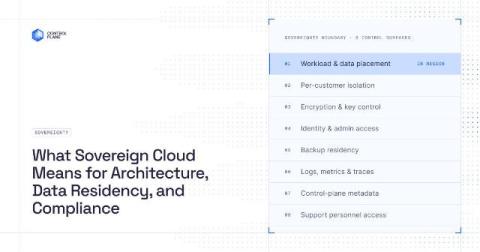
Sovereign cloud is a system design problem. It asks where workloads run, where data lives, who can administer the system, which legal authorities can compel access, who controls encryption keys, and where backups, telemetry, and control-plane metadata land. Selecting a region answers only part of that problem.
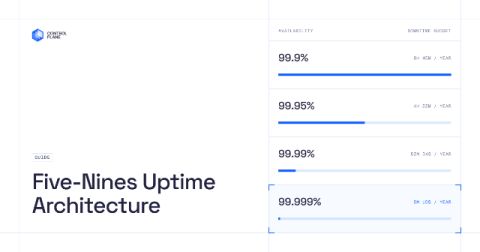
99.999% availability allows about 5 minutes 15 seconds of downtime per year, or about 26 seconds per month. That budget includes every failed deploy, certificate expiry, DNS misconfiguration, and provider incident in the request path. One regional outage lasting an hour consumes more than 11 years of five-nines budget. This guide explains which architecture tiers can reach that number, which cannot, and why.
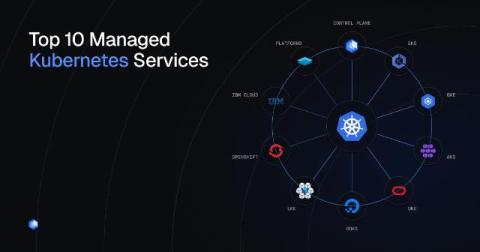
Kubernetes has become a standard foundation for modern containerized applications, but operating clusters still requires significant engineering work. In the CNCF’s 2025 annual cloud native survey, published in January 2026, 82% of container users reported running Kubernetes in production. As adoption matures, the question for many teams is no longer whether to use Kubernetes, but how much of the operational burden they want to own.
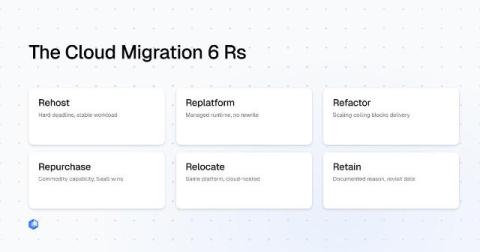
Consider a platform team that spends four months building a thorough migration plan. Its pilot, a stateless order-status API, runs on AWS within three weeks. Six months later, that API is still the only workload in the cloud. In this scenario, the blockers are not exotic technical failures.
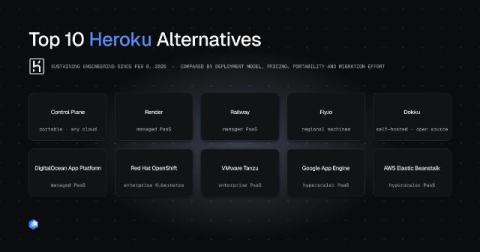
Heroku is not shutting down. On February 6, 2026, Heroku CPO Nitin T Bhat announced that the platform was moving to a sustaining engineering model: new feature development has stopped, but Heroku remains actively supported and production-ready. There is no announced EOL date or migration deadline, existing apps can keep running, credit-card customers can continue using the service, and existing Enterprise customers can renew. What changed is the roadmap, not immediate availability.
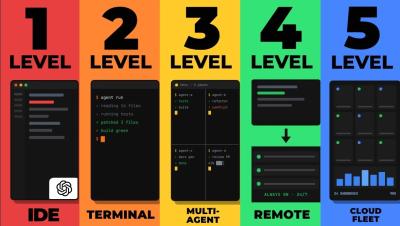
If you're trying to run more than a few AI coding agents at once, the real problem shifts from prompting to managing where they live and what they can reach. This video walks through the five levels of agent management, from the IDE all the way to a fleet running in the cloud with access to your own services.
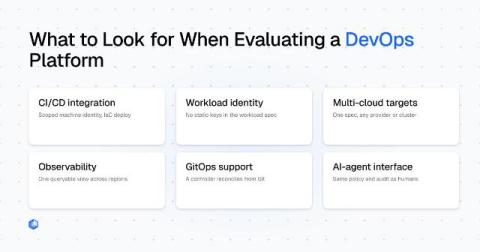
DevOps platform feature lists increasingly look alike. CI/CD, multi-cloud, observability, GitOps, and AI-friendly automation can all appear as checkboxes while the implementation burden still falls on your team. The useful signal appears when you ask how each capability actually works, what evidence a vendor can show, and which parts your team still has to build. Can pipelines authenticate with a scoped machine identity? Can workloads reach cloud APIs without static keys?
Kintsugi puts sales tax compliance on autopilot for 7,300 companies selling into 110 countries, and its tax engine sits inside other companies' checkouts. The answer has to arrive before the shopper finishes paying. "Typically, a customer's expectation is that we are returning the sales tax estimate on the invoice within 100 milliseconds." The cost of missing is not abstract: "For every minute that our sales tax API, if it ever goes down, our customers are not able to collect roughly $4 million in sales tax that they should be collecting.".
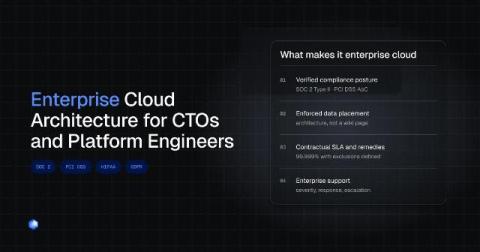
Most teams that say they have an enterprise cloud strategy mean that they have workloads running on a hyperscaler and a set of compliance controls documented somewhere. That is a cloud deployment, but it is not necessarily an enterprise cloud operating model. Google Cloud’s 2025 platform engineering research with ESG describes platform engineering as a strategic discipline tied to delivery, governance, and operational outcomes, rather than simply another infrastructure cost.