Operations | Monitoring | ITSM | DevOps | Cloud

How AI Agents Work in a Software Factory

I built a small software factory: I file a Linear ticket, and a coding agent spins up in its own cloud sandbox, fixes the bug, pushes a branch and reports back. I can watch it work or take over from my laptop using my normal dev setup. In this video I walk through every piece of it in plain terms, from ticket to pushed branch, and explain why I made each decision so you can build your own.
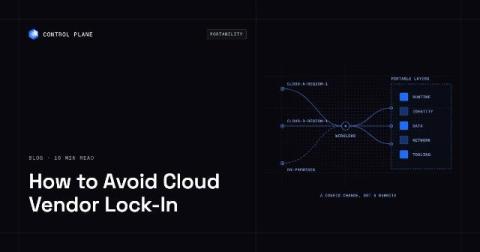
How to Avoid Cloud Vendor Lock-In: A Practical Guide for 2026

You avoid cloud vendor lock-in by keeping the parts that are expensive to move portable: the compute runtime, identity, data, networking, and deployment tooling. You accept proprietary services only where their value clearly exceeds the exit cost, so that leaving or adding a provider is a configuration change rather than a rewrite.

What Infrastructure Do You Need to Run an Inference Layer? A Production Guide

A production inference layer needs GPU compute sized to the model, a serving runtime such as vLLM or SGLang, orchestration that autoscales on queue depth, one endpoint with health-aware routing and failover, model weights cached near the GPUs, and observability, security, and cost controls.

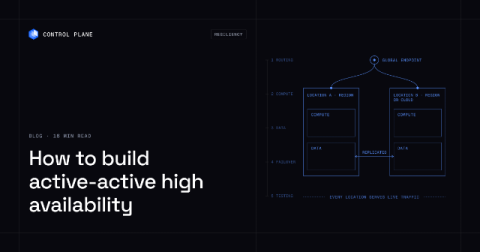
How to Build Active-Active High Availability Across Regions and Clouds

Active-active means two or more locations serve live traffic at the same time, with the application running in each and its data replicated across them, so no location sits idle waiting for a failover. You build it in five layers, and data is the hardest.

How to Add a Neocloud to AWS or GCP Without Running a Second Stack

There is no single best neocloud for AWS or GCP teams. The right one depends on the workload. Bursty fine-tuning and batch jobs reward flexible billing and low hourly rates. Always-on inference and agents reward capacity you can keep plus a second place to run, and data-heavy pipelines reward cheap data movement.

What Is High Availability? How It Works and How Many Nines You Actually Need

High availability (HA) is a system’s ability to keep serving users when individual components fail, from a single server up to a whole cloud region or provider. It is measured in nines: 99.9% allows about 8 hours 46 minutes of downtime a year, 99.99% about 52 minutes, and 99.999% about 5 minutes 15 seconds. HA works by removing single points of failure through redundancy, health checks, automatic failover, and replicated data.