Operations | Monitoring | ITSM | DevOps | Cloud

The 10 Best MCP Servers for DevOps and Cloud Infrastructure in 2026

The best MCP servers for DevOps depends on what you want an AI assistant to do: read code and pipelines, plan infrastructure as code, call one cloud’s APIs, observe production, or deploy and operate workloads. The safest setups combine scoped permissions, a read-only mode for investigation, confirmation before destructive actions, and an audit trail of every change.
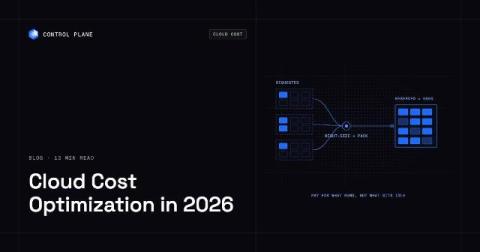
Cloud Cost Optimization in 2026: 10 Levers That Cut Your Compute Bill

Most cloud compute waste comes from paying for capacity your workloads do not use: over-provisioned requests, idle nodes, standby capacity, and per-service add-ons. The biggest savings come from changing how capacity is reserved and packed, not only from discounts or dashboards.

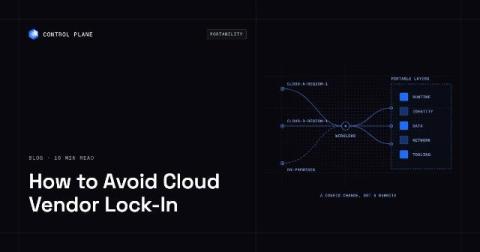
How to Avoid Cloud Vendor Lock-In: A Practical Guide for 2026

You avoid cloud vendor lock-in by keeping the parts that are expensive to move portable: the compute runtime, identity, data, networking, and deployment tooling. You accept proprietary services only where their value clearly exceeds the exit cost, so that leaving or adding a provider is a configuration change rather than a rewrite.

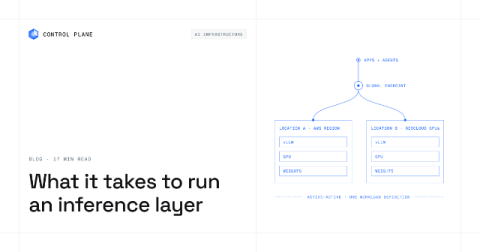
What Infrastructure Do You Need to Run an Inference Layer? A Production Guide

A production inference layer needs GPU compute sized to the model, a serving runtime such as vLLM or SGLang, orchestration that autoscales on queue depth, one endpoint with health-aware routing and failover, model weights cached near the GPUs, and observability, security, and cost controls.

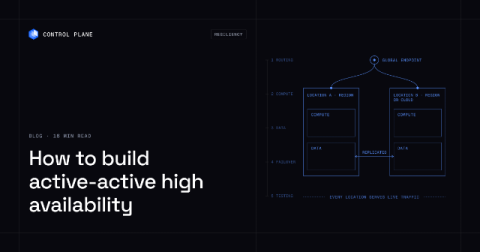
How to Build Active-Active High Availability Across Regions and Clouds

Active-active means two or more locations serve live traffic at the same time, with the application running in each and its data replicated across them, so no location sits idle waiting for a failover. You build it in five layers, and data is the hardest.

How to Add a Neocloud to AWS or GCP Without Running a Second Stack

There is no single best neocloud for AWS or GCP teams. The right one depends on the workload. Bursty fine-tuning and batch jobs reward flexible billing and low hourly rates. Always-on inference and agents reward capacity you can keep plus a second place to run, and data-heavy pipelines reward cheap data movement.