What Infrastructure Do You Need to Run an Inference Layer? A Production Guide
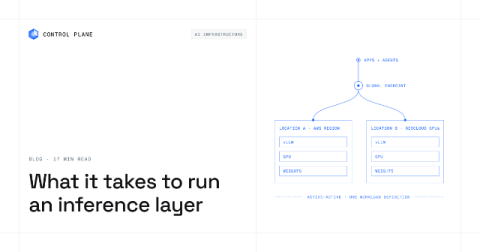
A production inference layer needs GPU compute sized to the model, a serving runtime such as vLLM or SGLang, orchestration that autoscales on queue depth, one endpoint with health-aware routing and failover, model weights cached near the GPUs, and observability, security, and cost controls.