Operations | Monitoring | ITSM | DevOps | Cloud

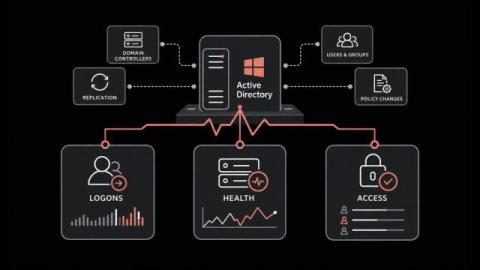
What to Monitor in Active Directory to Keep Logons Fast and Access Under Control

Why do logons crawl at one branch while headquarters is fine, or an admin group gain a member nobody approved, and no alert says a word? Trace any of those back far enough and you usually reach Active Directory. Since email, VPN, file shares and line-of-business software all lean on it for credentials, a directory fault rarely looks like itself and tends to show up as a network outage or a bug in some other application. Most of these faults creep in.
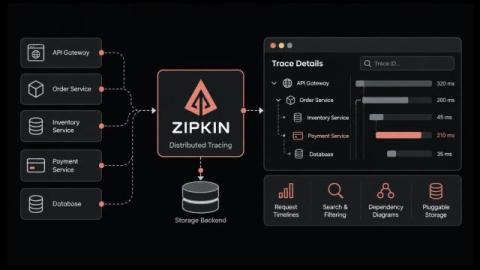
What is Zipkin and How does Distributed Tracing Speed Up Incident Resolution

If a checkout slows down or an API call fails, why can the cause stay hidden for so long while every service dashboard looks fine? One customer click in a microservices setup may hit a gateway and a few backend services first, then a queue or a database. Every hop logs its own events, yet none of those logs points back to the original request. Distributed tracing was created to solve exactly this. Zipkin arrived early, as one of the first open-source tracers.

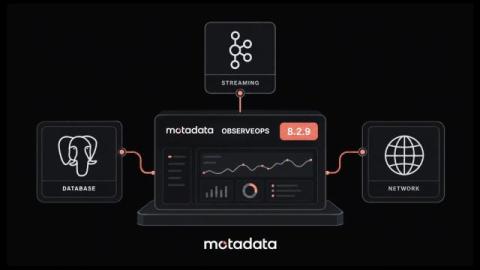
What's New in Motadata 8.2.9 as ObserveOps Expands Database, Streaming and Network Coverage

How often does a lagging replica or a bad network link reach users before your monitoring flags it? The problem grows when every layer has its own tool. Warning signs then show up in different places, often too late to act on. Motadata 8.2.9 came out on October 5, 2026, with eight updates to Motadata ObserveOps. Four of them focus on the network. The other four deal with databases, data streaming, alerting and SEBI compliance reporting. A few add support for technologies Motadata did not cover before.

DNS Monitoring: What to Track and Where to Watch It From

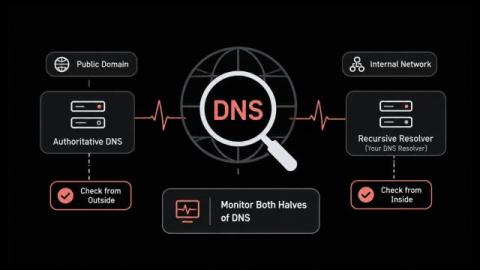
DNS monitoring asks your name servers the same question on a timer and checks the answer that comes back. Most teams aim it at their public domain and stop there. That covers half the problem. Your public domain and your internal resolver fail in different ways. A check from outside the building never sees the second one. In this blog, you'll see: By the end you'll know which half of your DNS nobody is watching. A DNS check sends a query and reads the reply. The reply can fail three ways.

What a Patch Management Policy Should Contain to Keep Systems Secure and Audit-Ready

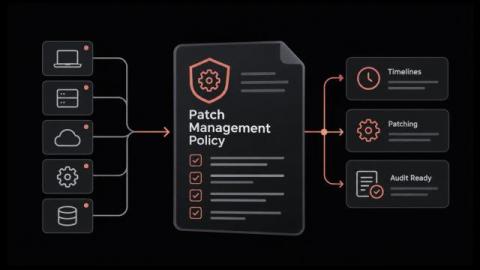
Who decides how fast a critical patch goes out, and who signs off when a production server can't be restarted? For many IT groups, the answer is a mix of one senior admin's judgment, an old ticket and a shared spreadsheet. It holds up fine right until an auditor asks for proof, or that admin leaves. A written policy replaces that guesswork with rules people have agreed to. Owners are named, deadlines are fixed, and there's a plan for the system that can't be patched on time.

Logging as a Service (LaaS): What It Costs and When It Fits

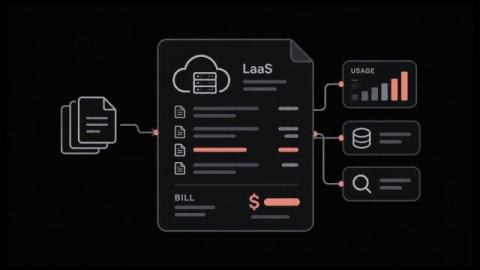
Logging as a Service moves your log management to a provider. They collect, parse, store and search your logs for a monthly fee. The fee is where it goes wrong. Providers meter five different things, and the one written into your contract decides whether ordinary growth doubles your bill. In this blog, you'll see: By the end you'll know which meter your workload lands on. Logging as a Service is a cloud-delivered model for collecting and searching logs.

WAN Link Monitoring for Faster Branch Troubleshooting

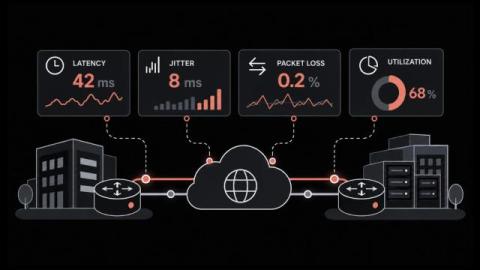
Why do users at a branch complain about choppy calls and stalled apps when every WAN circuit on the dashboard still shows up? A link can be reachable without being healthy. Delay and packet loss can rise for hours on a live circuit, and a simple up-or-down check will report nothing unusual the whole time. WAN link monitoring checks the quality of each site-to-site connection by having routers send their own test packets and time the replies.

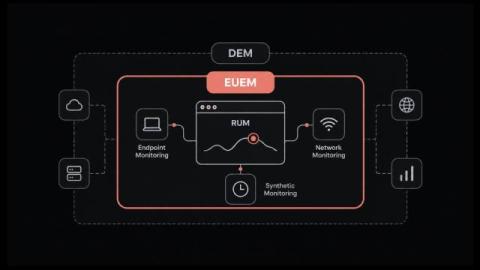
What is End User Experience Monitoring (EUEM)? How It Relates to RUM and DEM

Why do tickets about a slow application keep arriving while every server, link and service check reports normal? That mismatch is the problem end user experience monitoring exists to solve. A healthy server is one thing, but the business notices something else: whether people can finish their work or complete a purchase without delays or errors. Monitoring in most IT operations groups was built to watch the systems from the inside, so it reports CPU load, memory and uptime.

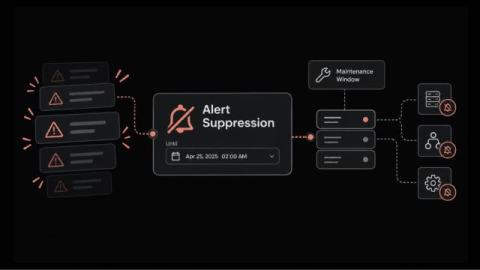
How Alert Suppression Pauses Alerts During Planned Work Without Losing Visibility

How many pages did your on-call engineer get during the last planned firmware upgrade on a core switch? The device stops responding and every dependent check fails. Soon the on-call phone is buzzing with alerts for a change that was approved last week. Alert suppression is a time-limited pause on alerts for a condition you already know about, such as planned work or an issue under investigation. And what is alert suppression from the engineer's side of the console?

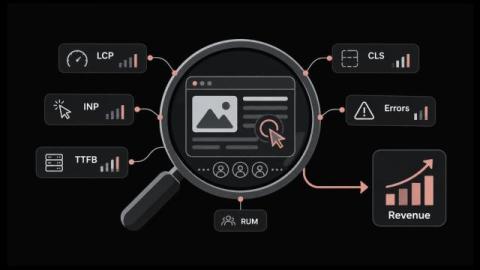
RUM Metrics That Matter for User Experience and Revenue

Why does a page that scores well in testing still draw complaints from customers about slowness? A lab test runs on one fast machine over a stable connection. Customers use older phones, congested mobile networks and browsers loaded with extensions, so their experience can only be measured on their own devices. Real user monitoring captures that experience, and it produces a long list of measurements.